<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://kraghavan.ca/feed.xml" rel="self" type="application/atom+xml" /><link href="https://kraghavan.ca/" rel="alternate" type="text/html" /><updated>2026-07-26T05:27:32+00:00</updated><id>https://kraghavan.ca/feed.xml</id><title type="html">Karthika Raghavan</title><subtitle>Engineering blog on distributed systems, LLM infrastructure, and observability</subtitle><author><name>Karthika Raghavan</name></author><entry><title type="html">What Is LLM-as-a-Judge, Really? A Field Guide to the State of the Art in 2026</title><link href="https://kraghavan.ca/llm-infrastructure/evaluation/2026/07/25/llm-as-a-judge-field-guide.html" rel="alternate" type="text/html" title="What Is LLM-as-a-Judge, Really? A Field Guide to the State of the Art in 2026" /><published>2026-07-25T00:00:00+00:00</published><updated>2026-07-25T00:00:00+00:00</updated><id>https://kraghavan.ca/llm-infrastructure/evaluation/2026/07/25/llm-as-a-judge-field-guide</id><content type="html" xml:base="https://kraghavan.ca/llm-infrastructure/evaluation/2026/07/25/llm-as-a-judge-field-guide.html"><![CDATA[<p>Let me be honest about how this post happened, because it’s a better story than the post itself.</p>

<p>I wanted to learn LLM-as-a-judge properly — not “yeah, you use an LLM to grade another LLM’s output” properly, but actually understand where it came from, where it breaks, and what people smarter than me are doing about it. And since I’d just spent a week writing a reactive hot-take about someone else’s product launch and gotten (correctly) called out for having zero citations and zero original insight, I decided to do this one right: real research, real sources, and if I was going to claim something novel, it had to survive someone actively trying to kill it.</p>

<p>So I spun up a small army of research agents. Six of them went and surveyed the field — foundations, biases, calibration, mitigations, the 2025-2026 frontier, and how it’s actually used in production. Then a synthesis pass consolidated all of that into five candidate “gaps” in the current toolkit. Then I had agents develop each gap into a concrete, technically-grounded proposal. Then — and this is the part that actually taught me something — I had three independent skeptics per proposal try to refute each one: find the prior art, poke the mechanism, default to “this doesn’t survive” unless proven otherwise.</p>

<p>All five proposals died. Every single one. Not because the ideas were bad — the mechanisms were sound — but because someone had already published almost exactly the same thing, in some cases within the last twelve weeks. I’ll walk through the wreckage later in this post, because it turned out to be the most useful part of the whole exercise. But first, the actual field guide, because that’s what I came here to learn.</p>

<hr />

<h2 id="1-what-is-llm-as-a-judge">1. What Is LLM-as-a-Judge?</h2>

<p>Picture a professor with 50,000 essays to grade by Friday. They can’t read all of them — nobody can. So they hire a teaching assistant: someone smart, fast, and (crucially) consistent, who reads a rubric once and then applies it identically to essay #1 and essay #49,999. The TA isn’t the professor. The TA can be wrong, tired, biased toward students who write in a font the TA likes, or unable to tell a genuinely brilliant unconventional answer from a well-formatted one that says nothing. But the TA is fast enough that grading actually finishes, and reliable enough — most of the time — that the grades mean something.</p>

<p>LLM-as-a-judge is that TA, and the “essays” are LLM outputs: chatbot responses, RLHF preference pairs, agent trajectories, summaries, code. Instead of a human rater or a fixed answer key, you prompt an LLM to score or compare outputs — pointwise (“rate this 1-10”), pairwise (“which of these two is better”), or via a rubric (“does this satisfy criteria A, B, and C”). The judge doesn’t need to be a different model than the one being graded, though — as we’ll get to — that turns out to matter a lot.</p>

<figure style="max-width:640px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-as-judge/LLM-as-Judge.png" alt="LLM-as-a-Judge system diagram" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">The judge sits between candidate outputs and a verdict. The human rater doesn't disappear — it moves to a gold-set spot check.</figcaption>
</figure>

<h2 id="2-why-it-had-to-exist">2. Why It Had to Exist</h2>

<p>Two gaps forced this into existence, and both are obvious in hindsight.</p>

<p><strong>Gap one: the old metrics don’t work for open-ended text.</strong> BLEU and ROUGE — the classic n-gram overlap metrics — were built for machine translation, where there’s a roughly “correct” answer to compare against. They fall apart on summarization, dialogue, or anything with legitimate diversity of good answers. <a href="https://arxiv.org/abs/2303.16634">G-Eval</a> (Liu et al., Microsoft, EMNLP 2023) showed that GPT-4, prompted with chain-of-thought reasoning and a structured “form-filling” scoring template, correlated with human judgment far better than any n-gram metric — 0.514 Spearman correlation on summarization, a genuinely large jump.</p>

<p><strong>Gap two: human evaluation doesn’t scale to how fast models ship.</strong> Getting crowdworkers to rate thousands of response pairs for every RLHF iteration or every weekly model release is slow and expensive. <a href="https://arxiv.org/abs/2305.14387">AlpacaFarm</a> (Stanford, NeurIPS 2023) and its successor <a href="https://github.com/tatsu-lab/alpaca_eval">AlpacaEval</a> showed that LLM auto-annotators could substitute for human preference labeling at roughly <strong>50x lower cost</strong>, with high agreement — enough to actually run RLHF-style method development without a standing army of human raters.</p>

<p>Put those together and you get the pitch: an evaluator that’s fast enough to keep up with iteration speed, and correlated enough with humans to be trustworthy. Emphasis on “enough” — we’ll spend a lot of this post on the gap between “enough” and “always.”</p>

<h2 id="3-the-papers-that-built-the-field">3. The Papers That Built the Field</h2>

<table>
  <thead>
    <tr>
      <th>Year</th>
      <th>Work</th>
      <th>What it established</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>2022</td>
      <td><a href="https://arxiv.org/abs/2212.08073">Constitutional AI</a> (Anthropic)</td>
      <td>An AI judge, guided by written principles, evaluates response pairs to build a preference model — the origin of “RLAIF”</td>
    </tr>
    <tr>
      <td>2023</td>
      <td><a href="https://arxiv.org/abs/2303.16634">G-Eval</a></td>
      <td>Chain-of-thought + form-filling scoring beats n-gram metrics on open-ended generation</td>
    </tr>
    <tr>
      <td>2023</td>
      <td><a href="https://arxiv.org/abs/2305.14387">AlpacaFarm</a> / <a href="https://github.com/tatsu-lab/alpaca_eval">AlpacaEval</a></td>
      <td>LLM auto-annotators as a ~50x cheaper substitute for human preference labeling</td>
    </tr>
    <tr>
      <td>2023</td>
      <td><a href="https://arxiv.org/abs/2306.05685">MT-Bench &amp; Chatbot Arena</a> (Zheng et al., NeurIPS)</td>
      <td>Formalized the term “LLM-as-a-judge”; GPT-4 judges hit &gt;80% agreement with humans — but so do the biases</td>
    </tr>
    <tr>
      <td>2023</td>
      <td><a href="https://arxiv.org/abs/2309.00267">RLAIF</a> (Google)</td>
      <td>LLM-judge-trained reward models match human-feedback RLHF on real tasks</td>
    </tr>
    <tr>
      <td>2023</td>
      <td><a href="https://arxiv.org/abs/2308.03688">AgentBench</a></td>
      <td>Establishes agent evaluation (multi-step trajectories) as distinct from static QA</td>
    </tr>
    <tr>
      <td>2024</td>
      <td><a href="https://arxiv.org/abs/2403.13787">RewardBench</a> (Ai2)</td>
      <td>First dedicated benchmark for reward models — the judges quietly steering every RLHF pipeline</td>
    </tr>
    <tr>
      <td>2024</td>
      <td><a href="https://arxiv.org/abs/2404.04475">Length-Controlled AlpacaEval</a></td>
      <td>Fixes AlpacaEval’s length bias; correlation with Arena jumps from 0.94 to 0.98</td>
    </tr>
    <tr>
      <td>2024</td>
      <td><a href="https://arxiv.org/abs/2403.04132">Chatbot Arena paper</a></td>
      <td>Live, crowdsourced human pairwise votes at scale — the non-LLM cross-check the field still relies on</td>
    </tr>
  </tbody>
</table>

<p>Notice the shape of this timeline: 2022-2023 is “does this work at all” (yes, roughly). 2024 onward is “okay, now fix the ways it doesn’t.” We’re still deep in the second phase, and it’s accelerating, not slowing down.</p>

<h2 id="4-where-its-actually-used-today">4. Where It’s Actually Used Today</h2>

<p>LLM-as-a-judge isn’t a research curiosity — it’s load-bearing infrastructure in three distinct lanes.</p>

<p><strong>Model release evaluation.</strong> Meta’s <a href="https://arxiv.org/abs/2407.21783">Llama 3 technical report</a> documents model-graded scoring (correctness, informativeness) running alongside human eval during post-training. OpenAI’s open-source <a href="https://github.com/openai/evals"><code class="language-plaintext highlighter-rouge">evals</code></a> framework standardizes “model-graded” templates as a first-class evaluation primitive, and their <a href="https://developers.openai.com/api/docs/guides/graders">grading guidance</a> explicitly recommends using a <em>different, typically stronger</em> model as judge than the one being graded — a direct, practitioner-level acknowledgment of self-preference bias.</p>

<p><strong>RLHF/RLAIF alignment pipelines.</strong> This is the highest-stakes lane: the judge’s verdict <em>becomes the training signal</em>. Anthropic’s Constitutional AI pipeline and Google’s RLAIF work both use LLM judges to generate the preference data that trains the reward model driving RL. If the judge is subtly wrong here, the model gets optimized toward the judge’s blind spots, not the user’s actual preferences — quietly, and at scale.</p>

<p><strong>Production engineering pipelines.</strong> This is where the culture is most mature, and most honest about limitations. Anthropic runs a <a href="https://www.anthropic.com/engineering/multi-agent-research-system">single-call rubric judge</a> inside its multi-agent research system but keeps human testers around for the failure modes the judge misses. Google’s Vertex AI AutoSxS ships response-flipping and multi-sampling as built-in bias controls, plus an <a href="https://cloud.google.com/vertex-ai/docs/generative-ai/models/side-by-side-eval">official notebook</a> for checking the autorater against human preference data <em>before</em> trusting it. Scale AI’s SEAL leaderboards pair private human-curated gold sets (~1,000 examples) with LLM grading for scale. Databricks <a href="https://www.databricks.com/blog/databricks-announces-significant-improvements-built-llm-judges-agent-evaluation">publishes its actual validation numbers</a> — Krippendorff’s alpha of 0.565-0.698, Cohen’s kappa around 0.64-0.65 — rather than just claiming the judge “works.” And the widely-followed practitioner playbook from <a href="https://hamel.dev/blog/posts/llm-judge/index.html">Hamel Husain</a> and <a href="https://www.braintrust.dev/articles/how-to-eval">Braintrust</a> is refreshingly unglamorous: label ~30 examples by hand, iterate the judge prompt against your own disagreements with it, prefer binary pass/fail over Likert scales, and <em>never fully retire the human reviewer</em> — just shrink their workload via sampling.</p>

<p>That last point is the tell. Nobody serious treats the judge as ground truth. They treat it as a fast, cheap, imperfect proxy that needs a human-labeled leash.</p>

<h2 id="5-the-bias-zoo">5. The Bias Zoo</h2>

<p>Here’s where it gets genuinely funny, in a “I can’t believe this is the state of the art” way.</p>

<p><strong>Position bias.</strong> Judges systematically favor whichever answer is shown first (or second — it’s judge-dependent). <a href="https://arxiv.org/abs/2305.17926">Wang et al.</a> demonstrated you could make Vicuna-13B beat ChatGPT on <strong>66 of 80 test queries</strong> purely by swapping which answer appeared first — no change to either model’s actual output. A later large-scale study across <a href="https://arxiv.org/abs/2406.07791">15 judges and 150,000+ evaluations</a> confirmed it’s real, judge- and task-dependent, and driven more by how close the two answers are in quality than by anything about length.</p>

<p><strong>Verbosity bias.</strong> Longer answers get rated higher, independent of whether the extra length adds anything. This was bad enough that AlpacaEval needed a dedicated length-control regression just to stop measuring “which model rambles more” instead of “which model is better.” Interestingly, this one isn’t universal: <a href="https://arxiv.org/abs/2604.23178">recent work</a> shows Gemini- and Llama-family judges prefer longer answers, Claude-family judges actually prefer <em>shorter</em> ones, and GPT-4o sits roughly neutral. Your bias-mitigation strategy needs to know which judge you’re running.</p>

<p><strong>Self-preference bias.</strong> Judges rate their own model family’s outputs higher — <a href="https://arxiv.org/abs/2410.21819">Wataoka &amp; Takahashi</a> tie this to <em>perplexity</em>: the judge seems to conflate “text I find familiar/predictable” with “text that’s good,” which is a fairly damning thing to discover about your quality metric.</p>

<p><strong>Format bias, and this is the punchline.</strong> A <a href="https://tianpan.co/blog/2026-04-27-llm-judge-bias-audit-length-position-format">2026 analysis</a> quantified judges’ preference for markdown formatting — headers, bullets, code blocks — over plain prose with <em>identical content</em>, at an effect size of <strong>0.76-0.92</strong>. For comparison, position bias in the same analysis measured <strong>≤0.04</strong>. Format bias isn’t a minor confound sitting next to position bias — it dwarfs it by roughly 20x. And it’s not just incidental: a <a href="https://arxiv.org/abs/2605.26156">2026 adversarial paper</a> shows you can learn, via bandit search, exactly which formatting tweaks most reliably flip a judge’s verdict, independent of content quality. If your eval pipeline isn’t stripping markdown before comparing responses, you are, to a significant degree, benchmarking who writes the prettiest bullet points.</p>

<figure style="max-width:640px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-as-judge/measured_bias.png" alt="Bar chart of measured bias effect sizes across LLM judges" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">Format bias isn't a minor footnote next to position bias — it's roughly 20x larger.</figcaption>
</figure>

<p>A broader <a href="https://arxiv.org/abs/2410.02736">CALM framework study</a> catalogs <strong>12 distinct bias categories</strong> — bandwagon effects, authority bias, sentiment bias, distraction bias, chain-of-thought bias, and more — and finds even the strongest judge models retain measurable bias on specific tasks. This is not a solved problem with a couple of known footguns. It’s an active taxonomy.</p>

<h2 id="6-where-judges-fall-off-a-cliff">6. Where Judges Fall Off a Cliff</h2>

<p>Bias is embarrassing. Domain collapse is worse, because it means the judge isn’t measuring the thing you think it’s measuring at all.</p>

<p>On <strong>factual consistency in summarization</strong>, GPT-3.5-class judges show only 0.3-0.6 correlation with human judgment (versus 0.8-0.9 for human experts), and miss 40-70% of factually inconsistent summaries outright — while maintaining high <em>specificity</em>, meaning they confidently pass bad summaries rather than obviously flailing.</p>

<p>On <strong>humor</strong>, it’s almost slapstick: LLM judges rated irrelevant, nonsensical responses as <em>highly funny</em> (mean scores 2.18-3.29 on a scale where humans rated the same content 0.681) — <a href="https://arxiv.org/html/2604.19786v1">Spearman correlation with human funniness ratings sat at 0.169-0.266</a> across Claude Sonnet 4, GPT-4.1, and Gemini 2.5 Pro. To be fair, humans don’t agree with each other about what’s funny either (31.7% pairwise agreement) — but the judges tracked human consensus only ~52-58% of the time, which is barely better than a coin flip on top of an already-noisy target.</p>

<p>On <strong>safety judgment</strong>, the numbers get genuinely concerning. A study found LLM safety judges reaching <em>near-zero or negative</em> Krippendorff’s alpha on “operational misuse” harm categories — meaning the raw agreement numbers looked fine only because of label imbalance, not real signal — with identical queries labeled “safe” anywhere from <strong>12% to 83% of the time</strong> depending purely on which model did the judging.</p>

<p>On <strong>clinical/global-health content</strong>, even the best-performing judge (Claude Opus-class) reached human-equivalent performance on only <strong>4 of 11</strong> evaluation criteria, and degraded further outside English.</p>

<p>And there’s a meta-point that ties all of this together: raw correlation or percent-agreement can <em>overstate</em> reliability, because it doesn’t correct for chance agreement on skewed labels. A large benchmark called <a href="https://arxiv.org/abs/2510.09738">“Judge’s Verdict”</a>, using Cohen’s Kappa across 54 judge configurations, found only <strong>27 of 54</strong> actually showed genuinely human-like agreement patterns once chance was properly subtracted out. Half the field’s “reliable” judges are, statistically, a coin flip with good PR.</p>

<h2 id="7-when-judges-get-attacked-on-purpose">7. When Judges Get Attacked on Purpose</h2>

<p>Everything above is what happens when nobody’s trying to break the judge. Things get worse fast once someone is.</p>

<p><a href="https://arxiv.org/abs/2507.08794">One paper</a> titled, with admirable bluntness, “One Token to Fool LLM-as-a-Judge,” showed that trivial adversarial tokens can fool even frontier reasoning-model judges like o1 and Claude-4-class reward models. Under <a href="https://arxiv.org/html/2607.05904">self-play optimization pressure</a>, reference-free judges reward-hack toward responses that are <em>more convincing</em> rather than <em>more correct</em> — the gap between judge-approval rate and actual accuracy widened to <strong>0.74</strong>, and critically, this transfers across model families and <strong>survives a three-judge ensemble</strong>, which still accepted the hacked, wrong answers 55% of the time. Ensembling three judges sounds like a safety margin. It bought almost nothing.</p>

<p>Under <a href="https://arxiv.org/html/2603.06594">adversarial/jailbreak distribution shift</a>, safety judges collapse to <strong>AUROC ~0.48</strong> — genuinely indistinguishable from random guessing. And there’s a subtler contamination problem called <a href="https://arxiv.org/abs/2502.01534">“preference leakage”</a>: judges show systematic bias toward outputs from “student” models related to the judge’s own training lineage, which is exactly the kind of thing that quietly corrupts a benchmark leaderboard without anyone noticing until someone goes looking.</p>

<figure style="max-width:640px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-as-judge/self-play-training-iterations.png" alt="Line chart showing the judge-truth gap widening under self-play optimization" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">Judge-approval rate climbs to 94% while true accuracy sits flat around 20% — and a 3-judge ensemble still accepted the hacked answers 55% of the time.</figcaption>
</figure>

<p>The throughline: everything in Section 5 (position, verbosity, self-preference, format bias) is a judge being <em>imprecise</em>. Everything in this section is a judge being <em>actively exploitable</em> — which matters enormously once you remember that RLAIF pipelines use judge verdicts as a training reward signal. An exploitable reward signal doesn’t just misjudge outputs. It teaches the next model exactly how to game it.</p>

<h2 id="8-the-mitigation-toolkit-ranked-by-how-solved-it-actually-is">8. The Mitigation Toolkit, Ranked by How Solved It Actually Is</h2>

<p><strong>Mature and widely deployed:</strong></p>
<ul>
  <li><strong>Chain-of-thought + form-filling</strong> (G-Eval): make the judge reason before scoring, not just spit out a number.</li>
  <li><strong>Reference-guided grading</strong>: have the judge solve the problem itself first, then grade against its own solution. MT-Bench’s authors showed this cut math-grading failure from <strong>~70% to ~15%</strong> — the single biggest before/after number in this entire post.</li>
  <li><strong>Position-swap / order randomization</strong>: run the comparison both ways, only trust verdicts that agree. Standard in MT-Bench methodology and Vertex AI AutoSxS.</li>
  <li><strong>Rubric decomposition</strong>: score independent sub-criteria instead of one holistic verdict — more interpretable, harder to game wholesale.</li>
</ul>

<p><strong>Popular, but with known blind spots:</strong></p>
<ul>
  <li><strong>Panel of LLM evaluators (PoLL) / juries</strong>: diverse judges canceling out idiosyncratic bias. Cheaper than one giant judge, and reduces self-enhancement bias — <em>if</em> the panel is genuinely diverse.</li>
  <li><strong>Multi-agent debate</strong> (<a href="https://arxiv.org/abs/2308.07201">ChatEval</a>): persona-diverse agents argue before verdicting. The catch, straight from ChatEval’s own ablation: the gains <strong>vanish</strong> with homogeneous personas.</li>
  <li>The blind spot both share: a <a href="https://arxiv.org/html/2605.29800">2026 study</a> titled “Nine Judges, Two Effective Votes” showed that correlated errors across same-family judges mean a 9-judge panel can carry the <em>independent information content of only ~2 effective votes</em>. Ensembling doesn’t buy you what it looks like it buys you unless you actually measure and select for independence.</li>
</ul>

<p><strong>Newest, least production-hardened:</strong></p>
<ul>
  <li><strong>RL-trained “thinking” judges</strong> (<a href="https://arxiv.org/abs/2504.00050">JudgeLRM</a>, <a href="https://arxiv.org/abs/2505.10320">J1</a>): reasoning-trained judges outperforming much larger SFT-only judges, with meaningful multilingual accuracy gains.</li>
  <li><strong>Calibration/uncertainty quantification</strong>: linear probes on judge hidden states (cheaper and better-calibrated than asking the judge to state its own confidence), TH-Score ensemble fusers, and trust-or-escalate cascades that fall back to a stronger judge (or a human) when confidence is low.</li>
  <li><strong>Constitutional-lineage rubric judges</strong>: Anthropic’s Constitutional Classifiers, now <a href="https://arxiv.org/pdf/2601.04603">Constitutional Classifiers++</a> (Jan 2026), pairing written principles with rubric-generation to bridge human policy and machine reward.</li>
</ul>

<p><strong>The de facto industry standard, and it isn’t a technique at all — it’s a validation habit:</strong> benchmark your judge against a small human-labeled gold set using <em>chance-corrected</em> agreement (Cohen’s kappa or Krippendorff’s alpha — not raw percent agreement, which lies to you on skewed labels), iterate the judge prompt against your own disagreements with it, prefer binary over Likert, and never fully retire the human reviewer. Every credible production pipeline in this post does some version of this. None of them skip it.</p>

<h2 id="9-the-honest-interlude-i-tried-to-find-you-something-novel">9. The Honest Interlude: I Tried to Find You Something Novel</h2>

<p>Here’s the part I promised at the top. I had five grounded, technically-sound proposals, each targeting a genuine gap the survey surfaced. I had three independent skeptic agents try to kill each one — find prior art, poke the mechanism, default to “no” unless proven otherwise. Here’s the body count:</p>

<table>
  <thead>
    <tr>
      <th>My proposal</th>
      <th>The idea</th>
      <th>What already existed</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Committed Rubric De-Anchoring</strong></td>
      <td>Have the judge pre-commit a decomposed rubric <em>before</em> seeing the candidate answer, to block “convincing not correct” reward hacking</td>
      <td><a href="https://arxiv.org/abs/2601.08654">RULERS</a> (Jan 2026) implements essentially the same three-stage pipeline, published months earlier</td>
    </tr>
    <tr>
      <td><strong>EffVote</strong></td>
      <td>Build judge panels by explicitly selecting for measured statistical independence (via a determinantal point process over the error-correlation matrix), not just “different vendor”</td>
      <td>Closest to surviving — 1 of 3 skeptics called it novel. Every building block (the Kish n_eff diagnostic, DPP selection, decorrelated aggregation) already exists individually; no exact match for the full pipeline was found, but the space is, in the reviewer’s words, “extremely crowded”</td>
    </tr>
    <tr>
      <td><strong>Escalate-Where-It-Breaks</strong></td>
      <td>Calibrate judge confidence specifically under adversarial and cross-cultural distribution shift, not just standard accuracy benchmarks</td>
      <td>All four grounding papers check out, but the mechanism is an integration of existing calibration techniques over existing stress-test datasets — an evaluation study, not a new capability</td>
    </tr>
    <tr>
      <td><strong>Format-Invariant Judging</strong></td>
      <td>Treat format bias the way MT-Bench treats position bias: strip markdown, re-judge, compare, flag disagreement</td>
      <td>A <a href="https://tianpan.co/blog/2026-04-27-llm-judge-bias-audit-length-position-format">public blog post</a> spelled out this exact recipe <strong>three months before</strong> I proposed it</td>
    </tr>
    <tr>
      <td><strong>Locale-Stratified Judge Auditing</strong></td>
      <td>Re-run the entire existing mitigation toolkit stratified by language × culture, with a per-cell go/no-go reliability gate</td>
      <td>M-RewardBench, MM-Eval, and a 2026 paper called BabelJudge already treat cross-lingual/cross-cultural robustness as a first-class axis, contradicting the premise that it’s under-explored</td>
    </tr>
  </tbody>
</table>

<figure style="max-width:640px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-as-judge/research-pipeline.png" alt="Flowchart of the research pipeline: 6 survey agents to 5 proposals to 3 skeptics each to verdicts" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">EffVote was the closest thing to a survivor — 1 of 3 skeptics called it novel. Everything else got a full red X.</figcaption>
</figure>

<p>Zero for five. And I want to be direct about why that’s the interesting result rather than a disappointing one: every single “gap” my agents identified as under-explored had already been substantially closed by a real paper, and in two cases, closed within the previous few months. That’s not a story about my research process being bad. It’s a story about how fast this specific field is moving right now. If a competent, well-grounded ideation pass — searching the literature, checking mechanisms, being honest about limitations — gets scooped this reliably, the honest takeaway isn’t “invent something,” it’s <strong>“go read what already exists, because it’s better than what you’d invent, and it’s newer than you’d expect.”</strong></p>

<h2 id="10-where-the-frontier-actually-is">10. Where the Frontier Actually Is</h2>

<p>If you’re an engineer looking for where to actually contribute — not “impressive-sounding project” contribute, but real open-problem contribute — here’s what the graveyard above points at:</p>

<ul>
  <li><strong>Panel diversity that’s measured, not assumed.</strong> Nine Judges shows the problem; nobody has shipped a production-grade selection method that engineers panels for genuine statistical independence rather than nominal vendor diversity.</li>
  <li><strong>Calibration under adversarial and cross-cultural pressure specifically</strong>, not just in-distribution accuracy. The existing calibration literature is real and works — on the easy regime. Nobody has proven it survives the regime where it actually matters.</li>
  <li><strong>Defending against reward-hacking under self-play</strong>, where the judge is training the thing that’s learning to fool it. The 0.74 judge-truth gap surviving a three-judge ensemble is a five-alarm fire that the field has diagnosed but not extinguished.</li>
  <li><strong>Cross-lingual/cross-cultural certification as an operational gate</strong>, not a research metric — turning “here’s our multilingual accuracy number” into “here’s a machine-checkable go/no-go before you ship this judge in a market you haven’t validated it for.”</li>
</ul>

<p>None of these require you to out-invent the field. They require you to pick one of these open problems and go deeper than a survey paper — which, per Section 9, is a genuinely different and much harder bar than it sounds.</p>

<h2 id="11-the-war-room-reference-table">11. The War Room Reference Table</h2>

<table>
  <thead>
    <tr>
      <th>Failure mode</th>
      <th>Rough magnitude</th>
      <th>Best current mitigation</th>
      <th>Maturity</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Position bias</td>
      <td>Flips verdicts on ~15-80% of close calls, task-dependent</td>
      <td>Order-swap, require consistency</td>
      <td>Mature</td>
    </tr>
    <tr>
      <td>Verbosity bias</td>
      <td>Family-dependent; some judges &gt;90% length-correlated</td>
      <td>Length-controlled regression</td>
      <td>Mature</td>
    </tr>
    <tr>
      <td>Format/style bias</td>
      <td>Effect size 0.76-0.92 — ~20x larger than position bias</td>
      <td>Format-stripped comparison</td>
      <td>Emerging, not yet standard</td>
    </tr>
    <tr>
      <td>Self-preference bias</td>
      <td>10-25% self-rating boost</td>
      <td>Use a different, stronger model as judge</td>
      <td>Mature</td>
    </tr>
    <tr>
      <td>Factuality correlation</td>
      <td>0.3-0.6 vs. 0.8-0.9 for humans</td>
      <td>Reference-guided grading</td>
      <td>Partial</td>
    </tr>
    <tr>
      <td>Safety judgment</td>
      <td>Near-zero/negative kappa on nuanced categories</td>
      <td>Human gold-set validation, no full automation</td>
      <td>Unsolved</td>
    </tr>
    <tr>
      <td>Adversarial reward hacking</td>
      <td>Judge-truth gap up to 0.74, survives 3-judge ensembles</td>
      <td>None proven robust yet</td>
      <td>Open frontier</td>
    </tr>
    <tr>
      <td>Cross-lingual/cultural robustness</td>
      <td>Degrades sharply outside English/majority culture</td>
      <td>Stratified benchmarks (M-RewardBench, BabelJudge)</td>
      <td>Active, fast-moving</td>
    </tr>
  </tbody>
</table>

<h2 id="conclusion-the-fundamentals-are-settled-the-frontier-is-not">Conclusion: The Fundamentals Are Settled. The Frontier Is Not.</h2>

<p>Here’s the honest shape of where things stand: the basic case for LLM-as-a-judge — chain-of-thought scoring, reference-guided grading, position-swap consistency checks, rubric decomposition, and validating everything against a small human-labeled gold set with chance-corrected agreement — is genuinely solved. It works, it’s deployed at scale by every serious lab and platform in this post, and if you’re building an eval pipeline today, that toolkit is your starting point, not a research project.</p>

<p>What’s not solved is everything that happens once the judge is under real pressure: adversarial optimization, safety-critical or culturally-specific content, and panels that look diverse but aren’t. That’s not a gap you close by reading one survey and having a clever idea — I tried, and the literature ate my lunch five times in a row. It’s a gap you close by actually reading the last two years of this field, which is exactly what six research agents and an afternoon of adversarial review just did for both of us.</p>

<p>If you’re an engineer trying to get on board with evaluation work, this is, genuinely, one of the best times to start. The fundamentals are stable enough to build on immediately. The open problems are documented, real, and moving fast enough that “novel” has a shelf life measured in months, not years. That’s not a discouraging fact. It means the frontier is close enough to touch.</p>

<hr />

<h2 id="references">References</h2>

<p><strong>Foundations:</strong> <a href="https://arxiv.org/abs/2303.16634">G-Eval</a> · <a href="https://arxiv.org/abs/2305.14387">AlpacaFarm</a> · <a href="https://github.com/tatsu-lab/alpaca_eval">AlpacaEval</a> · <a href="https://arxiv.org/abs/2306.05685">MT-Bench &amp; Chatbot Arena</a> · <a href="https://arxiv.org/abs/2403.04132">Chatbot Arena platform paper</a> · <a href="https://arxiv.org/abs/2403.13787">RewardBench</a> · <a href="https://arxiv.org/abs/2308.03688">AgentBench</a> · <a href="https://arxiv.org/abs/2212.08073">Constitutional AI</a> · <a href="https://arxiv.org/abs/2309.00267">RLAIF</a> · <a href="https://arxiv.org/abs/2407.21783">Llama 3 Herd of Models</a> · <a href="https://arxiv.org/abs/2404.04475">Length-Controlled AlpacaEval</a></p>

<p><strong>Biases:</strong> <a href="https://arxiv.org/abs/2305.17926">Large Language Models are not Fair Evaluators</a> · <a href="https://arxiv.org/abs/2406.07791">Judging the Judges: Position Bias at Scale</a> · <a href="https://arxiv.org/abs/2410.21819">Self-Preference Bias in LLM-as-a-Judge</a> · <a href="https://arxiv.org/pdf/2404.13076">LLM Evaluators Recognize and Favor Their Own Generations</a> · <a href="https://arxiv.org/abs/2604.23178">Judging the Judges: Bias Mitigation Strategies</a> · <a href="https://tianpan.co/blog/2026-04-27-llm-judge-bias-audit-length-position-format">Your LLM Judge Has a Length, Position, and Format Bias</a> · <a href="https://arxiv.org/abs/2605.26156">Turning Bias into Bugs</a> · <a href="https://arxiv.org/abs/2410.02736">Justice or Prejudice? (CALM framework)</a></p>

<p><strong>Calibration and domain failures:</strong> <a href="https://arxiv.org/abs/2510.09738">Judge’s Verdict</a> · <a href="https://www.medrxiv.org/content/10.1101/2025.10.27.25338910v1.full">Human Evaluators vs. LLM-as-a-Judge in Global Health</a> · <a href="https://arxiv.org/html/2604.19786v1">HumorRank</a> · <a href="https://arxiv.org/pdf/2605.31381">LLM Judges Inconsistently Disagree Across Safety Criteria</a> · <a href="https://arxiv.org/html/2508.06225v2">Overconfidence in LLM-as-a-Judge</a> · <a href="https://arxiv.org/abs/2512.22245">Calibrating LLM Judges: Linear Probes</a></p>

<p><strong>Adversarial robustness:</strong> <a href="https://arxiv.org/abs/2507.08794">One Token to Fool LLM-as-a-Judge</a> · <a href="https://arxiv.org/html/2607.05904">More Convincing, Not More Correct</a> · <a href="https://arxiv.org/html/2603.06594">A Coin Flip for Safety</a> · <a href="https://arxiv.org/abs/2502.01534">Preference Leakage</a></p>

<p><strong>Mitigations:</strong> <a href="https://arxiv.org/html/2404.18796v1">Replacing Judges with Juries (PoLL)</a> · <a href="https://arxiv.org/abs/2308.07201">ChatEval</a> · <a href="https://arxiv.org/html/2605.29800">Nine Judges, Two Effective Votes</a> · <a href="https://arxiv.org/abs/2504.00050">JudgeLRM</a> · <a href="https://arxiv.org/abs/2505.10320">J1: Incentivizing Thinking in LLM-as-a-Judge</a> · <a href="https://proceedings.iclr.cc/paper_files/paper/2025/file/08dabd5345b37fffcbe335bd578b15a0-Paper-Conference.pdf">Trust or Escalate</a> · <a href="https://arxiv.org/pdf/2601.04603">Constitutional Classifiers++</a> · <a href="https://arxiv.org/abs/2602.05125v1">Rethinking Rubric Generation (RRD)</a></p>

<p><strong>Production practice:</strong> <a href="https://www.anthropic.com/engineering/multi-agent-research-system">Anthropic’s multi-agent research system</a> · <a href="https://developers.openai.com/api/docs/guides/graders">OpenAI Graders</a> · <a href="https://developers.openai.com/api/docs/guides/evaluation-best-practices">OpenAI Evaluation Best Practices</a> · <a href="https://cloud.google.com/vertex-ai/docs/generative-ai/models/side-by-side-eval">Vertex AI AutoSxS</a> · <a href="https://scale.com/blog/leaderboard">Scale SEAL Leaderboards</a> · <a href="https://www.databricks.com/blog/databricks-announces-significant-improvements-built-llm-judges-agent-evaluation">Databricks LLM Judges</a> · <a href="https://hamel.dev/blog/posts/llm-judge/index.html">Hamel Husain’s LLM Judge Guide</a> · <a href="https://www.braintrust.dev/articles/how-to-eval">Braintrust: How to Eval</a></p>

<hr />

<p><em>I’m an infrastructure engineer with 11+ years in distributed systems (D-Wave, Enbala, MasterCard, Cisco), currently going deep on LLM serving, evaluation, and agent infrastructure. This post is grounded in a real multi-agent research pipeline — six survey agents, a synthesis pass, five proposals, and fifteen adversarial reviews — not just my own reading. I write what I actually learned, including the parts where my own ideas lost.</em></p>

<p><em>Find me on GitHub: <a href="https://github.com/kraghavan">kraghavan</a></em></p>

<p><em>Find me on Linkedin: <a href="https://linkedin.com/in/karthikaraghavan">Karthika Raghavan</a></em></p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm-infrastructure" /><category term="evaluation" /><category term="llm-as-a-judge" /><category term="evaluation" /><category term="rlhf" /><category term="rlaif" /><category term="benchmarks" /><category term="bias" /><category term="calibration" /><category term="agents" /><summary type="html"><![CDATA[I wanted to actually understand LLM-as-a-judge instead of nodding along the way I used to with CAP theorem before I'd actually read the paper. So I built a proper research pipeline, tried to find something genuinely novel to say about it, and watched all five of my "novel" ideas get killed by papers published in the last few months. Here's everything I learned along the way — with the receipts.]]></summary></entry><entry><title type="html">Software Layers Before Inference At Scale</title><link href="https://kraghavan.ca/2026/04/30/software-layers-before-inference-at-scale.html" rel="alternate" type="text/html" title="Software Layers Before Inference At Scale" /><published>2026-04-30T00:00:00+00:00</published><updated>2026-04-30T00:00:00+00:00</updated><id>https://kraghavan.ca/2026/04/30/software-layers-before-inference-at-scale</id><content type="html" xml:base="https://kraghavan.ca/2026/04/30/software-layers-before-inference-at-scale.html"><![CDATA[<h1 id="the-llm-serving-stack-you-actually-need-from-nginx-to-llm-d-to-gpu">The LLM Serving Stack You Actually Need: From NGINX to llm-d to GPU</h1>

<p><em>A layer-by-layer guide for DevOps, SRE, and infrastructure engineers building scalable, secure, production-grade LLM services — and wondering why the naive approach keeps falling over.</em></p>

<hr />

<p>Lets hear a familliar story. An engineer, often a good one, spins up vLLM, drops it behind a round-robin load balancer, confirms it responds to <code class="language-plaintext highlighter-rouge">curl</code>, and ships it. The demo works. The first week of real traffic does not. TTFT climbs to 8 seconds. A GPU OOMs at 2am. Nobody can explain why because there’s nothing between the load balancer and the model worker that actually understands what’s happening.</p>

<p>The load balancer isn’t the problem. The mental model is.</p>

<p>Serving an LLM at scale is categorically different from serving a stateless REST API. An LLM response isn’t a database row lookup — it’s a two-phase, stateful compute process where the routing decision made <em>before</em> the request ever touches the GPU determines whether your p99 latency is 800ms or 8 seconds. Get the routing wrong and no amount of GPU capacity saves you.</p>

<p>This is the architecture that gets it close to production grade. We’ll cover each layer — what it does, why it exists, and what a real config looks like. If you want to understand what’s actually happening inside the GPU once a request lands, I’d start with my <a href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/14/re-introduction-to-inference.html">deep inference walkthrough</a> first. This post picks up where that one ends.</p>

<p>One deliberate scope boundary worth stating upfront: this article covers the serving infrastructure — the layers between your user and your GPU. The application layer above it, including retrieval pipelines, vector databases, MCP tool integration, and orchestration frameworks, is a separate concern and not covered here. Those components plug in above Layer 3, but how they do so is its own topic.</p>

<hr />

<h2 id="why-you-cant-just-load-balance-an-llm">Why You Can’t Just Load-Balance an LLM</h2>

<p>The naive mental model — round-robin across replicas — breaks for four distinct reasons that compound on each other.</p>

<p><strong>KV cache is stateful per-replica.</strong> When a request lands on a replica that hasn’t seen this prompt prefix before, it recomputes the entire KV cache from scratch. Route to the wrong replica and you pay full prefill cost every time. Route to the right one and prefill is nearly free. A round-robin load balancer has no idea this distinction exists. The <a href="https://docs.vllm.ai/en/latest/automatic_prefix_caching/apc.html">vLLM prefix caching docs</a> explain the underlying mechanism well if you want to go deeper on how blocks are hashed and matched.</p>

<p><strong>Prefill and decode have wildly different compute profiles.</strong> Prefill is GPU compute-bound — it parallelizes across all input tokens at once. Decode is GPU memory-bandwidth-bound — it generates one token at a time against an ever-growing KV cache. Running both phases on the same pod pool means a single long-context prefill can stall your decode queue for every other in-flight request. These phases want different hardware and different scheduling treatment.</p>

<p><strong>Token budgets are not request counts.</strong> Traditional RPS-based load balancing treats every request as equivalent. It’s completely blind to the difference between a 200-token chat turn and a 32k-token document summarization. A single 32k-context request consumes the GPU memory and compute that would otherwise serve 50 short requests. Your quota system needs to reason about tokens, not connections.</p>

<p><strong>GPU memory is the real constraint.</strong> When your KV cache is full, new requests either queue and wait or trigger eviction of in-progress requests — which causes latency spikes as those requests recompute from scratch. A load balancer tracking CPU and RAM is measuring the wrong thing. The constraint is VRAM, and specifically KV cache block occupancy.</p>

<p>The punchline: <strong>LLM load balancing is a scheduling problem disguised as a networking problem.</strong> The stack below exists to solve the scheduling problem correctly at each layer.</p>

<hr />

<h2 id="the-stack-at-a-glance">The Stack at a Glance</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Client
  └─ NGINX / Envoy              ← TLS termination, connection limits, WAF, basic rate limit
       └─ Kong Gateway           ← Auth, per-tenant quota, request logging, plugin chain
            └─ LiteLLM / L3 proxy  ← Model abstraction, fallbacks, cost attribution, caching
                 └─ llm-d        ← KV-cache-aware scheduling, prefill/decode disaggregation
                      └─ vLLM replicas  ← PagedAttention, continuous batching
                           └─ GPU
</code></pre></div></div>

<p>Before we get into each layer, one thing that trips people up early: <strong>NGINX at Layer 1 is not your LLM gateway. It’s your platform gateway.</strong> Your LLM service lives alongside your user API, your auth service, your billing endpoints. NGINX routes all of them. This distinction changes how you think about security, compliance, and observability across the entire stack.</p>

<hr />

<h2 id="layer-1--edge-ingress-nginx--envoy--traefik">Layer 1 — Edge Ingress (NGINX / Envoy / Traefik)</h2>

<p><strong>What it does:</strong> TLS termination, unified platform routing, WAF filtering, IP-based rate limiting. Everything entering your cluster north-south passes through here.</p>

<p>This layer routes your <em>entire platform</em> — not just LLM traffic. Your NGINX config has location blocks for your user API, your auth service, your product endpoints, and your LLM service. Security controls here — SQL injection filtering, request size limits, DDoS protection — apply uniformly across everything. That uniformity is the value. The moment you build a separate LLM-specific ingress, you’ve split your security posture in two and you’re maintaining both forever.</p>

<div class="language-nginx highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># nginx.conf — unified platform ingress</span>
<span class="k">upstream</span> <span class="s">app_backend</span> <span class="p">{</span>
    <span class="kn">server</span> <span class="nf">app-service</span><span class="p">:</span><span class="mi">8080</span><span class="p">;</span>
<span class="p">}</span>

<span class="k">upstream</span> <span class="s">llm_gateway</span> <span class="p">{</span>
    <span class="kn">server</span> <span class="nf">litellm</span><span class="p">:</span><span class="mi">4000</span><span class="p">;</span>
<span class="p">}</span>

<span class="k">server</span> <span class="p">{</span>
    <span class="kn">listen</span> <span class="mi">443</span> <span class="s">ssl</span><span class="p">;</span>
    <span class="kn">server_name</span> <span class="s">api.yourplatform.com</span><span class="p">;</span>

    <span class="c1"># Standard application traffic</span>
    <span class="kn">location</span> <span class="n">/api/v1/users/</span> <span class="p">{</span>
        <span class="kn">proxy_pass</span> <span class="s">http://app_backend</span><span class="p">;</span>
        <span class="kn">include</span> <span class="n">/etc/nginx/modsecurity.conf</span><span class="p">;</span>   <span class="c1"># WAF: SQL injection, XSS</span>
    <span class="p">}</span>

    <span class="kn">location</span> <span class="n">/api/v1/auth/</span> <span class="p">{</span>
        <span class="kn">proxy_pass</span> <span class="s">http://app_backend</span><span class="p">;</span>
        <span class="kn">limit_req</span> <span class="s">zone=auth_limit</span> <span class="s">burst=10</span> <span class="s">nodelay</span><span class="p">;</span>
    <span class="p">}</span>

    <span class="c1"># LLM traffic — routed to LLM gateway (L3)</span>
    <span class="kn">location</span> <span class="n">/api/v1/chat/</span> <span class="p">{</span>
        <span class="kn">proxy_pass</span> <span class="s">http://llm_gateway</span><span class="p">;</span>
        <span class="kn">proxy_read_timeout</span> <span class="s">120s</span><span class="p">;</span>          <span class="c1"># Default 60s is not enough for long generations</span>
        <span class="kn">proxy_buffering</span> <span class="no">off</span><span class="p">;</span>              <span class="c1"># Critical: SSE streaming breaks without this</span>
        <span class="kn">proxy_set_header</span> <span class="s">X-Real-IP</span> <span class="nv">$remote_addr</span><span class="p">;</span>
        <span class="kn">limit_req</span> <span class="s">zone=llm_limit</span> <span class="s">burst=5</span> <span class="s">nodelay</span><span class="p">;</span>
    <span class="p">}</span>

    <span class="kn">location</span> <span class="n">/api/v1/embed/</span> <span class="p">{</span>
        <span class="kn">proxy_pass</span> <span class="s">http://llm_gateway</span><span class="p">;</span>
        <span class="kn">proxy_read_timeout</span> <span class="s">30s</span><span class="p">;</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">proxy_buffering off</code> on the chat endpoint is not optional. Without it, NGINX holds the entire streaming response in its buffer before delivering it — your users see nothing until the full response is done. Verify this with a streaming test before you ship; it fails silently. The <a href="https://nginx.org/en/docs/http/ngx_http_proxy_module.html#proxy_buffering">NGINX docs on proxying</a> cover the interaction with SSE and chunked transfer encoding if you need the full picture.</p>

<p><strong>Scalability:</strong> Completely stateless — add NGINX instances horizontally behind your cloud load balancer without coordination. Handles millions of concurrent connections.</p>

<p><strong>Security:</strong> TLS offload, WAF rules, IP allowlisting, DDoS rate limiting. This is your perimeter — every request passes through before any application code sees it. <a href="https://github.com/owasp-modsecurity/ModSecurity">ModSecurity</a> is the standard WAF module for NGINX if you haven’t already integrated it.</p>

<p><strong>Compliance:</strong> Full audit logging of inbound traffic. IP-based geo-blocking for data residency requirements. Request body size limits block oversized prompt payloads — raise the default 1MB limit to 10–50MB or legitimate LLM requests will be rejected.</p>

<p><strong>Reliability:</strong> Health checks against all upstreams with automatic failover. If L3 goes down, NGINX returns a clean 502 rather than letting connections hang until they timeout.</p>

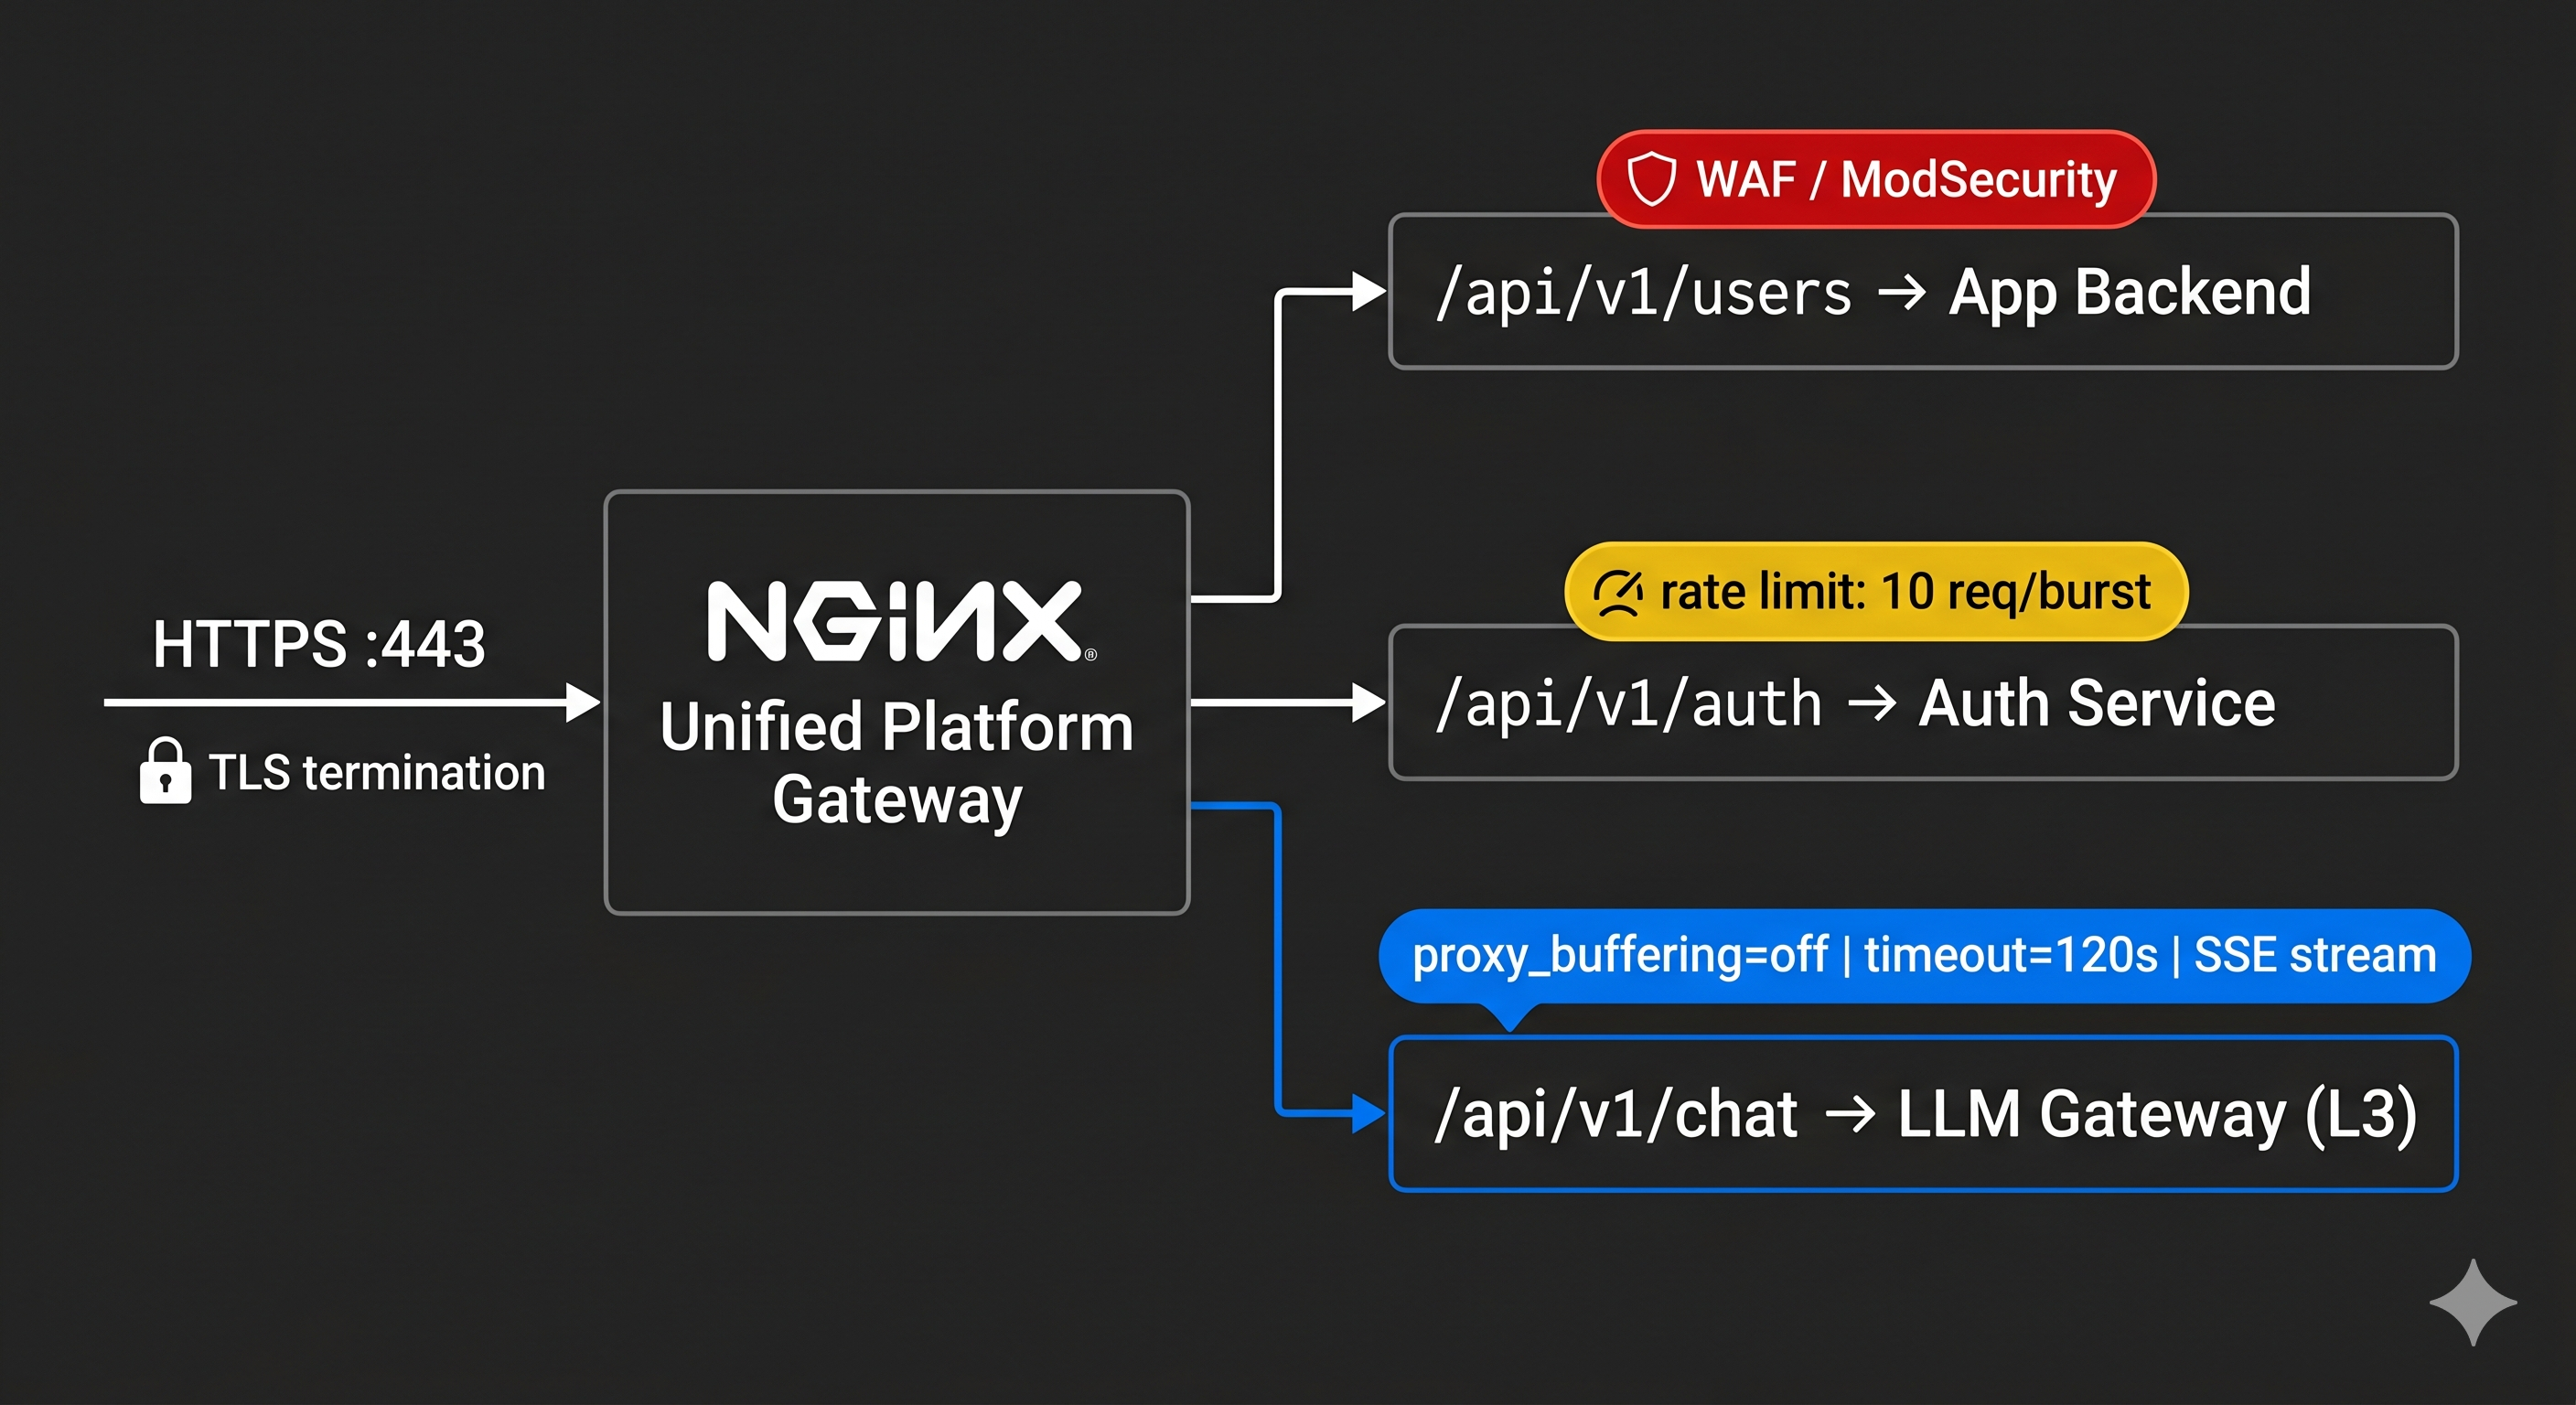
<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/nginx-unified-platform.png" alt="NGINX as a unified platform gateway routing HTTPS traffic to three upstreams: App Backend with WAF, Auth Service with rate limiting, and LLM Gateway with SSE streaming configuration" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    NGINX as a unified platform gateway. A single HTTPS :443 entry point (with TLS termination) fans out to three upstream paths: the App Backend (red path, /api/v1/users) protected by WAF / ModSecurity; the Auth Service (yellow path, /api/v1/auth) with a burst rate limit; and the LLM Gateway at L3 (blue path, /api/v1/chat) carrying streaming-specific annotations — proxy_buffering=off and a 120s read timeout — that are absent from the other two paths. The LLM path is the only one where buffering must be disabled for SSE to work correctly.
  </figcaption>
</figure>

<hr />

<h2 id="layer-2--api-gateway-kong--aws-api-gw--apigee">Layer 2 — API Gateway (Kong / AWS API GW / Apigee)</h2>

<p><strong>What it does:</strong> Per-consumer identity, quota enforcement, centralized audit logging, compliance controls. Where Layer 1 knows <em>what</em> is coming in, Layer 2 knows <em>who</em> is sending it.</p>

<p>This is your consumer-facing contract layer. Every team, every external partner, every integration that calls your LLM service gets an API key managed here. Rate limits are enforced here — and critically, in token-per-minute terms, not requests-per-minute. When your security team asks “which consumers sent requests to the model between 9pm and midnight last Tuesday,” this is where that answer lives — not scattered across application logs.</p>

<p><a href="https://docs.konghq.com/hub/kong-inc/ai-proxy/">Kong’s AI Gateway plugin</a> adds prompt-level rate limiting and response caching as first-class plugins, which gives you a natural integration point between L2 and L3 concerns without duplicating configuration. AWS API Gateway is the natural choice if you’re already heavily on AWS and routing to Bedrock or SageMaker endpoints.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Kong declarative config — AI traffic with per-consumer quota</span>
<span class="na">services</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">llm-service</span>
    <span class="na">url</span><span class="pi">:</span> <span class="s">http://litellm:4000</span>
    <span class="na">routes</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">chat-route</span>
        <span class="na">paths</span><span class="pi">:</span>
          <span class="pi">-</span> <span class="s">/api/v1/chat</span>
    <span class="na">plugins</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">key-auth</span>                   <span class="c1"># Identify the consumer by API key</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">rate-limiting</span>
        <span class="na">config</span><span class="pi">:</span>
          <span class="na">minute</span><span class="pi">:</span> <span class="m">60</span>                     <span class="c1"># 60 req/min per consumer key</span>
          <span class="na">policy</span><span class="pi">:</span> <span class="s">redis</span>                  <span class="c1"># Shared limit across Kong replicas</span>
          <span class="na">redis_host</span><span class="pi">:</span> <span class="s">redis</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">request-size-limiting</span>
        <span class="na">config</span><span class="pi">:</span>
          <span class="na">allowed_payload_size</span><span class="pi">:</span> <span class="m">10</span>       <span class="c1"># 10MB cap — prevents prompt stuffing</span>
      <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">http-log</span>                   <span class="c1"># Immutable audit trail per request</span>
        <span class="na">config</span><span class="pi">:</span>
          <span class="na">http_endpoint</span><span class="pi">:</span> <span class="s">http://audit-service/log</span>
</code></pre></div></div>

<p>The ownership model here matters: <strong>platform teams own L2, ML teams own L3.</strong> Platform controls who gets a key, what their quota is, and what compliance requirements look like. ML teams control which models are available, how fallbacks work, and what cost attribution looks like. Different concerns, different change cadences — keeping them in separate layers means neither team blocks the other’s deploys.</p>

<p><strong>Scalability:</strong> Centralized quota enforcement means no single consumer can saturate your GPU pool regardless of how aggressively they call. Token budgets per API key enforced before the request reaches inference.</p>

<p><strong>Security:</strong> API key lifecycle management, scoped permissions, key rotation without application changes. Auth concern cleanly separated from inference logic.</p>

<p><strong>Compliance:</strong> Immutable per-request audit log with consumer identity attached. This is what SOC2 and HIPAA auditors look at — you can’t reconstruct this after the fact from vLLM logs.</p>

<p><strong>Reliability:</strong> Circuit breaker per consumer. A runaway batch job from one team hitting quota doesn’t degrade other consumers — they’re rate-limited independently.</p>

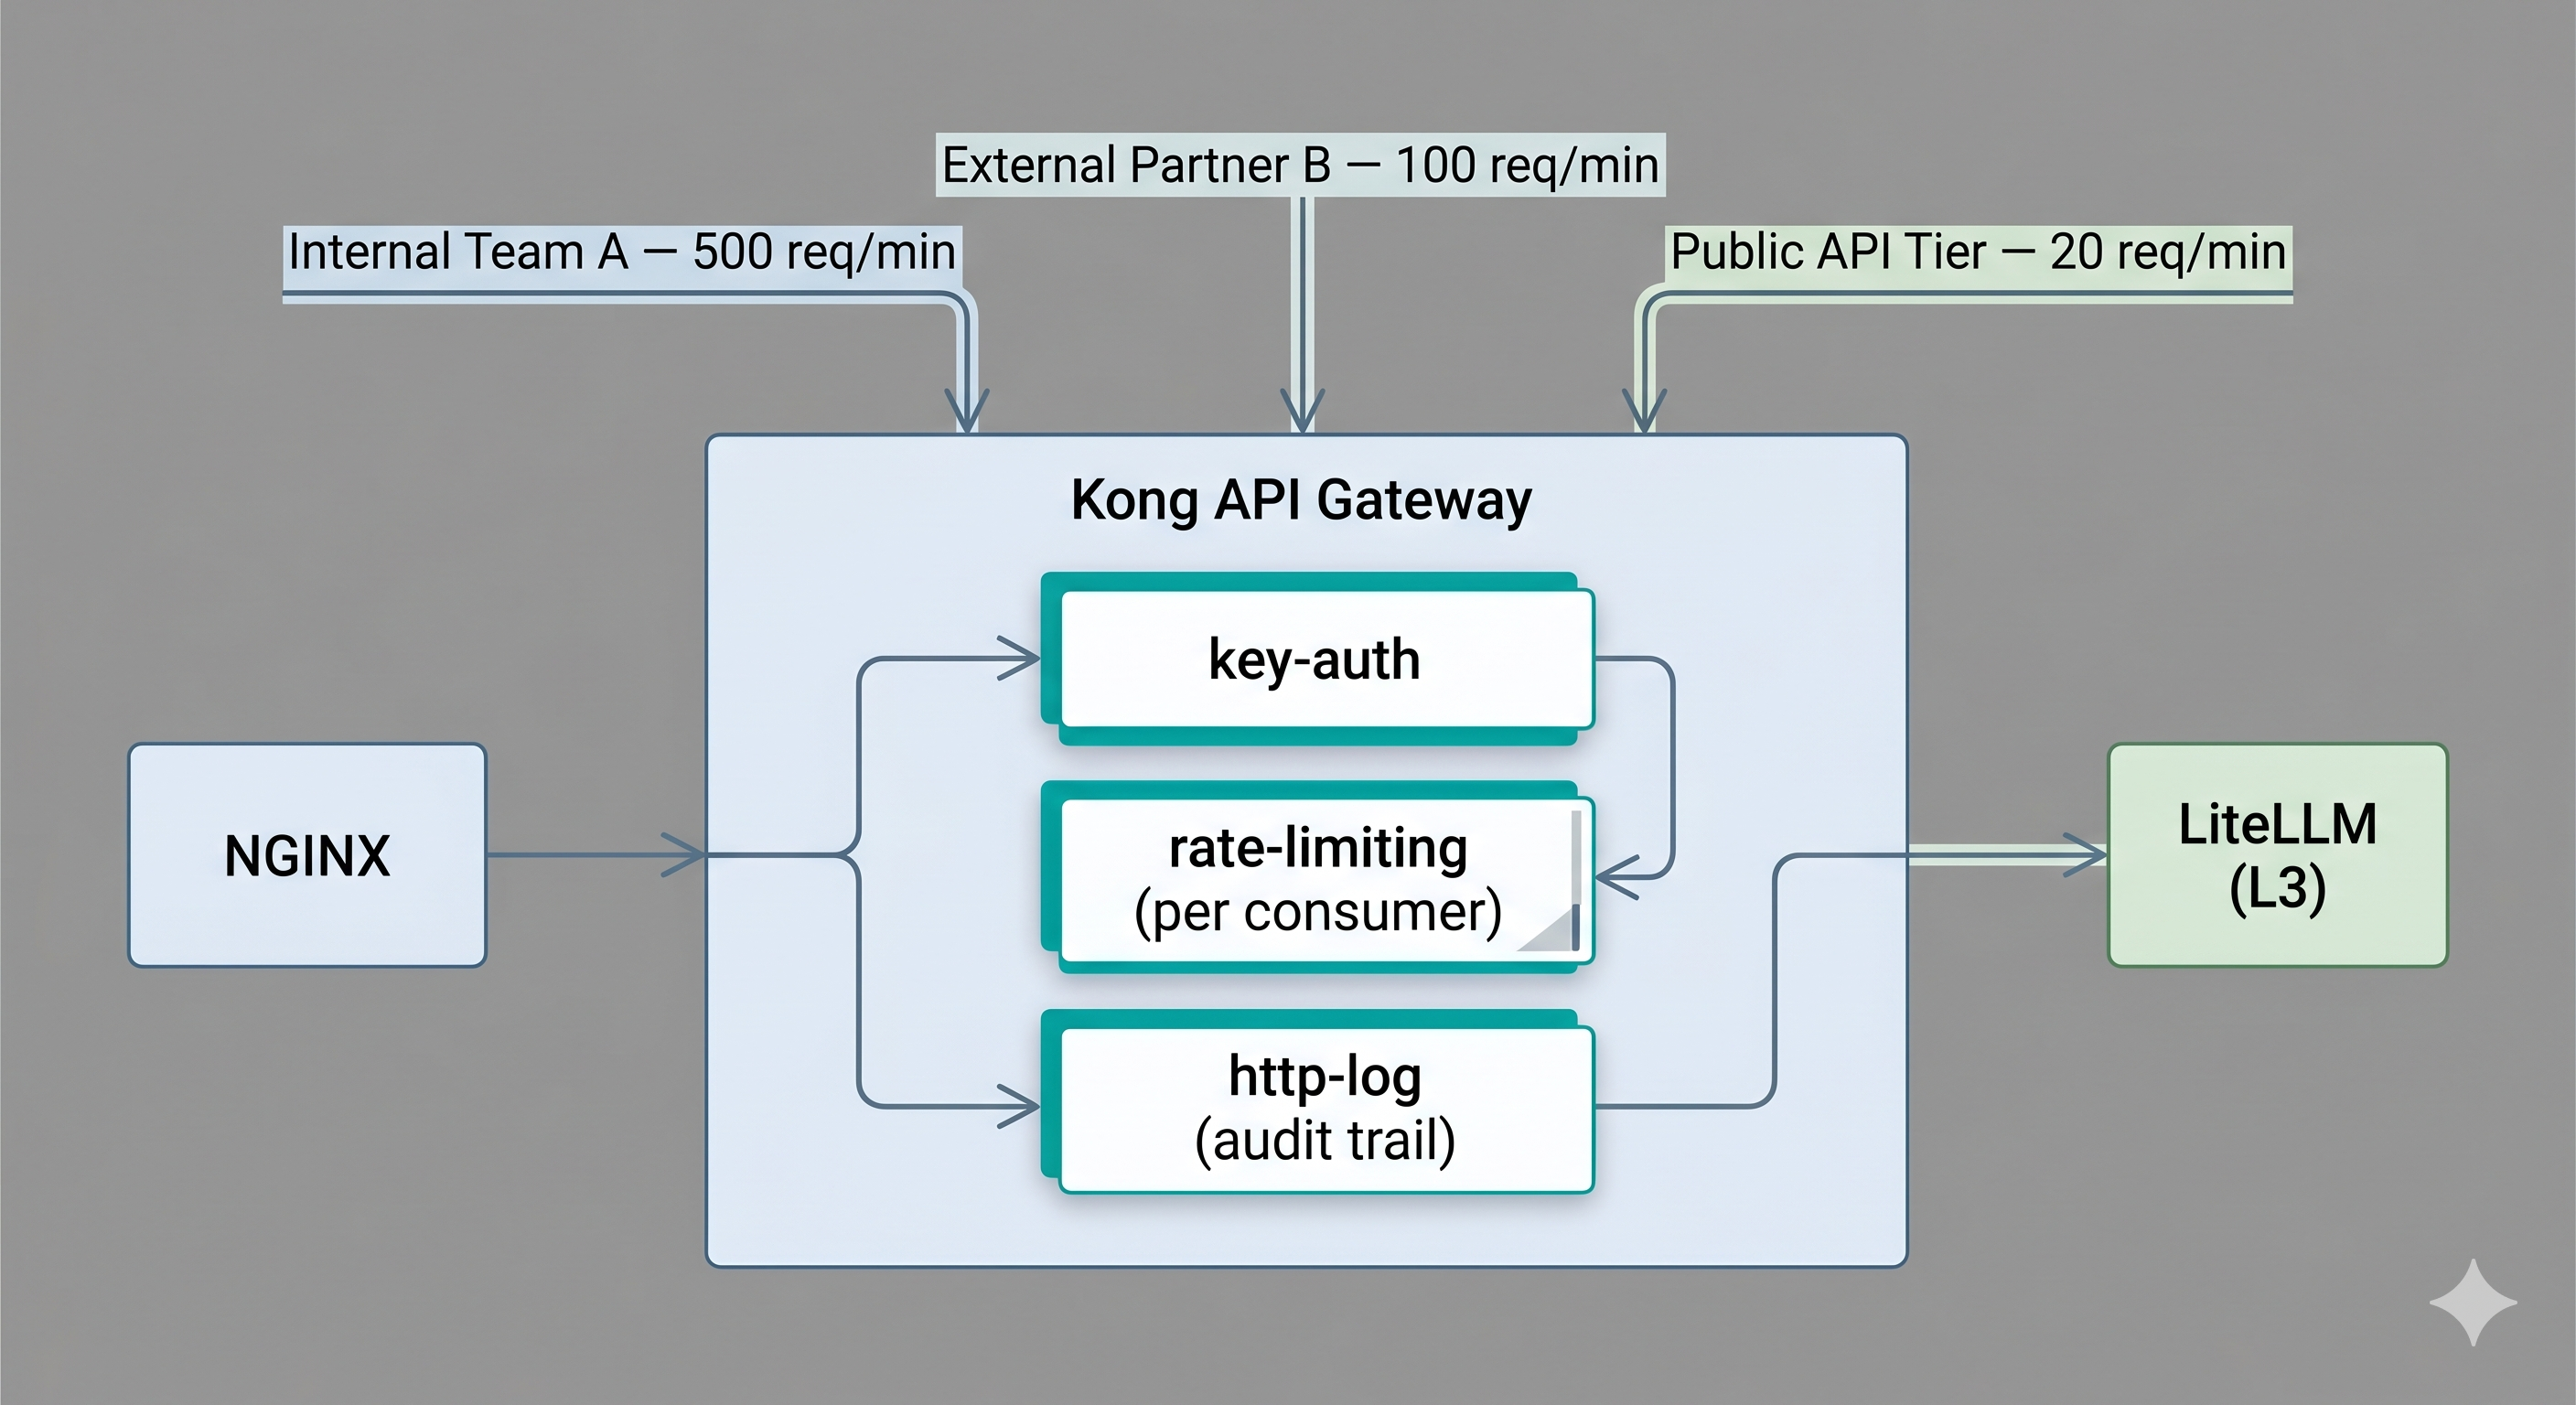
<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/kong-api-gateway.png" alt="Kong API Gateway managing three consumer tiers — Internal Team A, External Partner B, and Public API — each with independent rate limits enforced through key-auth, rate-limiting, and http-log plugins before forwarding to LiteLLM" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    A technical architecture diagram showing the Kong API Gateway as a traffic management layer. On the left, traffic from NGINX feeds into the gateway. At the top of Kong, three consumer identities are defined: 'Internal Team A' with a 500 req/min limit, 'External Partner B' with 100 req/min, and 'Public API Tier' with 20 req/min. Inside the Kong gateway block, requests pass sequentially through three stacked plugin boxes labeled 'key-auth', 'rate-limiting (per consumer)', and 'http-log (audit trail)', which are highlighted with teal accents. Finally, processed requests flow out of Kong via a single outbound arrow to LiteLLM (L3) on the right. The diagram uses a clean flowchart style with a muted color scheme against a grey background.
  </figcaption>
</figure>

<hr />

<h2 id="layer-3--llm-aware-proxy-litellm--portkey">Layer 3 — LLM-Aware Proxy (LiteLLM / PortKey)</h2>

<p><strong>What it does:</strong> Model name abstraction, fallback chains, cost attribution, semantic caching. This is the first layer in the stack that actually understands what an LLM request is.</p>

<p><a href="https://docs.litellm.ai/docs/">LiteLLM</a> gives your application a single OpenAI-compatible endpoint while managing all the complexity underneath — routing to different providers, retrying failed requests, tracking cost per model per team, and caching repeated prompts. Your application code never needs to know whether it’s talking to a self-hosted Llama cluster or Anthropic’s API. <a href="https://portkey.ai/docs">PortKey</a> is a solid alternative if you need stronger guardrails and observability built in rather than composed through callbacks.</p>

<p>For teams that need to go further — classifying prompts by data sensitivity, enforcing that PII never routes to cloud providers — LiteLLM is a solid foundation that you’d extend with custom middleware at this layer. I’ve been exploring a similar pattern as a side project, though it’s still a long way from production-ready.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># litellm config.yaml</span>
<span class="c1"># Illustrative — verify field names and routing strategy values against</span>
<span class="c1"># your installed LiteLLM version before deploying</span>
<span class="c1"># Docs: https://docs.litellm.ai/docs/routing</span>
<span class="na">model_list</span><span class="pi">:</span>
  <span class="c1"># Primary: internal vLLM cluster (routed through llm-d at L4)</span>
  <span class="pi">-</span> <span class="na">model_name</span><span class="pi">:</span> <span class="s">gpt-4o</span>
    <span class="na">litellm_params</span><span class="pi">:</span>
      <span class="na">model</span><span class="pi">:</span> <span class="s">openai/gpt-4o</span>
      <span class="na">api_base</span><span class="pi">:</span> <span class="s">http://llmd-router:8080/v1</span>
      <span class="na">api_key</span><span class="pi">:</span> <span class="s2">"</span><span class="s">sk-internal"</span>

  <span class="c1"># Fallback: Anthropic (if internal cluster is saturated or unavailable)</span>
  <span class="pi">-</span> <span class="na">model_name</span><span class="pi">:</span> <span class="s">gpt-4o</span>
    <span class="na">litellm_params</span><span class="pi">:</span>
      <span class="na">model</span><span class="pi">:</span> <span class="s">anthropic/claude-sonnet-4-5</span>
      <span class="na">api_key</span><span class="pi">:</span> <span class="s">os.environ/ANTHROPIC_API_KEY</span>

  <span class="c1"># Emergency fallback</span>
  <span class="pi">-</span> <span class="na">model_name</span><span class="pi">:</span> <span class="s">gpt-4o</span>
    <span class="na">litellm_params</span><span class="pi">:</span>
      <span class="na">model</span><span class="pi">:</span> <span class="s">openai/gpt-4o</span>
      <span class="na">api_key</span><span class="pi">:</span> <span class="s">os.environ/OPENAI_API_KEY</span>

<span class="na">router_settings</span><span class="pi">:</span>
  <span class="na">routing_strategy</span><span class="pi">:</span> <span class="s">least-busy</span>
  <span class="na">num_retries</span><span class="pi">:</span> <span class="m">2</span>
  <span class="na">retry_after</span><span class="pi">:</span> <span class="m">5</span>

<span class="na">litellm_settings</span><span class="pi">:</span>
  <span class="na">success_callback</span><span class="pi">:</span> <span class="pi">[</span><span class="s2">"</span><span class="s">prometheus"</span><span class="pi">]</span>
  <span class="na">failure_callback</span><span class="pi">:</span> <span class="pi">[</span><span class="s2">"</span><span class="s">prometheus"</span><span class="pi">]</span>
  <span class="na">cache</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">cache_params</span><span class="pi">:</span>
    <span class="na">type</span><span class="pi">:</span> <span class="s">redis</span>
    <span class="na">host</span><span class="pi">:</span> <span class="s">redis</span>
    <span class="na">port</span><span class="pi">:</span> <span class="m">6379</span>
    <span class="na">ttl</span><span class="pi">:</span> <span class="m">3600</span>
</code></pre></div></div>

<p>Semantic caching is worth enabling from day one. For any workload with repeated questions — knowledge base Q&amp;A, customer support, internal tooling — cache hit rates of 30–40% are realistic. That’s 30–40% of inference traffic returning zero GPU compute. Enable it, set a sensible TTL for your workload, and check the hit rate in Grafana after your first week of real traffic.</p>

<p>One thing worth understanding clearly: L3 is the only layer in this entire stack that can stop a long prompt from traveling all the way to the GPU. Every other layer — NGINX, Kong, llm-d — reads the full request body, makes a decision, and forwards it wholesale. llm-d’s KV cache routing is often misread as meaning the prompt doesn’t travel to vLLM; it does, every time. What llm-d skips is the <em>compute</em> on the cached prefix, not the transmission of the prompt itself. The only genuine short-circuit is a semantic cache hit at L3, where LiteLLM returns the stored response from Redis and the prompt goes no further. For workloads with long system prompts — 4k, 32k, 128k tokens — this distinction has real implications for both latency and memory pressure across the stack. A cache miss on a 128k-token prompt means roughly 500KB of JSON moving through every layer, held in memory at each hop, before a single token is generated.</p>

<p>Provider API keys belong in a secrets manager, not in this config file. A leaked LiteLLM config that contains API keys in plaintext is an expensive incident.</p>

<p><strong>Scalability:</strong> Run multiple LiteLLM instances behind a load balancer, all sharing a Redis cache. Fallback chains mean no single provider outage takes down your service.</p>

<p><strong>Security:</strong> Cloud API keys centralized here — application code never holds provider credentials. Custom classification hooks live at this layer, not scattered across application logic.</p>

<p><strong>Compliance:</strong> Per-model cost tracking for internal chargebacks. Audit log of which model handled which request. Policy enforcement on which teams can access which models.</p>

<p><strong>Reliability:</strong> Automatic failover to fallback providers with configurable retry. Health checks per backend. If your internal cluster is unhealthy, traffic shifts to cloud automatically without any application change.</p>

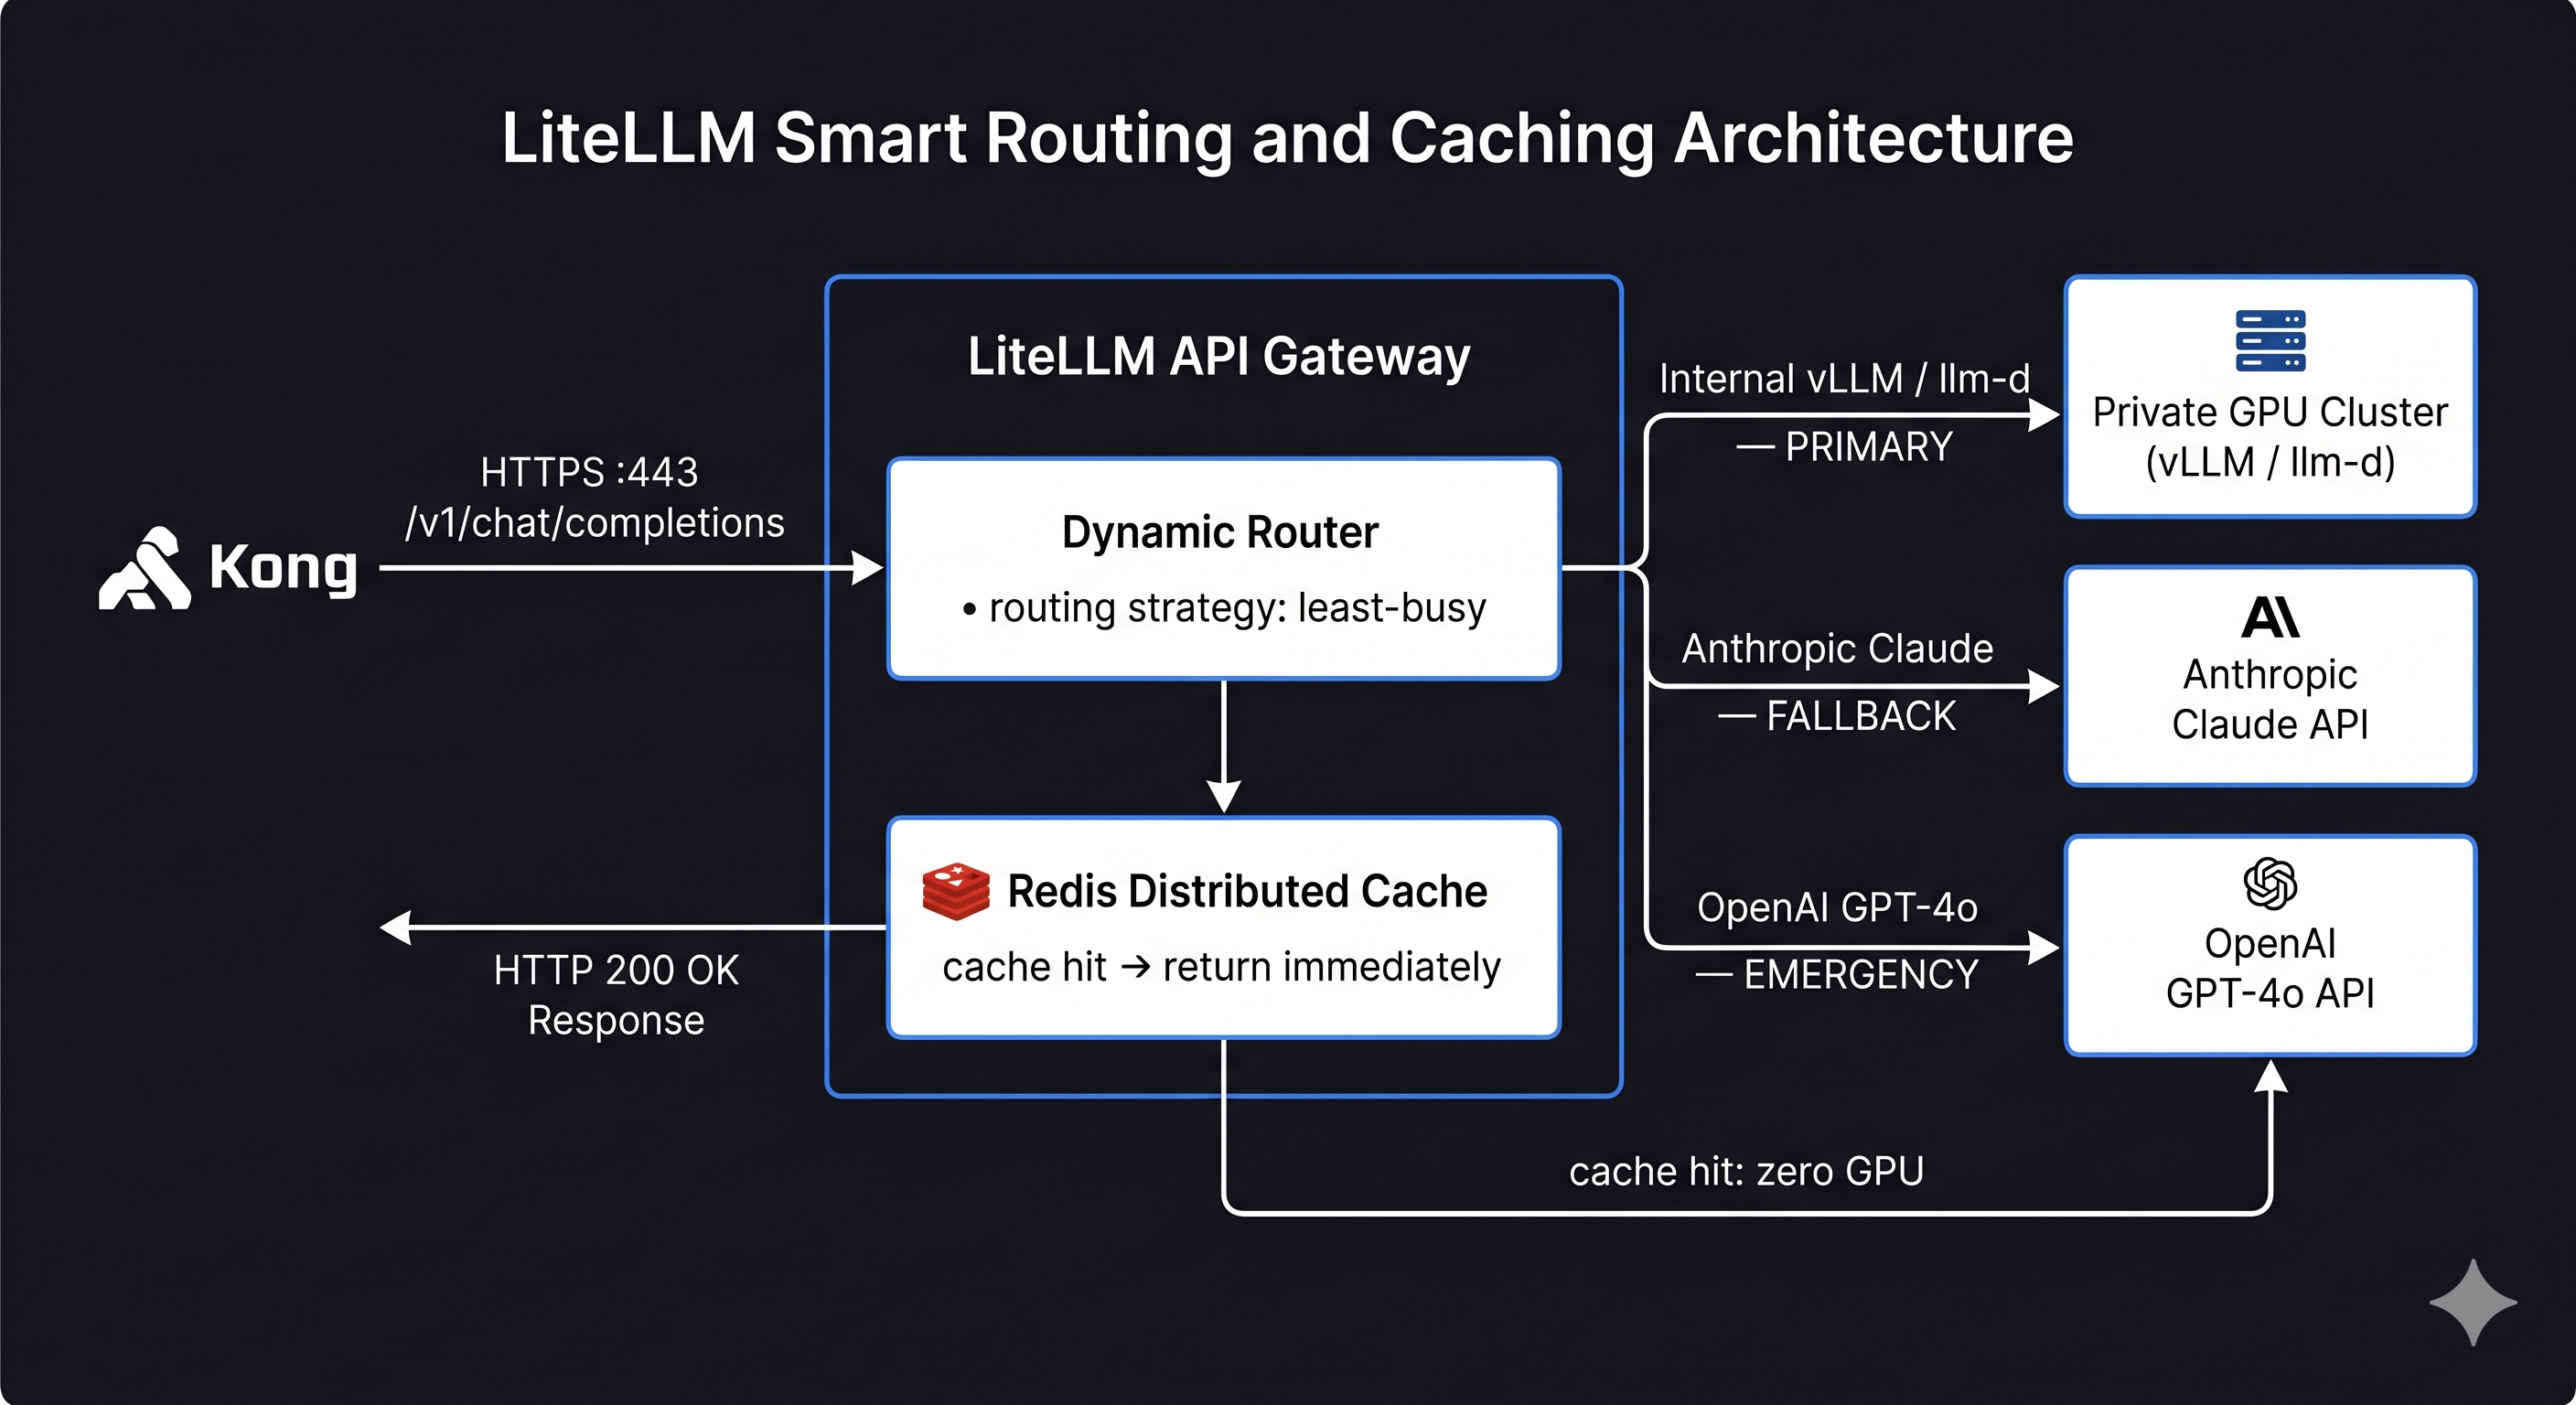
<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/llmlite.png" alt="LiteLLM smart routing layer showing a least-busy router distributing requests across Internal vLLM primary, Anthropic Claude fallback, and OpenAI emergency fallback, with a Redis cache bypass path that returns cached responses without touching the GPU" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    LiteLLM as a smart routing and caching layer. A single /v1/chat/completions request enters from the left (via Kong). Inside LiteLLM, two components are shown: a Router applying a least-busy strategy, and a Redis Cache that short-circuits the request on a hit — returning immediately with zero GPU compute. On a cache miss, the Router forwards to one of three backends in priority order: the internal vLLM cluster via llm-d (primary), Anthropic Claude (fallback), and OpenAI GPT-4o (emergency fallback). The cache-hit bypass arrow is the key visual — it shows the path where no inference work is done at all.
  </figcaption>
</figure>

<hr />

<h2 id="layer-4--inference-router-llm-d--kserve">Layer 4 — Inference Router (llm-d / KServe)</h2>

<p><strong>What it does:</strong> KV cache-aware routing, disaggregated prefill/decode scheduling, GPU queue depth balancing. This is the layer that makes a fleet of GPU workers behave as a single coherent system rather than a collection of independent replicas.</p>

<p>This is the layer most infrastructure engineers haven’t seen before, and it makes the most difference at scale.</p>

<p><strong>KV cache-aware routing</strong> is the core capability. <a href="https://github.com/llm-d/llm-d">llm-d</a> maintains cluster-wide visibility into which KV cache blocks each pod currently holds. When a new request arrives carrying a system prompt that matches a cached prefix on a specific pod, llm-d routes it there. The first request with that prompt pays the full prefill cost. Every subsequent request with the same prefix costs almost nothing on prefill. Without this, every pod in your cluster recomputes the same system prompt KV vectors independently, for every request, forever.</p>

<p><strong>Disaggregated prefill/decode</strong> is the architectural step beyond that. Because prefill is compute-bound and decode is memory-bandwidth-bound, running them on the same pods creates resource contention — long prefills starve decode queues at exactly the wrong moment. llm-d lets you run dedicated prefill pods (sized for compute) and dedicated decode pods (sized for memory bandwidth) as separate pools. The <a href="https://github.com/vllm-project/vllm/issues/4443">disaggregated serving RFC in the vLLM project</a> is worth reading for the hardware-level reasoning behind why this separation matters.</p>
<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># llm-d InferenceModel CRD</span>
<span class="c1"># Field names representative of llm-d v0.x — verify against the</span>
<span class="c1"># current operator spec at github.com/llm-d/llm-d before applying</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">inference.llm-d.io/v1alpha1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">InferenceModel</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">llama3-70b-instruct</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">llm-serving</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">modelName</span><span class="pi">:</span> <span class="s">meta-llama/Llama-3.1-70B-Instruct</span>

  <span class="na">routing</span><span class="pi">:</span>
    <span class="na">strategy</span><span class="pi">:</span> <span class="s">kv-cache-aware</span>

  <span class="na">prefillDecode</span><span class="pi">:</span>
    <span class="na">disaggregated</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">prefillPool</span><span class="pi">:</span>
      <span class="na">replicas</span><span class="pi">:</span> <span class="m">4</span>
      <span class="na">resources</span><span class="pi">:</span>
        <span class="na">limits</span><span class="pi">:</span>
          <span class="na">nvidia.com/gpu</span><span class="pi">:</span> <span class="m">4</span>              <span class="c1"># H100s — need FLOP throughput for prefill</span>
    <span class="na">decodePool</span><span class="pi">:</span>
      <span class="na">replicas</span><span class="pi">:</span> <span class="m">8</span>
      <span class="na">resources</span><span class="pi">:</span>
        <span class="na">limits</span><span class="pi">:</span>
          <span class="na">nvidia.com/gpu</span><span class="pi">:</span> <span class="m">2</span>              <span class="c1"># A10Gs — need HBM bandwidth for decode</span>

  <span class="na">kvCache</span><span class="pi">:</span>
    <span class="na">prefixCachingEnabled</span><span class="pi">:</span> <span class="no">true</span>
    <span class="na">blockSize</span><span class="pi">:</span> <span class="m">16</span>
    <span class="na">maxCachedPrefixes</span><span class="pi">:</span> <span class="m">1000</span>

  <span class="na">scheduling</span><span class="pi">:</span>
    <span class="na">queueDepthThreshold</span><span class="pi">:</span> <span class="m">4</span>
</code></pre></div></div>

<h3 id="llm-d-vs-vllm-standalone">llm-d vs vLLM Standalone</h3>

<p>This is the distinction most people are missing a mental model for.</p>

<table>
  <thead>
    <tr>
      <th>Capability</th>
      <th>vLLM standalone</th>
      <th>llm-d</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Scheduling unit</strong></td>
      <td>Single replica</td>
      <td>Fleet of replicas</td>
    </tr>
    <tr>
      <td><strong>KV cache awareness</strong></td>
      <td>Per-instance only</td>
      <td>Cluster-wide via KV cache index</td>
    </tr>
    <tr>
      <td><strong>Prefill/decode</strong></td>
      <td>Co-located on same pod</td>
      <td>Disaggregated into separate pools</td>
    </tr>
    <tr>
      <td><strong>Routing</strong></td>
      <td>None — you bring your own</td>
      <td>Built-in, cache-locality-aware</td>
    </tr>
    <tr>
      <td><strong>Kubernetes integration</strong></td>
      <td>Manual Deployments + Services</td>
      <td>Native CRDs + operator</td>
    </tr>
  </tbody>
</table>

<p>vLLM is a superb inference engine. llm-d is the orchestration layer that makes a fleet of vLLM workers behave as a single, cache-aware system. You need both.</p>

<h3 id="llm-d-vs-kserve--when-to-use-which">llm-d vs KServe — When to Use Which</h3>

<p><a href="https://kserve.github.io/website/latest/">KServe</a> appears in L4 comparisons often enough that it deserves a direct answer. They solve adjacent but different problems.</p>

<p><strong>Reach for KServe when</strong> you’re already on the Kubeflow ecosystem, you need multi-framework serving (not just vLLM — also TensorFlow, PyTorch Serve, Triton), or model versioning and canary rollout are first-class concerns. KServe has a mature <code class="language-plaintext highlighter-rouge">InferenceService</code> CRD with built-in traffic splitting and revision history that’s genuinely useful for teams managing many models across many versions.</p>

<p><strong>Reach for llm-d when</strong> you’re optimizing specifically for LLM inference scheduling — KV cache locality, prefill/decode disaggregation, and GPU queue depth awareness. llm-d is built from the ground up around the resource dynamics of transformer inference. KServe treats the inference engine as a black box; llm-d is deeply aware of what’s happening inside it.</p>

<p>In practice: KServe is the right answer for general-purpose model serving platforms. llm-d is the right answer when LLM throughput and TTFT are your primary optimization targets.</p>

<p><strong>Scalability:</strong> Scale prefill and decode capacity independently. Add prefill nodes when long-context load increases; add decode nodes when concurrent users increase. KV cache routing reduces redundant GPU work across the fleet.</p>

<p><strong>Security:</strong> Namespace isolation per model and team. RBAC on InferenceModel CRDs. Pod-level network policy enforcement between pools.</p>

<p><strong>Compliance:</strong> Model-level request audit trail. GPU resource quotas per team enforced at the scheduling layer. Policy on which models serve which namespaces lives here, not in application code.</p>

<p><strong>Reliability:</strong> Pod-level health awareness — if a decode pod OOMs, llm-d drains it and reroutes without dropping in-flight requests. Priority scheduling for latency-critical traffic over batch workloads.</p>

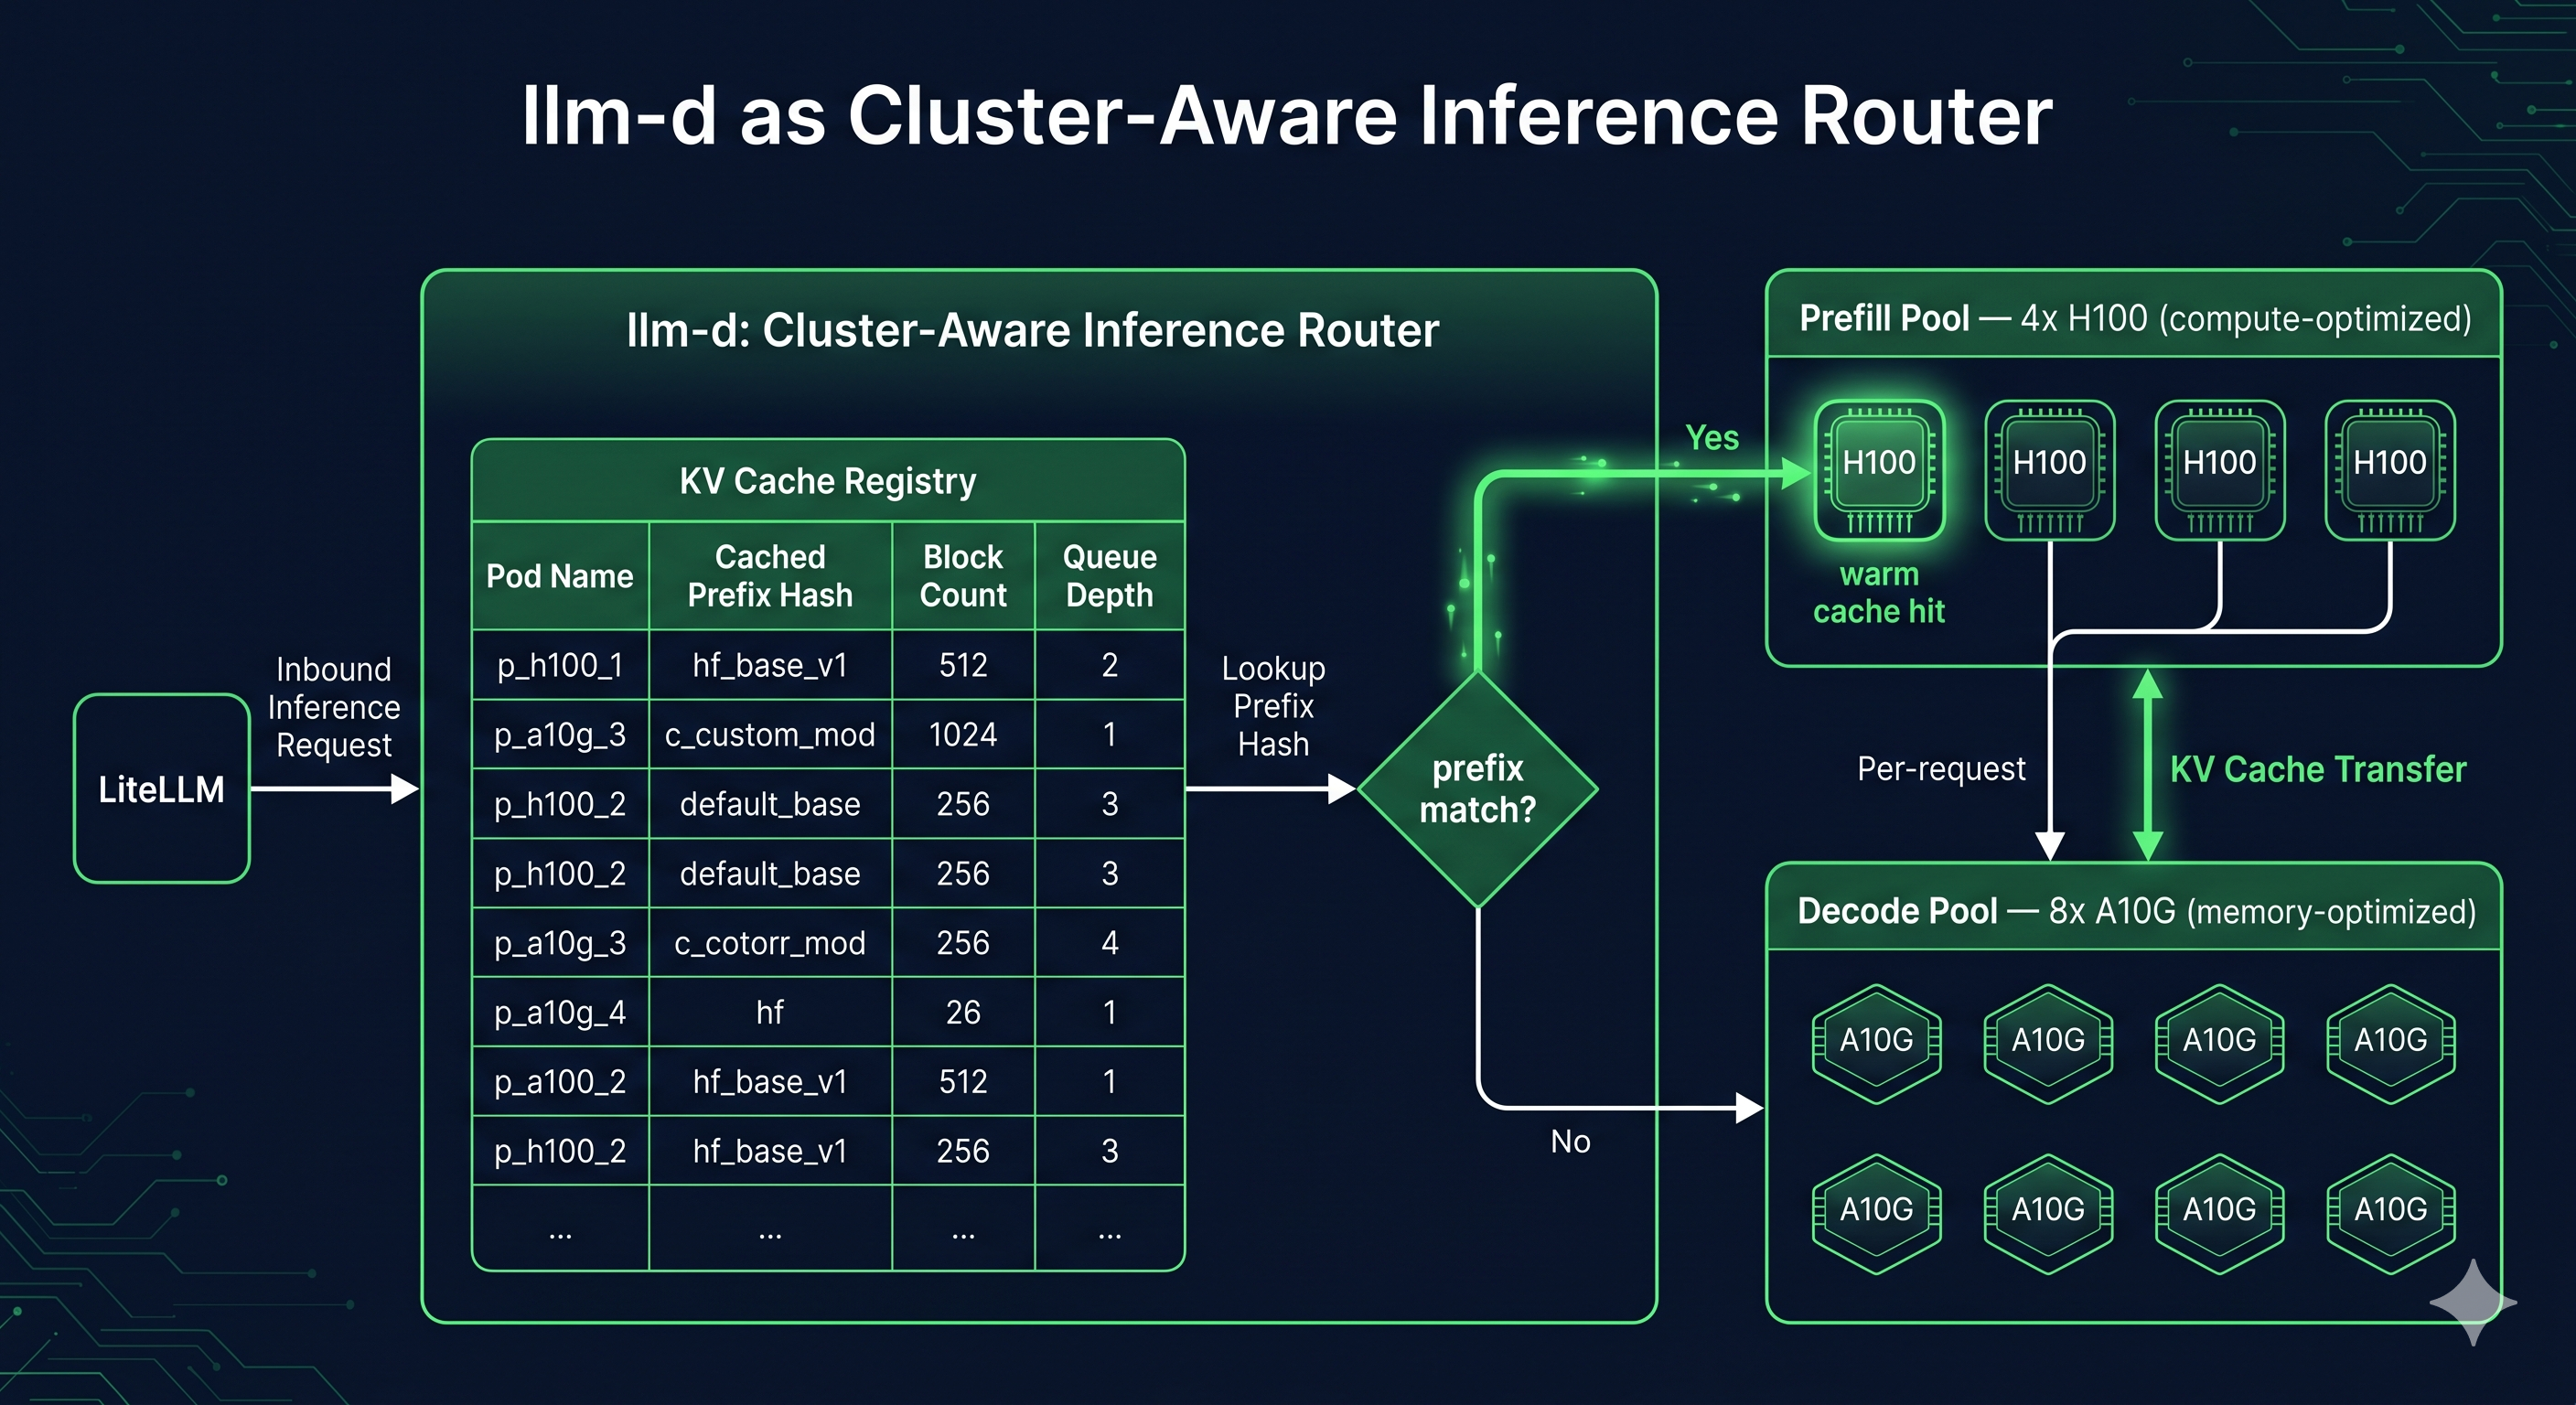
<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/llm-d.png" alt="llm-d as a cluster-aware inference router showing a KV Cache Registry table driving routing decisions, with separate Prefill Pool (4x H100) and Decode Pool (8x A10G) and a KV state transfer arrow between them" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    llm-d as a cluster-aware inference router. Requests arrive from LiteLLM on the left. Inside llm-d, a KV Cache Registry table tracks each replica by pod name, cached prefix hash, block count, and queue depth. A routing decision diamond reads from that table: if a prefix match exists, the request is sent to the specific replica holding the warm cache — skipping full prefill; if no match, it routes to any available replica. On the right, two distinct GPU pools handle separated workloads: the Prefill Pool (4x H100, compute-optimized) and the Decode Pool (8x A10G, memory-optimized), connected by a KV state transfer arrow showing how computed KV blocks move from prefill to decode once the input phase completes.
  </figcaption>
</figure>

<hr />

<h2 id="layer-5--gpu-worker-vllm--tensorrt-llm--tgi">Layer 5 — GPU Worker (vLLM / TensorRT-LLM / TGI)</h2>

<p><strong>What it does:</strong> Tokenization, prefill, decode loop, KV cache management. This is where inference actually happens and tokens are generated.</p>
<p>The internals — <a href="https://arxiv.org/abs/2309.06180">PagedAttention</a>, continuous batching, KV cache lifecycle, TTFT vs ITL, why decode is memory-bound — are covered in depth in my <a href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/14/re-introduction-to-inference.html">inference walkthrough</a>. Anyscale’s post on <a href="https://www.anyscale.com/blog/continuous-batching-llm-inference">continuous batching</a> is also worth reading for the throughput argument. What matters here is what the GPU worker exposes upward to llm-d and the configuration decisions that affect production stability.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># vLLM Deployment — decode pool</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">apps/v1</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">Deployment</span>
<span class="na">metadata</span><span class="pi">:</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s">vllm-decode-pool</span>
  <span class="na">namespace</span><span class="pi">:</span> <span class="s">llm-serving</span>
<span class="na">spec</span><span class="pi">:</span>
  <span class="na">replicas</span><span class="pi">:</span> <span class="m">8</span>
  <span class="na">selector</span><span class="pi">:</span>
    <span class="na">matchLabels</span><span class="pi">:</span>
      <span class="na">pool</span><span class="pi">:</span> <span class="s">decode</span>
  <span class="na">template</span><span class="pi">:</span>
    <span class="na">spec</span><span class="pi">:</span>
      <span class="na">containers</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">vllm</span>
          <span class="na">image</span><span class="pi">:</span> <span class="s">vllm/vllm-openai:latest</span>
          <span class="na">args</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">--model"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">meta-llama/Llama-3.1-70B-Instruct"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">--served-model-name"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">llama3-70b-instruct"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">--max-model-len"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">8192"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">--tensor-parallel-size"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">4"</span>                <span class="c1"># Split model weights across 4 GPUs on this node</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">--gpu-memory-utilization"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">0.90"</span>            <span class="c1"># Never 1.0 — CUDA needs headroom for runtime allocations</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">--enable-prefix-caching"</span>
            <span class="pi">-</span> <span class="s2">"</span><span class="s">--disable-log-requests"</span>  <span class="c1"># Log at L2/L3; avoid double-logging at high throughput</span>
          <span class="na">resources</span><span class="pi">:</span>
            <span class="na">limits</span><span class="pi">:</span>
              <span class="na">nvidia.com/gpu</span><span class="pi">:</span> <span class="m">4</span>  <span class="c1"># Must match --tensor-parallel-size exactly</span>
          <span class="na">ports</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="na">containerPort</span><span class="pi">:</span> <span class="m">8000</span>
          <span class="na">env</span><span class="pi">:</span>
            <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">VLLM_PROMETHEUS_ENABLED</span>
              <span class="na">value</span><span class="pi">:</span> <span class="s2">"</span><span class="s">1"</span>        <span class="c1"># These metrics are what llm-d reads for scheduling decisions</span>
          <span class="na">readinessProbe</span><span class="pi">:</span>
            <span class="na">httpGet</span><span class="pi">:</span>
              <span class="na">path</span><span class="pi">:</span> <span class="s">/health</span>
              <span class="na">port</span><span class="pi">:</span> <span class="m">8000</span>
            <span class="na">initialDelaySeconds</span><span class="pi">:</span> <span class="m">30</span>
            <span class="na">periodSeconds</span><span class="pi">:</span> <span class="m">10</span>
</code></pre></div></div>

<p><code class="language-plaintext highlighter-rouge">--gpu-memory-utilization 0.90</code> matters more than it looks. vLLM uses this value to pre-allocate its KV cache block pool at startup. At 1.0 there’s no headroom left for CUDA runtime allocations — under load you get OOM crashes with no graceful degradation. I run 0.90 in production and haven’t had an unplanned OOM since making that change. The <a href="https://docs.vllm.ai/en/latest/serving/engine_args.html">vLLM engine arguments reference</a> has the full list of tunable parameters if you want to go further.</p>

<h3 id="tensor-parallelism-and-pipeline-parallelism">Tensor Parallelism and Pipeline Parallelism</h3>

<p>Most production deployments of 70B+ parameter models require parallelism — the model simply doesn’t fit in a single GPU’s VRAM. vLLM supports two strategies and you’ll almost certainly need to reason about both.</p>

<p><strong>Tensor parallelism (TP)</strong> splits a model’s weight matrices across multiple GPUs on the same node. Each GPU holds a shard of every layer, and they cooperate on every single forward pass using <a href="https://developer.nvidia.com/nccl">NCCL</a> all-reduce operations. <code class="language-plaintext highlighter-rouge">--tensor-parallel-size 4</code> means one logical replica is served by 4 GPUs working together. The key constraint: <strong>your <code class="language-plaintext highlighter-rouge">nvidia.com/gpu</code> pod resource request must equal your TP size.</strong> Mismatch these and vLLM either fails to start or silently under-uses the hardware.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Model: Llama-3.1-70B  (~140GB in bf16)
Single A100 80GB VRAM → doesn't fit
TP=2 across 2x A100 80GB → 70GB per GPU → fits with headroom
TP=4 across 4x A100 80GB → 35GB per GPU → fits comfortably, more KV cache room
</code></pre></div></div>

<p>The tradeoff with TP is that every decode step requires an all-reduce across all N GPUs. This adds ~0.5–2ms of inter-GPU communication latency per token, which is negligible on NVLink but noticeable over PCIe. Keep TP within a single node on fast interconnect whenever possible.</p>

<p><strong>Pipeline parallelism (PP)</strong> splits the model’s <em>layers</em> across multiple nodes rather than splitting each layer across GPUs. Node 1 runs layers 1–40, node 2 runs layers 41–80. Requests flow through the pipeline sequentially. PP is the right tool when your model is too large for a single node even with TP, but it introduces pipeline bubbles — nodes idle waiting for the previous stage to finish. In practice, most teams reach for TP first and only add PP when they’re running models at the 405B+ scale.</p>

<p><strong>How this interacts with llm-d:</strong> llm-d routes at the replica level. A replica with TP=4 looks like a single logical worker to llm-d — it routes a request to that replica, and the 4-GPU coordination happens transparently inside the pod. Your <code class="language-plaintext highlighter-rouge">InferenceModel</code> CRD’s <code class="language-plaintext highlighter-rouge">nvidia.com/gpu: 4</code> in the decode pool spec should reflect the TP size you’ve chosen. If you later change TP, update both the vLLM args and the CRD resource limits together.</p>

<p><strong>Inference engine selection:</strong></p>

<table>
  <thead>
    <tr>
      <th>Engine</th>
      <th>Reach for it when</th>
      <th>Avoid it when</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong><a href="https://github.com/vllm-project/vllm">vLLM</a></strong></td>
      <td>Production multi-user serving, llm-d integration</td>
      <td>Local dev, single user</td>
    </tr>
    <tr>
      <td><strong><a href="https://github.com/NVIDIA/TensorRT-LLM">TensorRT-LLM</a></strong></td>
      <td>Maximum throughput on a fixed NVIDIA hardware config</td>
      <td>You need model flexibility or multi-cloud</td>
    </tr>
    <tr>
      <td><strong><a href="https://github.com/huggingface/text-generation-inference">TGI</a></strong></td>
      <td>You’re deep in the HuggingFace ecosystem</td>
      <td>You need aggressive throughput optimization</td>
    </tr>
    <tr>
      <td><strong><a href="https://github.com/ollama/ollama">Ollama</a></strong></td>
      <td>Local development, Apple Silicon, single-user experiments</td>
      <td>Any concurrent production traffic</td>
    </tr>
  </tbody>
</table>

<p><strong>Scalability:</strong> PagedAttention enables 2–4x more concurrent requests versus naive KV allocation. Continuous batching keeps GPU utilization high even when request lengths vary widely. TP lets you serve models that would otherwise be impossible to run, at the cost of tighter node topology requirements.</p>

<p><strong>Reliability:</strong> KV cache eviction prevents OOM at the cost of latency spikes for the evicted requests — which is the right tradeoff. <code class="language-plaintext highlighter-rouge">/health</code> endpoint for readiness and liveness probes. Graceful shutdown drains in-flight requests before terminating.</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/vllm-gpu-worker.png" alt="vLLM GPU worker cutaway showing the left-to-right flow from Tokenizer through Scheduler, Prefill (compute-bound), KV Cache block grid, Decode Loop (memory-bound), and Detokenizer, with TTFT and ITL annotations and a Prometheus metrics sidebar" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    A cutaway view of a vLLM GPU worker, left to right. An HTTP request enters a CPU-side Tokenizer, passes through the Scheduler, then enters the GPU section (orange border) where two distinct phases run: Prefill (compute-bound, processes all input tokens in parallel) feeds into a KV Cache block grid — shown as a partially filled matrix of allocated and free blocks — which in turn feeds the Decode Loop (memory-bound, generates one token per step). Output tokens pass back through a CPU-side Detokenizer and stream to the client. TTFT is annotated as the span from request arrival to the first decoded token. ITL is annotated as the interval between consecutive decoded tokens. A sidebar lists the key Prometheus metrics exported by this worker — the same signals llm-d reads to make scheduling decisions. For tensor-parallel deployments (TP=4), NCCL all-reduce operations synchronize GPU shards after each layer inside the GPU section.
  </figcaption>
</figure>

<hr />

<h2 id="what-to-instrument-at-each-layer">What to Instrument at Each Layer</h2>

<p>These are the metrics you watch in production to know the system is healthy and catch problems before users do — not a pre-launch checklist.</p>

<p><strong>NGINX — connection saturation and upstream latency</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>nginx_connections_active           # Are you close to worker_connections limit?
nginx_upstream_response_time_ms    # p95/p99 latency from NGINX's perspective
nginx_upstream_connect_time_ms     # Spikes here mean L3 is slow to accept connections
</code></pre></div></div>

<p><strong>Kong — quota headroom and 429 rate</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kong_http_requests_total{code="429"}   # Rising 429s = consumers hitting quota
kong_upstream_latency_ms               # Time Kong adds before forwarding
quota_headroom_percent per consumer    # How close is each tenant to their limit?
</code></pre></div></div>

<p><strong>LiteLLM — classification latency and routing distribution</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>litellm_request_duration_seconds    # End-to-end L3 latency
litellm_cache_hit_rate              # Below 0.20 on a Q&amp;A workload is worth investigating
litellm_fallback_count_total        # Rising fallbacks = primary cluster has a problem
</code></pre></div></div>

<p><strong>llm-d — cache hit rate, queue depth, prefill vs decode split</strong></p>

<p>The cache hit rate is the single most important metric at this layer. Everything else follows from it.</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>llmd_kv_cache_hit_rate              # Target &gt; 0.5 for workloads with shared system prompts
llmd_queue_depth_per_replica        # Alert if any replica queue &gt; 10
llmd_prefill_latency_seconds        # Should be low if prefix caching is working
llmd_decode_latency_seconds         # Scales with KV cache size; memory-bound
llmd_routing_decisions{reason}      # cache_hit vs cold_start distribution
</code></pre></div></div>

<p><strong>vLLM — GPU KV cache utilization, batch size, generation throughput</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>vllm:gpu_cache_usage_perc           # Alert at 0.85 — at 0.95 you're already evicting
vllm:num_requests_waiting           # Queue depth this replica can't yet serve
vllm:gpu_prefix_cache_hit_rate      # Local prefix cache effectiveness
vllm:time_to_first_token_seconds    # TTFT histogram — your primary latency SLO metric
vllm:time_per_output_token_seconds  # ITL histogram — decode throughput per user
vllm:generation_tokens_total        # Total tokens generated — maps directly to GPU cost
</code></pre></div></div>

<p>The relationship between layers matters for incident diagnosis. A spike in <code class="language-plaintext highlighter-rouge">vllm:time_to_first_token_seconds</code> with a simultaneous drop in <code class="language-plaintext highlighter-rouge">llmd_kv_cache_hit_rate</code> means you’ve lost prefix cache warmth — look for a recent deployment that cleared pod state. A spike in TTFT with a stable cache hit rate but rising <code class="language-plaintext highlighter-rouge">vllm:gpu_cache_usage_perc</code> means you’re running out of KV capacity and need more decode pods, not better routing.</p>

<hr />

<h2 id="full-request-path-end-to-end">Full Request Path, End to End</h2>

<p>Walk a single request: <code class="language-plaintext highlighter-rouge">POST /v1/chat/completions</code> with a 4k-token system prompt and a 200-token user turn.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>POST /api/v1/chat/completions
[4096-token system prompt + 200-token user turn]
     |
     v
[L1] NGINX
     - TCP accepted, TLS terminated
     - Connection limit checked — within bounds
     - WAF: request inspected, size limit checked (well under 10MB cap)
     - Routed to LLM gateway (L3)
     - proxy_buffering off: SSE will stream through cleanly
     |
     v
[L2] Kong
     - JWT / API key validated → consumer: "internal-team-a"
     - TPM quota checked: 47 of 500 req/min used — allowed
     - Trace ID stamped on request headers
     - Audit log entry written: consumer + timestamp + path
     |
     v
[L3] LiteLLM
     - Semantic cache lookup: has this exact prompt been seen? → miss
     - Routing decision: internal cluster healthy → route there
     - Request forwarded to llm-d with trace ID preserved
     |
     v
[L4] llm-d
     - System prompt hashed → looked up in KV cache index
     - Match found: replica R2 has the 4096-token prefix cached
     - Request routed to R2 specifically
     - Decode queue depth on R2: 2 active requests — within threshold
     |
     v
[L5] vLLM on replica R2 (TP=4 across 4x A100)
     - Tokenization: 200 new user tokens (system prompt already tokenized and cached)
     - Prefill: only the 200-token user turn computed — 4096 prefix tokens skipped
     - Each GPU shard processes its weight slice; NCCL all-reduce syncs after each layer
     - Decode loop begins: tokens generated one at a time, streamed back
     - KV blocks appended for the new 200 tokens
     - Response streams back token-by-token through the same chain
     |
     v (response path)
[L2] Kong
     - Token count recorded against consumer quota bucket
     |
[L1] NGINX
     - SSE frames streamed to client as they arrive
     - Access log entry written

Total routing overhead L1-L4: ~3-8ms
What your users are waiting on: GPU compute at L5
The system prompt's KV cache being warm on R2 saved ~400ms of prefill.
</code></pre></div></div>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/serving-request.png" alt="UML sequence diagram showing a single LLM request flowing through Client, NGINX, Kong, LiteLLM, llm-d, and vLLM R2, with a KV cache hit annotation on the llm-d routing step and streaming token responses returning through the same chain" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    End-to-end sequence for a single POST /v1/chat/completions request carrying a 4096-token system prompt and a 200-token user turn. The request moves left to right through seven participants: Client → NGINX (TLS termination) → Kong (API key validation, trace ID stamped) → LiteLLM (cache miss, routes to internal cluster) → llm-d (KV cache registry hit — replica R2 already holds the system prompt prefix) → vLLM R2 (prefill runs on the 200 new tokens only; 4096 prefix tokens skipped) → GPU. The note on the llm-d → vLLM R2 arrow calls out the cache hit explicitly. Token responses stream back through the same chain as repeated return arrows, reflecting SSE delivery. Kong records the token count against the consumer quota on the return path.
  </figcaption>
</figure>

<hr />

<h2 id="decision-matrix-which-layers-do-you-actually-need">Decision Matrix: Which Layers Do You Actually Need?</h2>

<table>
  <thead>
    <tr>
      <th>Stage</th>
      <th>Concurrent Users</th>
      <th>Stack</th>
      <th>What you’re solving for</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Internal / prototype</strong></td>
      <td>&lt; 50</td>
      <td>NGINX → vLLM</td>
      <td>One vLLM instance handles this comfortably; adding routing layers is pure overhead at this scale</td>
    </tr>
    <tr>
      <td><strong>Early production</strong></td>
      <td>50–500</td>
      <td>NGINX → LiteLLM → vLLM</td>
      <td>You’ll hit provider RPM limits and need fallback chains before an incident forces them on you</td>
    </tr>
    <tr>
      <td><strong>Growth stage</strong></td>
      <td>500–5,000</td>
      <td>NGINX → Kong → LiteLLM → vLLM</td>
      <td>Per-tenant isolation and compliance audit trails become real requirements — Kong earns its place here</td>
    </tr>
    <tr>
      <td><strong>Scale / GPU efficiency</strong></td>
      <td>5,000+</td>
      <td>NGINX → Kong → LiteLLM → llm-d → vLLM</td>
      <td>KV cache hit rate becomes a meaningful GPU cost lever; llm-d’s operational overhead now pays for itself</td>
    </tr>
    <tr>
      <td><strong>Enterprise / regulated</strong></td>
      <td>Any</td>
      <td>Full stack + custom L3</td>
      <td>Data residency, PII routing, granular audit — these can’t be bolted on later</td>
    </tr>
  </tbody>
</table>

<p>The principal engineer’s test for each layer you add: if I removed this tomorrow, what specifically breaks? If you can’t answer that concretely, the layer isn’t earning its place yet.</p>

<hr />

<h2 id="closing">Closing</h2>

<p>None of this is over-engineering. Each layer exists because something specific breaks without it. NGINX without <code class="language-plaintext highlighter-rouge">proxy_buffering off</code> breaks streaming silently. A proxy without a fallback chain means a provider outage is your outage. llm-d without KV cache routing means you’re paying GPU costs for work that’s already been done on another pod.</p>

<p>Start with <code class="language-plaintext highlighter-rouge">NGINX → LiteLLM → vLLM</code>. That’s a real production stack that serves real traffic well. Add layers as the specific pressure they solve becomes concrete — not before. The stack I’ve laid out here is the shape of where you’ll end up as scale and compliance requirements grow.</p>

<p>The five layers above exist because the tools your team already knows — NGINX, Kong, Kubernetes — were built for networking problems. LLM serving is a scheduling problem wearing networking clothes, and each layer is one part of that disguise being pulled off.</p>

<p>The specific tools here — especially at L4 — will change faster than any other layer in this stack. llm-d is pre-v1 and the operator API is still settling. The shape of the stack won’t change. The components will.</p>

<p>The GPU is the expensive part. Everything above it exists to make sure that GPU spends its cycles on inference — not on routing errors, redundant compute, or requests that should have been served from cache.</p>

<hr />

<p><em>Karthika Raghavan — infrastructure engineer, 11+ years in distributed systems across D-Wave, Enbala, MasterCard, and Cisco. Currently focused on LLM serving infrastructure and inference optimization. The experiments behind this post ran on everything from a Mac Mini M4 to Lambda Labs GH200 clusters.</em></p>

<table>
  <tbody>
    <tr>
      <td>*GitHub: <a href="https://github.com/kraghavan">kraghavan</a></td>
      <td>LinkedIn: <a href="https://linkedin.com/in/karthikaraghavan">Karthika Raghavan</a>*</td>
    </tr>
  </tbody>
</table>

<hr />

<p><strong>Related reading:</strong></p>

<p><em>My posts:</em></p>
<ul>
  <li><a href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/14/re-introduction-to-inference.html">What Is LLM Inference, Really? A Deep Technical Walkthrough</a> — L5 internals: PagedAttention, KV cache, TTFT vs ITL</li>
</ul>

<p><em>External references:</em></p>
<ul>
  <li><a href="https://docs.vllm.ai/en/latest/automatic_prefix_caching/apc.html">vLLM — Automatic Prefix Caching</a></li>
  <li><a href="https://docs.vllm.ai/en/latest/serving/engine_args.html">vLLM Engine Arguments Reference</a></li>
  <li><a href="https://arxiv.org/abs/2309.06180">PagedAttention paper (Kwon et al., 2023)</a></li>
  <li><a href="https://www.anyscale.com/blog/continuous-batching-llm-inference">Continuous Batching: A New Trick for LLM Throughput</a> — Anyscale</li>
  <li><a href="https://github.com/llm-d/llm-d">llm-d GitHub</a></li>
  <li><a href="https://kserve.github.io/website/latest/">KServe documentation</a></li>
  <li><a href="https://docs.konghq.com/hub/kong-inc/ai-proxy/">Kong AI Gateway plugin</a></li>
  <li><a href="https://docs.litellm.ai/docs/">LiteLLM documentation</a></li>
  <li><a href="https://github.com/owasp-modsecurity/ModSecurity">ModSecurity / OWASP Core Rule Set</a></li>
  <li><a href="https://nginx.org/en/docs/http/ngx_http_proxy_module.html#proxy_buffering">NGINX proxy_buffering module reference</a></li>
  <li><a href="https://developer.nvidia.com/nccl">NVIDIA NCCL — GPU communication library</a></li>
  <li><a href="https://docs.vllm.ai/en/latest/serving/distributed_serving.html">vLLM distributed inference and serving</a></li>
</ul>]]></content><author><name>Karthika Raghavan</name></author><summary type="html"><![CDATA[The LLM Serving Stack You Actually Need: From NGINX to llm-d to GPU]]></summary></entry><entry><title type="html">I Built a Five-Agent SRE War Room and Grafana Watched Every Token</title><link href="https://kraghavan.ca/llm-infrastructure/observability/grafana/2026/04/25/sre-war-room-grafana-observbility.html" rel="alternate" type="text/html" title="I Built a Five-Agent SRE War Room and Grafana Watched Every Token" /><published>2026-04-25T00:00:00+00:00</published><updated>2026-04-25T00:00:00+00:00</updated><id>https://kraghavan.ca/llm-infrastructure/observability/grafana/2026/04/25/sre-war-room-grafana-observbility</id><content type="html" xml:base="https://kraghavan.ca/llm-infrastructure/observability/grafana/2026/04/25/sre-war-room-grafana-observbility.html"><![CDATA[<p>On April 21, 2026, Grafana Labs quietly dropped a blog post: <em>AI Observability for Agents in Grafana Cloud</em>. I read it, got excited, and spent the next few days building something to put it through its paces. By April 25th I had five Claude agents handling fake production incidents — a P1 Redis split-brain, a DDoS on the CDN, a Postgres connection pool exhausted at 512/512 — and Grafana was watching every single token.</p>

<p>The hypothesis: if you instrument a multi-agent system properly, you can observe it the same way you observe infrastructure. Conversations become traces. Token costs become metrics. Agent quality becomes an SLO.</p>

<p>This is the story of testing that hypothesis. The build, the dashboard, the moment it looked like it worked, the moment I realised it hadn’t — and what the gap reveals about where AI agent systems actually break. I’ll be honest about all of it.</p>

<hr />

<h2 id="the-context-why-this-matters">The Context: Why This Matters</h2>

<p>I’ve spent more than half a decade making distributed systems observable. Prometheus metrics, distributed traces, structured logs, SLOs, alerting pipelines. When a service degrades, I know where to look.</p>

<p>LLM agents have none of this. Until now, “observability” for an AI agent meant reading stdout and hoping the error messages were useful. Token costs were buried in billing dashboards three clicks deep. Quality was vibes-based — you knew something was off when your users told you. There was no equivalent of a trace showing “this is where the agent went wrong.”</p>

<p><strong>Grafana AI Observability changes the mental model.</strong> Conversations become traces. Token counts become metrics. Agent quality becomes an SLO. The existing Grafana workflows — alerting, dashboards, explore, drill-down — work on AI data the same way they work on infrastructure data.</p>

<p>That’s the dream. This post is about testing it in the real world, four days after launch.</p>

<hr />

<h2 id="the-plan-an-ai-powered-sre-war-room">The Plan: An AI-Powered SRE War Room</h2>

<p>The idea was simple: build a multi-agent system that mirrors how a real SRE team handles incidents, then instrument it completely with Grafana’s new Sigil SDK.</p>

<p>Five agents, each with a distinct role:</p>

<table>
  <thead>
    <tr>
      <th>Agent</th>
      <th>SRE Equivalent</th>
      <th>Model</th>
      <th>What It Does</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">triage-agent</code></td>
      <td>First responder</td>
      <td>Claude Haiku</td>
      <td>Reads the alert, classifies severity (P1-P4), identifies blast radius</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">runbook-agent</code></td>
      <td>The senior who’s seen it all</td>
      <td>Claude Sonnet</td>
      <td>Looks up the right runbook, produces an ordered remediation plan</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">executor-agent</code></td>
      <td>The engineer who types commands</td>
      <td>Claude Haiku</td>
      <td>Simulates executing each runbook step (dry-run — no real infra harmed)</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">postmortem-agent</code></td>
      <td>The reflective senior</td>
      <td>Claude Sonnet</td>
      <td>Writes a structured post-mortem: timeline, root cause, action items</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cost-cop-agent</code></td>
      <td>The FinOps person nobody invited</td>
      <td>Claude Haiku</td>
      <td>Reads Sigil telemetry, flags expensive agents, suggests model swaps</td>
    </tr>
  </tbody>
</table>

<p>The model selection was deliberate. Triage and execution are fast, structured tasks — Haiku handles them in under 3 seconds. Runbook planning and post-mortem writing need reasoning across complex context — that’s Sonnet territory. The cost-cop agent using Haiku to audit the Sonnet agents is the most efficient use of irony I’ve found in systems design.</p>

<p><strong>Constraints:</strong> Everything runs on an M4 Mac Mini. No GPU. No cloud Kubernetes. Total demo budget: under $2 in Anthropic API credits.</p>

<hr />

<h2 id="the-setup-twenty-fake-incidents-that-feel-real">The Setup: Twenty Fake Incidents That Feel Real</h2>

<p>The system needed incident volume. I built a library of 20 canned PagerDuty-style alert payloads covering the greatest hits of production failure:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"incident_id"</span><span class="p">:</span><span class="w"> </span><span class="s2">"INC-0001"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"title"</span><span class="p">:</span><span class="w"> </span><span class="s2">"payment-service: P1 OOMKilled pods - 3 replicas down"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"severity_hint"</span><span class="p">:</span><span class="w"> </span><span class="s2">"P1"</span><span class="p">,</span><span class="w">
  </span><span class="nl">"affected_services"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"payment-service"</span><span class="p">,</span><span class="w"> </span><span class="s2">"payment-worker"</span><span class="p">,</span><span class="w"> </span><span class="s2">"checkout-api"</span><span class="p">],</span><span class="w">
  </span><span class="nl">"annotations"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"summary"</span><span class="p">:</span><span class="w"> </span><span class="s2">"Pod OOMKilled in payments namespace"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"description"</span><span class="p">:</span><span class="w"> </span><span class="s2">"Container exceeded memory limit of 512Mi. 3/5 replicas down. Revenue impact estimated at $4,200/min."</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>Each payload is realistic enough that the agents treat it as real. The triage agent doesn’t know it’s fake. It responds with genuine P1 urgency. That’s the point — the mocking is deliberate and specific, not random noise.</p>

<p>The incident library covers: OOM kills, connection pool exhaustion, Redis split-brain, TLS certificate expiry, etcd slow reads, CDN DDoS, CrashLoopBackOff with Kafka lag, Elasticsearch cluster RED, Istio sidecar memory leaks, GPU OOM on inference workloads.</p>

<p>An “incident blaster” fires these scenarios at configurable intervals:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>python <span class="nt">-m</span> scenarios.blaster <span class="nt">--count</span> 10 <span class="nt">--interval</span> 15
</code></pre></div></div>

<p><img src="/assets/images/sre-war-room/blaster-terminal.png" alt="The incident blaster terminal showing INC-0001 (DDoS) and INC-0002 (Redis split-brain) being processed" />
<em>The blaster in action. INC-0001 is a P1 CDN DDoS. INC-0002 is a Redis split-brain with dual master election. The ✅ Sigil line confirms telemetry is shipping.</em></p>

<hr />

<h2 id="the-orchestration-langgraph-state-machine">The Orchestration: LangGraph State Machine</h2>

<p>Each incident runs through a LangGraph state machine. One incident = one conversation = one Grafana thread.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Incident Alert → triage-agent → runbook-agent → executor-agent → postmortem-agent
                                                                        ↓
                                              LangGraph IncidentState (shared)
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">conversation_id</code> is the key insight. Every agent that touches an incident gets the same <code class="language-plaintext highlighter-rouge">conversation_id</code>. When Grafana receives four Sigil generations with the same ID, it threads them into a single conversation. You see the complete incident lifecycle — from raw alert to finished post-mortem — in one view.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">with</span> <span class="n">sigil_client</span><span class="p">.</span><span class="n">start_generation</span><span class="p">(</span>
    <span class="n">GenerationStart</span><span class="p">(</span>
        <span class="n">model</span><span class="o">=</span><span class="n">ModelRef</span><span class="p">(</span><span class="n">provider</span><span class="o">=</span><span class="s">"anthropic"</span><span class="p">,</span> <span class="n">name</span><span class="o">=</span><span class="s">"claude-haiku-4-5"</span><span class="p">),</span>
        <span class="n">conversation_id</span><span class="o">=</span><span class="n">incident_id</span><span class="p">,</span>   <span class="c1"># same ID across all 4 agents
</span>        <span class="n">agent_name</span><span class="o">=</span><span class="s">"triage-agent"</span><span class="p">,</span>
        <span class="n">system_prompt</span><span class="o">=</span><span class="n">SYSTEM_PROMPT</span><span class="p">,</span>
        <span class="n">tags</span><span class="o">=</span><span class="p">{</span><span class="s">"incident_id"</span><span class="p">:</span> <span class="n">incident_id</span><span class="p">},</span>
    <span class="p">)</span>
<span class="p">)</span> <span class="k">as</span> <span class="n">rec</span><span class="p">:</span>
    <span class="n">response</span> <span class="o">=</span> <span class="n">claude_client</span><span class="p">.</span><span class="n">messages</span><span class="p">.</span><span class="n">create</span><span class="p">(...)</span>
    <span class="n">rec</span><span class="p">.</span><span class="n">set_result</span><span class="p">(</span>
        <span class="nb">input</span><span class="o">=</span><span class="p">[</span><span class="n">user_text_message</span><span class="p">(</span><span class="n">alert_text</span><span class="p">)],</span>
        <span class="n">output</span><span class="o">=</span><span class="p">[</span><span class="n">assistant_text_message</span><span class="p">(</span><span class="n">response</span><span class="p">.</span><span class="n">content</span><span class="p">[</span><span class="mi">0</span><span class="p">].</span><span class="n">text</span><span class="p">)],</span>
    <span class="p">)</span>
</code></pre></div></div>

<p>That’s the entire instrumentation for one agent. Fifteen lines. The SDK handles token counting, latency tracking, and cost calculation automatically.</p>

<p><strong>A note on prompt design:</strong> Each agent’s system prompt is a strict output contract. The triage agent prompt, for example:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>You are a senior SRE triage specialist. Output ONLY valid JSON:
{
  "severity": "P1" | "P2" | "P3" | "P4",
  "affected_services": ["service-a"],
  "blast_radius": "single-region" | "multi-region" | "global",
  "triage_summary": "one paragraph"
}
Severity guide: P1 = complete outage, revenue impact, &gt;10k users...
Do not include markdown fences or any text outside the JSON object.
</code></pre></div></div>

<p>The “do not include markdown fences” instruction is violated by Claude Haiku consistently regardless. Hence <code class="language-plaintext highlighter-rouge">strip_fences()</code>. The larger issue is that structured output prompts work well for simple classification but break down when the output space is ambiguous — which is exactly what happens on the complex incidents that end up escalated.</p>

<hr />

<h2 id="the-dashboard-what-grafana-actually-shows">The Dashboard: What Grafana Actually Shows</h2>

<h3 id="ai-observability-landing-page">AI Observability Landing Page</h3>

<p><img src="/assets/images/sre-war-room/landing-page.png" alt="Grafana AI Observability landing page showing 24 conversations and 5 agents" />
<em>The AI Observability landing page after running 24 incidents. 5 agents registered, 24 conversations tracked.</em></p>

<p>The landing page summarises the last 24 hours: total conversations, average calls per conversation, token totals, cost. After running 10+ incidents you start to see the shape of your agent workload at a glance.</p>

<h3 id="conversations-view--the-main-event">Conversations View — The Main Event</h3>

<p><img src="/assets/images/sre-war-room/conversations-view.png" alt="Grafana AI Observability Conversations view showing 24 conversations with agent breakdown" />
<em>24 conversations, 3.88 average calls per conversation (exactly right for a 4-agent pipeline). Each row is one incident. The activity chart shows the cadence of the blaster runs.</em></p>

<p>Each row is one incident run. The columns show conversation ID, duration, call count, which agents participated, and which models were used. The conversation activity chart maps exactly to when the blaster was running — you can literally see when I paused it to debug something.</p>

<p>Clicking into a conversation is where it gets genuinely useful.</p>

<h3 id="conversation-drilldown--where-the-real-value-lives">Conversation Drilldown — Where the Real Value Lives</h3>

<p><img src="/assets/images/sre-war-room/conversation-drilldown.png" alt="Single conversation drilldown showing triage-agent, runbook-agent, executor-agent, postmortem-agent with per-agent timing" />
<em>One incident, four agents. Triage: 2.08s (Haiku), runbook: 8.57s (Sonnet), executor: 7.58s (Haiku), postmortem: 21.61s (Sonnet). Total: 37.8 seconds from alert to post-mortem.</em></p>

<p>The per-agent breakdown on the left shows:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">triage-agent</code>: <strong>2.08s</strong> (Haiku, exactly what we want)</li>
  <li><code class="language-plaintext highlighter-rouge">runbook-agent</code>: <strong>8.57s</strong> (Sonnet reasoning through a complex runbook)</li>
  <li><code class="language-plaintext highlighter-rouge">executor-agent</code>: <strong>7.58s</strong> (Haiku simulating kubectl commands)</li>
  <li><code class="language-plaintext highlighter-rouge">postmortem-agent</code>: <strong>21.61s</strong> (Sonnet writing a full post-mortem)</li>
</ul>

<p>The right panel shows the actual content — the triage agent’s JSON classification, the runbook it matched, the alert context it processed. This is the debugging interface for AI agents that we’ve never had before.</p>

<p><img src="/assets/images/sre-war-room/conversation-postgres.png" alt="Conversation drilldown for Postgres P1 incident showing the full triage summary and matched runbook" />
<em>The Postgres P1 (connection pool exhausted — 512/512). The triage agent correctly identified P1 severity and matched the DB Connection Pool Exhaustion runbook. All visible in Grafana.</em></p>

<h3 id="agents-view--whos-doing-the-work">Agents View — Who’s Doing the Work</h3>

<p><img src="/assets/images/sre-war-room/agents-view.png" alt="Grafana Agents view showing all 5 agents with generation counts and cost breakdown" />
<em>All five agents registered. The ‘Top by Generations’ chart shows near-equal usage across triage, runbook, executor, and postmortem (23 each). The cost-cop-agent ran twice.</em></p>

<p>The Agent Footprint section on the right is interesting: triage-agent is actually the most expensive by token volume despite using Haiku, because it runs on every incident. The postmortem-agent costs less in aggregate despite using Sonnet, because its output is dense and well-structured.</p>

<hr />

<h2 id="the-cost-cop-an-ai-auditing-other-ais">The Cost Cop: An AI Auditing Other AIs</h2>

<p>Every 10 incidents, the cost-cop agent wakes up, queries Grafana’s API, and produces a FinOps report. That report — generated by a Haiku agent — gets shipped back to Grafana as its own conversation thread.</p>

<p><img src="/assets/images/sre-war-room/cost-cop-conversation.png" alt="Cost-cop agent conversation thread in Grafana showing FinOps analysis with model swap recommendations" />
<em>The cost-cop agent’s conversation in Grafana. It identified postmortem-agent consuming 60% of total spend and recommended swapping to Haiku for an 83% cost reduction. This analysis is itself a Grafana conversation.</em></p>

<p>The output is pointed:</p>

<blockquote>
  <p><strong>postmortem-agent is your problem child.</strong> 1-hour cost: $1.81 (60% of total spend). Projected monthly: $1,294. Postmortem generation is templated, deterministic work — <strong>swap to Haiku immediately.</strong> Projected savings: ~$1,050/month. Risk: Low. Test on 5% traffic first.</p>
</blockquote>

<p>The cost-cop is Haiku auditing Sonnet. A cheap model correctly identifying that expensive models are doing work they’re overqualified for. That’s the FinOps signal that used to require a dedicated billing dashboard. Now it’s a Grafana conversation.</p>

<p>At this point in the experiment, everything was working. Telemetry flowing. Dashboard populated. Costs tracked. Agents completing pipelines. The hypothesis looked confirmed.</p>

<p>Then I looked at whether the agents were actually <em>right</em>.</p>

<hr />

<h2 id="when-the-system-was-confidently-wrong">When the System Was Confidently Wrong</h2>

<p>The auth-service JWT rotation incident (INC-0006 in the blaster output) is the one that made me sit up.</p>

<p>The alert: <code class="language-plaintext highlighter-rouge">auth-service: 401 error rate spike — 23% of requests failing</code>. The triage agent correctly classified this as P1 with global blast radius — JWT failures cascade into api-gateway and mobile-bff. Severity: correct. So far so good.</p>

<p>The runbook-agent matched a “JWT Key Rotation Authentication Failure Remediation” runbook and produced a reasonable-sounding 8-step plan. The executor simulated running those steps: checking pod logs, verifying secret mounts, rotating the signing key, rolling the pods. All steps returned <code class="language-plaintext highlighter-rouge">status: ok</code>. The executor declared <code class="language-plaintext highlighter-rouge">resolution_status: "escalated"</code> — which in this case was correct, but for the wrong reason. It escalated because one simulated step failed, not because it understood the actual blast radius of a JWT rotation gone wrong.</p>

<p>Here’s the problem: a real JWT rotation failure requires coordinating across every service that holds the public key. The runbook covered auth-service. It did not cover the downstream services that cached the old key. The executor had no way to know this, because the static runbook lookup doesn’t model service dependencies. The pipeline produced a plausible-looking post-mortem with actionable steps — and none of those steps would have actually fixed the problem.</p>

<p><strong>This is the failure mode that matters.</strong> Not malformed JSON. Not truncated responses. An agent that’s confidently correct at the individual step level but wrong at the system level, producing documentation that would mislead an on-call engineer.</p>

<blockquote>
  <p><strong>This is not a prompt problem. It’s a systems problem.</strong>
Static runbooks fail because systems aren’t static.</p>
</blockquote>

<p>The fix is architecture: the runbook-agent needs a dependency graph, not a keyword-match against a flat library of procedures.</p>

<p>What that graph looks like matters. A static service map (hardcoded in config) would have caught the JWT case — auth-service depends on api-gateway depends on mobile-bff, so any auth rotation plan must include key propagation across all three. A runtime-derived graph (built from OTel traces) would be more accurate but adds infrastructure complexity. A config-derived graph sitting in the platform layer is probably the right starting point: owned by the platform team, consumed by the runbook-agent as context injected into the prompt alongside the runbook data.</p>

<p>The ownership question is the harder one. If the dependency graph lives in the agent’s prompt context, it becomes a prompt engineering problem that degrades as services change. If it lives in the platform and is injected at runtime, it becomes an infrastructure contract. That’s a different kind of system to build and operate.</p>

<p>And this failure is invisible in the Grafana dashboard — the conversation shows 4 agents, all OK, resolution escalated. You’d have to read the actual post-mortem to catch it.</p>

<hr />

<h2 id="the-setup-what-was-hard">The Setup: What Was Hard</h2>

<p>This is a four-day-old public preview. I am not going to pretend it was smooth. Here is the honest accounting:</p>

<h3 id="the-endpoint-discovery-problem">The Endpoint Discovery Problem</h3>

<p>The Sigil SDK defaults to <code class="language-plaintext highlighter-rouge">localhost:8080</code>. The Grafana setup wizard shows <code class="language-plaintext highlighter-rouge">localhost:8080</code>. Neither of those is where you actually send data in Grafana Cloud.</p>

<p>After trying:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">&lt;my-grafana-username&gt;.grafana.net/api/sigil/v1/generations:export</code> → 404</li>
  <li><code class="language-plaintext highlighter-rouge">&lt;my-grafana-username&gt;.grafana.net/api/v1/generations:export</code> → 404</li>
  <li><code class="language-plaintext highlighter-rouge">localhost:4317</code> (Alloy’s OTLP port) → <code class="language-plaintext highlighter-rouge">UNIMPLEMENTED: unknown service sigil.v1.GenerationIngestService</code></li>
  <li><code class="language-plaintext highlighter-rouge">localhost:8080</code> → connection refused</li>
</ul>

<p>The answer was buried in <code class="language-plaintext highlighter-rouge">Administration → Plugins → AI Observability → Connection tab</code>.</p>

<p><img src="/assets/images/sre-war-room/plugin-config.png" alt="AI Observability plugin configuration page showing sigil-prod-ca-east-0.grafana.net endpoint" />
<em>The actual endpoint: sigil-prod-ca-east-0.grafana.net. Not documented. Found by clicking through the plugin Configuration tab.</em></p>

<p><strong>The correct endpoint:</strong> <code class="language-plaintext highlighter-rouge">https://sigil-prod-ca-east-0.grafana.net</code><br />
<strong>The correct auth:</strong> Basic auth with Instance ID as username + Cloud Access Policy token as password<br />
<strong>The correct token scope:</strong> You need a Cloud Access Policy token with sigil write scope, <em>not</em> a service account token and <em>not</em> the OTLP token</p>

<p>Total time spent on authentication alone: approximately 90 minutes across five different token types, three endpoints, and two auth schemes.</p>

<p>For teams already running Grafana Cloud with established service accounts and Cloud Access Policies: this is a 10-minute task. For someone setting up from scratch on a 4-day-old SDK: it is a different experience.</p>

<h3 id="running-alloy">Running Alloy</h3>

<p>Rather than using Docker Compose, we ran the Grafana Alloy container directly — simpler, more transparent, and easier to debug:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>docker run <span class="nt">-d</span> <span class="se">\</span>
  <span class="nt">--name</span> war-room-alloy <span class="se">\</span>
  <span class="nt">-p</span> 4317:4317 <span class="nt">-p</span> 4318:4318 <span class="nt">-p</span> 8080:8080 <span class="nt">-p</span> 12345:12345 <span class="se">\</span>
  <span class="nt">-v</span> <span class="si">$(</span><span class="nb">pwd</span><span class="si">)</span>/alloy/config.alloy:/etc/alloy/config.alloy:ro <span class="se">\</span>
  <span class="nt">--env-file</span> .env <span class="se">\</span>
  grafana/alloy:latest <span class="se">\</span>
  run /etc/alloy/config.alloy <span class="nt">--server</span>.http.listen-addr<span class="o">=</span>0.0.0.0:12345
</code></pre></div></div>

<p><img src="/assets/images/sre-war-room/alloy-logs.png" alt="Grafana Alloy Docker logs showing OTLP receivers starting on ports 4317 and 4318" />
<em>Alloy running — GRPC receiver on 4317, HTTP receiver on 4318. The Prometheus remote write errors are Alloy’s self-metrics hitting the wrong regional endpoint; they don’t affect agent telemetry.</em></p>

<h3 id="claude-returns-markdown-fenced-json">Claude Returns Markdown-Fenced JSON</h3>

<p>Despite being told “output ONLY valid JSON — no markdown fences, no explanation,” Claude Haiku wraps responses in ` <code class="language-plaintext highlighter-rouge">json</code> ` blocks. Every time. Without fail.</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">strip_fences</span><span class="p">(</span><span class="n">text</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
    <span class="s">"""The fix that should have been in the system prompt."""</span>
    <span class="n">text</span> <span class="o">=</span> <span class="n">text</span><span class="p">.</span><span class="n">strip</span><span class="p">()</span>
    <span class="n">text</span> <span class="o">=</span> <span class="n">re</span><span class="p">.</span><span class="n">sub</span><span class="p">(</span><span class="sa">r</span><span class="s">'^```(?:json)?\s*'</span><span class="p">,</span> <span class="s">''</span><span class="p">,</span> <span class="n">text</span><span class="p">)</span>
    <span class="n">text</span> <span class="o">=</span> <span class="n">re</span><span class="p">.</span><span class="n">sub</span><span class="p">(</span><span class="sa">r</span><span class="s">'\s*```$'</span><span class="p">,</span> <span class="s">''</span><span class="p">,</span> <span class="n">text</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">text</span><span class="p">.</span><span class="n">strip</span><span class="p">()</span>
</code></pre></div></div>

<p>One line of regex. Took longer to figure out than it should have. Now it’s in every agent.</p>

<h3 id="the-http-vs-grpc-transport-confusion">The HTTP vs gRPC Transport Confusion</h3>

<p>The sigil-sdk defaults to gRPC. Grafana Alloy doesn’t implement the <code class="language-plaintext highlighter-rouge">sigil.v1.GenerationIngestService</code> gRPC protocol — it’s an OTel collector, not a Sigil receiver. The fix was to use the HTTP exporter directly:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">sigil_sdk.exporters.http</span> <span class="kn">import</span> <span class="n">HTTPGenerationExporter</span>

<span class="n">http_exporter</span> <span class="o">=</span> <span class="n">HTTPGenerationExporter</span><span class="p">(</span>
    <span class="n">endpoint</span><span class="o">=</span><span class="s">"https://sigil-prod-ca-east-0.grafana.net"</span><span class="p">,</span>
    <span class="n">headers</span><span class="o">=</span><span class="p">{</span><span class="s">"Authorization"</span><span class="p">:</span> <span class="sa">f</span><span class="s">"Basic </span><span class="si">{</span><span class="n">base64_creds</span><span class="si">}</span><span class="s">"</span><span class="p">},</span>
<span class="p">)</span>
<span class="n">config</span> <span class="o">=</span> <span class="n">ClientConfig</span><span class="p">(</span><span class="n">generation_exporter</span><span class="o">=</span><span class="n">http_exporter</span><span class="p">)</span>
</code></pre></div></div>

<p>This isn’t documented. I found it by reading the source code of the SDK package.</p>

<hr />

<h2 id="what-experienced-teams-get-vs-what-new-users-face">What Experienced Teams Get vs. What New Users Face</h2>

<p><strong>If your team already has Grafana Cloud</strong> with established Cloud Access Policies, Alloy collectors running, and a platform team who knows where the endpoint configuration lives: this takes 30 minutes. Install <code class="language-plaintext highlighter-rouge">sigil-sdk</code>, add the <code class="language-plaintext highlighter-rouge">start_generation</code> context manager to your LLM calls, point at your existing sigil endpoint, done.</p>

<p><strong>If you’re setting this up from scratch:</strong> budget 3-4 hours for the first run. The SDK is solid. The dashboard is excellent. The undocumented corners are real but navigable. The endpoint discovery and auth story need better documentation before this can be called “zero-config.”</p>

<p>The tagline on the landing page is “Actually useful AI O11y.” That’s accurate, once you’re past setup.</p>

<hr />

<h2 id="the-dashboard-experience-seamless-once-youre-in">The Dashboard Experience: Seamless Once You’re In</h2>

<p>Here’s the part that genuinely impressed me. Once the telemetry was flowing, the Grafana AI Observability UI is fast, well-designed, and immediately useful.</p>

<p><img src="/assets/images/sre-war-room/conversations-with-assistant.png" alt="Grafana Conversations view with AI Assistant panel showing analysis of 24 conversations" />
<em>The Grafana AI Assistant analysed the 24 conversations and flagged that token metrics showed 0 tokens recorded — a real instrumentation gap. It also recommended enabling feedback collection for quality assessment.</em></p>

<p>The AI Assistant panel on the right is a nice touch — it analyses your agent telemetry and surfaces actionable observations. It spotted that my token counts weren’t flowing through (a known gap with how the Sigil HTTP exporter handles token reporting in this early version) and suggested next steps. A Grafana dashboard that uses AI to help you observe your AI agents. We’ve reached full recursion.</p>

<p>The tabs — Analytics, Agents, Conversations, Tools, Evaluation — cover every dimension of LLM observability:</p>
<ul>
  <li><strong>Conversations</strong>: the thread view, for debugging individual incidents</li>
  <li><strong>Agents</strong>: the fleet view, for understanding workload distribution</li>
  <li><strong>Analytics</strong>: the metrics view, for SLO and cost tracking — sparse in this setup for reasons explained below</li>
  <li><strong>Evaluation</strong>: the quality view, for LLM-as-judge scoring (Phase 4 for this project)</li>
</ul>

<blockquote>
  <p><strong>Why the Analytics tab is sparse in this setup</strong></p>

  <p>If you open Analytics and see mostly empty panels — that’s expected here, and worth explaining. The Analytics tab is powered by Prometheus-compatible metrics. This project instruments exclusively via the Sigil SDK’s HTTP exporter, which ships conversation telemetry directly to Grafana’s Sigil ingestion endpoint. There is no Prometheus scrape pipeline in play — we didn’t use Prometheus at all. The instrumentation path is: agent code → Sigil SDK → HTTP exporter → <code class="language-plaintext highlighter-rouge">sigil-prod-ca-east-0.grafana.net</code>. That path doesn’t feed the Prometheus data model that Analytics queries against.</p>

  <p>What this means practically: token usage aggregates, latency histograms, and cost-over-time charts won’t populate from this setup. The <strong>Conversations tab carries everything meaningful</strong> — per-agent timing, call counts, model attribution, and the full prompt/response content. For the goal of this experiment (debugging agent behaviour across incident pipelines), Conversations is the right surface anyway.</p>

  <p>Wiring Sigil telemetry into a Prometheus-compatible sink to fully populate Analytics is a Phase 4 item, alongside LLM-as-judge evaluation. It would require either a recording rule layer or a custom exporter that bridges Sigil’s generation data into the Prometheus data model — doable, but out of scope for a four-day experiment on a brand-new SDK.</p>
</blockquote>

<hr />

<h2 id="the-numbers">The Numbers</h2>

<p>After two runs of 10 incidents each:</p>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Total conversations in Grafana</td>
      <td>24</td>
    </tr>
    <tr>
      <td>Average calls per conversation</td>
      <td>3.88</td>
    </tr>
    <tr>
      <td>Total agents registered</td>
      <td>5</td>
    </tr>
    <tr>
      <td>Average pipeline time</td>
      <td>~37 seconds</td>
    </tr>
    <tr>
      <td>Incidents resolved</td>
      <td>11/20</td>
    </tr>
    <tr>
      <td>Incidents escalated</td>
      <td>3/20</td>
    </tr>
    <tr>
      <td>Incidents partial</td>
      <td>5/20</td>
    </tr>
    <tr>
      <td>Errors</td>
      <td>1 (malformed JSON, handled gracefully)</td>
    </tr>
    <tr>
      <td>Estimated API cost for all runs</td>
      <td>~$1.50</td>
    </tr>
  </tbody>
</table>

<p>The 11/20 resolved rate is the most interesting number here, and it deserves more than a footnote.</p>

<p>The 3 escalations were all high-ambiguity P1 scenarios — JWT key rotation failure across multiple services, etcd fsync degradation affecting the entire control plane, a Prometheus TSDB corruption that took out the monitoring stack itself. In each case, the runbook-agent returned a valid plan, but the executor-agent hit simulated steps that either failed (exit code 1) or produced ambiguous output. The postmortem-agent then faithfully documented an unresolved incident. The pipeline completed correctly; the incident just wasn’t resolved. That’s the right behaviour.</p>

<p>The 5 partials are more interesting. In several cases, the executor completed all 8 steps and declared <code class="language-plaintext highlighter-rouge">resolution_status: "partial"</code> — meaning it judged that the simulated outcomes weren’t conclusive enough to call resolved. This reflects a real gap: the executor agent has no feedback loop. It can’t verify whether the simulated <code class="language-plaintext highlighter-rouge">kubectl rollout status</code> actually showed healthy pods. It’s reasoning about resolution based on output strings alone.</p>

<p>The 1 error was a truncated JSON response from Claude on a CDN DDoS + multi-region blast radius scenario — a complex incident with a long triage output that pushed against the executor’s context window. The <code class="language-plaintext highlighter-rouge">strip_fences()</code> fix handles markdown wrapping; I need a similar safety net for truncated JSON. It’s on the backlog.</p>

<hr />

<h2 id="whats-next">What’s Next</h2>

<h3 id="phase-4-llm-as-judge-evaluation">Phase 4: LLM-as-Judge Evaluation</h3>

<p>The most compelling remaining capability is automated quality evaluation. The architecture is ready:</p>

<ol>
  <li>Configure a Grafana evaluator targeting <code class="language-plaintext highlighter-rouge">postmortem-agent</code> outputs</li>
  <li>Rubric: “Does this post-mortem contain a specific root cause hypothesis?”</li>
  <li>Alert: fire if quality score drops below 0.7</li>
  <li>Test: intentionally degrade the postmortem system prompt and watch the alert fire</li>
</ol>

<p>This closes the loop: instrument → observe → evaluate → alert. Agent quality becomes a production SLO. That’s the end state.</p>

<h3 id="extending-to-real-projects">Extending to Real Projects</h3>

<p>The patterns from this experiment map directly to production agent systems:</p>
<ul>
  <li><strong>Any LangGraph pipeline</strong>: add <code class="language-plaintext highlighter-rouge">start_generation</code> context managers, pass <code class="language-plaintext highlighter-rouge">conversation_id</code> through state</li>
  <li><strong>Existing Grafana Cloud setups</strong>: five minutes to wire up once you have the endpoint</li>
  <li><strong>Cost tracking</strong>: the cost-cop pattern works for any multi-agent system</li>
</ul>

<hr />

<h2 id="summary">Summary</h2>

<p>Five agents processed 20 incident types without crashing. 11 resolved, 5 partial, 3 escalated, 1 error. Total pipeline time averaged 37 seconds. Total cost: under $2 in Anthropic API credits. Grafana tracked every conversation thread and the cost-cop identified real model swap opportunities. The endpoint setup required navigating undocumented configuration on a 4-day-old SDK, which took longer than it should.</p>

<p>That’s what was built and what it did.</p>

<hr />

<h2 id="conclusion">Conclusion</h2>

<p>The system did not consistently resolve incidents. That’s not a failure of the observability layer — it’s an accurate picture of what current LLM agents can and can’t do with incident data. The observability layer is doing its job: making that gap visible, measurable, and improvable.</p>

<p><strong>Treating LLM agent conversations as first-class telemetry — alongside traces, metrics, and logs — is the right architecture for the agentic era.</strong> The patterns here — conversation threading, per-agent cost tracking, quality evaluation as an SLO — will matter at every company running AI agents in production.</p>

<p>But here is where it breaks specifically.</p>

<p><strong>At 1000 agents, the conversation model gets expensive.</strong> Every generation is a round-trip to the Sigil endpoint. At 1000 agents × 4 calls × 1 incident/minute, that’s 4000 HTTP calls per minute before you’ve made a single LLM call. The batching and queue mechanics of the SDK need stress-testing at that volume.</p>

<p><strong>Cross-conversation dependencies are invisible.</strong> Sigil tracks individual conversations. It doesn’t model the relationship between a JWT rotation conversation at 11:06pm and the cascading auth failures that appear in a different conversation five minutes later. What would “distributed tracing for agent behaviour” require? The primitive isn’t a trace ID — it’s a causal link between conversations. Normal distributed tracing models a single request flowing through services. Agent behaviour tracing would need to model a multi-hop causal chain across separate incidents, separate conversations, and potentially separate agent pipelines — none of which share a request context. The closest existing hook is <code class="language-plaintext highlighter-rouge">parent_generation_id</code> on <code class="language-plaintext highlighter-rouge">GenerationStart</code>, but nothing in the current tooling connects those links across conversation boundaries.</p>

<p><strong>Evaluation is the hardest part, and I skipped it.</strong> I listed LLM-as-judge evaluation as Phase 4 because it requires defining what a good triage or good post-mortem actually looks like — a rubric problem that’s harder than the instrumentation problem. The dashboard has an Evaluation tab. It’s empty. That’s not Grafana’s failure. It’s mine.</p>

<p>As an SRE building toward LLM infrastructure roles, this experiment confirms the intersection I care about: SRE rigour applied to LLM systems. The tooling is here. The mental models transfer. The failure modes are real.</p>

<p>But here’s the shift in framing that matters most:</p>

<p><strong>We don’t have an observability problem for agents anymore. We have a correctness problem — and we finally have the tools to see it.</strong></p>

<p>The next question isn’t “can we observe what our agents are doing?” It’s “now that we can see it clearly, what do we do about it?” That’s a harder problem. It’s also a more honest one.</p>

<p>That’s the next post.</p>

<hr />

<h2 id="references">References</h2>

<ul>
  <li><a href="https://grafana.com/blog/ai-observability-for-agents-in-grafana-cloud/">Grafana AI Observability Blog Post</a></li>
  <li><a href="https://grafana.com/docs/grafana-cloud/machine-learning/ai-observability/">Grafana AI Observability Docs</a></li>
  <li><a href="https://github.com/grafana/sigil-sdk">Grafana Sigil SDK (GitHub)</a></li>
  <li><a href="https://langchain-ai.github.io/langgraph/">LangGraph Docs</a></li>
  <li><a href="https://docs.anthropic.com">Anthropic Claude API</a></li>
</ul>

<hr />

<p><em>This post is part of my ongoing series on LLM inference infrastructure. Previous posts: <a href="/llm-inference-deep-dive">What Is LLM Inference, Really?</a> and <a href="/apple-silicon-llm-inference">Running LLM Inference on Apple Silicon</a>.</em></p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm-infrastructure" /><category term="observability" /><category term="grafana" /><category term="grafana" /><category term="sigil-sdk" /><category term="langgraph" /><category term="anthropic" /><category term="claude" /><category term="multi-agent" /><category term="sre" /><category term="llm-ops" /><summary type="html"><![CDATA[Grafana AI Observability launched on April 21. I spent a few days building a five-agent incident response system to put it through its paces. Here's what actually happened.]]></summary></entry><entry><title type="html">P/D Disaggregation on a Single GPU — What the Architecture Actually Requires</title><link href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/21/llm-d-pd-disaggregation.html" rel="alternate" type="text/html" title="P/D Disaggregation on a Single GPU — What the Architecture Actually Requires" /><published>2026-04-21T00:00:00+00:00</published><updated>2026-04-21T00:00:00+00:00</updated><id>https://kraghavan.ca/llm-infrastructure/inference/2026/04/21/llm-d-pd-disaggregation</id><content type="html" xml:base="https://kraghavan.ca/llm-infrastructure/inference/2026/04/21/llm-d-pd-disaggregation.html"><![CDATA[<p>This post is the honest account of what happened when I ran experiments 5 and 6 — the <a href="https://github.com/llm-d/llm-d/tree/main/guides/pd-disaggregation">P/D disaggregation guide</a> from the llm-d repo — on a second Lambda Labs GH200 instance.</p>

<p>The short version: the pods ran, the stack was healthy, and the NIXL KV cache transfer dashboard showed “No Data” for every single metric. Performance was worse than the aggregated setup from the <a href="/llm-infrastructure/inference/2026/04/19/llm-d-epp-prefix-cache-results.html">previous post</a> on every dimension — E2E latency 6.5× higher, TTFT 3.7× higher, ITL 3.5× higher.</p>

<p>On a single GPU, P/D disaggregation doesn’t degrade — it collapses back into aggregated serving with worse performance. That’s the thesis of this post, and the Grafana dashboards prove it.</p>

<p>This is not a failure of the implementation. It’s the expected outcome when the hardware preconditions for NIXL are not met. This post maps that failure mode precisely — what the architecture requires, what actually ran, and how to tell the difference from the dashboards.</p>

<p><strong>Hardware:</strong> Lambda Labs GH200 480GB, instance <code class="language-plaintext highlighter-rouge">xxx.xxx.xx.186</code><br />
<strong>Model:</strong> Qwen/Qwen3-0.6B<br />
<strong>Stack:</strong> llm-d v0.4.0, pd-disaggregation guide, NIXL sidecar v0.7.1<br />
<strong>Load testing:</strong> Locust with tenant simulation (~50,000 requests)</p>

<hr />

<h2 id="what-pd-disaggregation-is-supposed-to-do">What P/D Disaggregation Is Supposed to Do</h2>

<p>In <a href="/llm-infrastructure/inference/2026/04/19/llm-d-epp-prefix-cache-results.html">aggregated serving</a> — what experiments 1–4 tested — a single pod handles both prefill and decode for every request. Prefill spikes for long prompts steal GPU time from ongoing decode sequences. The two phases compete for the same resources.</p>

<p>P/D disaggregation separates them. Dedicated prefill pods handle the compute-intensive, bursty work of processing input tokens. Dedicated decode pods handle the memory-bandwidth-intensive, steady work of generating output tokens. Each pool scales independently. Prefill spikes never interrupt decode.</p>

<p>The mechanism that makes this work is <strong>KV cache transfer</strong>. When a prefill pod finishes processing a request’s input tokens, it has a set of KV cache blocks — the computed key-value tensors for every input token. Those blocks need to move to the decode pod before decode can begin. The decode pod cannot start generating without them.</p>

<p>llm-d uses <strong>NIXL</strong> (<a href="https://github.com/ai-dynamo/nixl">NVIDIA Inference Xfer Library</a>) for this transfer. NIXL is designed to move KV cache blocks between pods over high-bandwidth interconnects — specifically InfiniBand or RoCE RDMA (<a href="https://github.com/ai-dynamo/nixl#supported-backends">NIXL transport backends</a>). The transfer happens over port 5600 via a <a href="https://github.com/llm-d/llm-d-routing-sidecar">routing sidecar</a> injected into each pod.</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/p-d-disaggregation-architecture-diagram.png" alt="Grafana Overview — 0 alerts, 32 dashboards, API server healthy on instance xxx.xxx.xx.186" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    A detailed breakdown of the disaggregated inference request flow. The Endpoint Picker (EPP) intelligently routes new requests to compute-bound Prefill Pods, which generate the initial KV Cache. This cache is then transferred via NIXL (over RDMA/NVLink on port 5600) to memory-bandwidth-bound Decode Pods for steady-state token generation. This separation eliminates inter-phase contention and allows for independent scaling of physical GPU resources tailored to the specific workload type.
  </figcaption>
</figure>

<p>The values.yaml for this guide makes the architecture explicit:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">routing</span><span class="pi">:</span>
  <span class="na">proxy</span><span class="pi">:</span>
    <span class="na">image</span><span class="pi">:</span> <span class="s">ghcr.io/llm-d/llm-d-routing-sidecar:v0.7.1</span>
    <span class="na">connector</span><span class="pi">:</span> <span class="s">nixlv2</span>        <span class="c1"># ← NIXL for KV transfer</span>
    <span class="na">secure</span><span class="pi">:</span> <span class="no">false</span>

<span class="na">decode</span><span class="pi">:</span>
  <span class="na">containers</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s2">"</span><span class="s">vllm"</span>
      <span class="na">args</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">--kv-transfer-config"</span>
        <span class="pi">-</span> <span class="s1">'</span><span class="s">{"kv_connector":"NixlConnector",</span><span class="nv"> </span><span class="s">"kv_role":"kv_both"}'</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">--gpu-memory-utilization"</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">0.45"</span>             <span class="c1"># ← halved to leave room for both pods</span>
      <span class="na">ports</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">containerPort</span><span class="pi">:</span> <span class="m">8200</span>  <span class="c1"># vllm</span>
        <span class="pi">-</span> <span class="na">containerPort</span><span class="pi">:</span> <span class="m">5600</span>  <span class="c1"># nixl transfer</span>

<span class="na">prefill</span><span class="pi">:</span>
  <span class="na">create</span><span class="pi">:</span> <span class="no">true</span>              <span class="c1"># ← this is the key difference from exp 1-4</span>
  <span class="na">containers</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s2">"</span><span class="s">vllm"</span>
      <span class="na">args</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">--kv-transfer-config"</span>
        <span class="pi">-</span> <span class="s1">'</span><span class="s">{"kv_connector":"NixlConnector",</span><span class="nv"> </span><span class="s">"kv_role":"kv_both"}'</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">--gpu-memory-utilization"</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">0.45"</span>
      <span class="na">ports</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">containerPort</span><span class="pi">:</span> <span class="m">8000</span>  <span class="c1"># vllm</span>
        <span class="pi">-</span> <span class="na">containerPort</span><span class="pi">:</span> <span class="m">5600</span>  <span class="c1"># nixl transfer</span>
</code></pre></div></div>

<p>Two notable changes from the inference-scheduling config: <code class="language-plaintext highlighter-rouge">prefill: create: true</code> (we now have a dedicated prefill pod), and <code class="language-plaintext highlighter-rouge">gpu-memory-utilization: 0.45</code> per pod instead of 0.90. Each pod gets 45% of GPU memory — the assumption being that each runs on a dedicated GPU.</p>

<hr />

<h2 id="the-setup">The Setup</h2>

<p>Day 2 was faster. The gotchas from Post 3 were already solved — real Helm binary, kubeconfig chown’d, environment variables in <code class="language-plaintext highlighter-rouge">.bashrc</code>, Gateway API CRDs pre-installed. The stack came up in under an hour.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get pods <span class="nt">-n</span> llm-d

NAME                                                READY   STATUS    RESTARTS      AGE
gaie-pd-epp-6bd657c9f4-q882g                        1/1     Running   0             45m
infra-pd-inference-gateway-istio-666c6955bd-g2wnl   1/1     Running   0             45m
ms-pd-llm-d-modelservice-decode-696d86b5c5-tk8d9    1/1     Running   1 <span class="o">(</span>25m ago<span class="o">)</span>   26m
ms-pd-llm-d-modelservice-prefill-64d5f7bb7f-rxvwb   1/1     Running   0             26m
</code></pre></div></div>

<p>Four pods. EPP running, gateway running, <strong>both prefill and decode pods running at 1/1</strong>. The decode pod had one restart — normal during model download. HTTPRoute confirmed valid, gateway responding, model serving requests.</p>

<p>The system looked healthy at every layer except the one that actually mattered.</p>

<p>The observability stack confirmed the same:</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/pd-grafana-overview.png" alt="Grafana Overview — 0 alerts, 32 dashboards, API server healthy on instance xxx.xxx.xx.186" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Grafana Overview on instance xxx.xxx.xx.186: 0 alerts, 32 dashboards loaded, observability stack healthy.
    The P/D Coordinator Metrics dashboard — a new addition specific to this guide — is visible in the tab bar.
  </figcaption>
</figure>

<p>Then the Locust test ran. And the numbers came back wrong.</p>

<hr />

<h2 id="the-locust-results">The Locust Results</h2>

<p>Same script as experiments 1–4. Same traffic shape: 4:1 tenant session to cold request ratio, same three tenant profiles with long system prompts.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Hardware:  GH200 480GB (prefill pod + decode pod, P/D disaggregation guide)
Model:     Qwen/Qwen3-0.6B
Duration:  sustained run, ~26 req/s

Task              Requests    Failures   avg      min      max
──────────────────────────────────────────────────────────────
cold_request      ~10,020     0 (0%)     1,047ms  969ms    1,094ms
tenant_session    ~39,976     0 (0%)     1,654ms  1,521ms  1,721ms
──────────────────────────────────────────────────────────────
Aggregated        ~49,996     0 (0%)     1,532ms  969ms    1,721ms
</code></pre></div></div>

<p><em>Note: terminal output only — no CSV saved for this run. Avg, min, max reported; p95/p99 not available.</em></p>

<p>Zero failures — the system was stable. But the latency numbers were dramatically worse than experiments 1–4:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Metric           Exp 1-4 (aggregated)   Exp 5-6 (P/D)      Change
────────────────────────────────────────────────────────────────────
cold_request avg   207ms                 1,047ms            5.1× worse
tenant_session avg 273ms                 1,654ms            6.1× worse
</code></pre></div></div>

<p>This was not what P/D disaggregation is supposed to deliver. The next step was Grafana.</p>

<hr />

<h2 id="what-grafana-showed">What Grafana Showed</h2>

<h3 id="the-performance-dashboard">The Performance Dashboard</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/pd-performance-dashboard.png" alt="llm-d Performance Dashboard — TTFT p50 53.3ms, ITL p50 17.5ms, KV Cache Hit Rate 81.3%, Throughput peaked then dropped" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    llm-d Performance Dashboard during the Locust run.
    Top-left: TTFT p50 at 53.3ms — two lines visible, one per pod.
    Top-right: ITL p50 at 17.5ms, p95 at 24.3ms.
    Middle: KV Cache Hit Rate at <strong>81.3%</strong> — EPP routing still working.
    Bottom: Request Throughput shows the Locust run peak then trailing off.
    Request Queue Status shows Requests Running=39 during the peak.
  </figcaption>
</figure>

<p>Three things immediately stand out comparing this to the experiments 1–4 dashboard:</p>

<p><strong>TTFT went from 15ms to 53ms.</strong> More than 3× worse. In a properly functioning P/D disaggregated system, TTFT should improve because the decode pod never waits for prefill — prefill happens on a dedicated pod. Here it got worse.</p>

<p><strong>ITL went from 5ms to 17.5ms.</strong> Inter-Token Latency — the gap between consecutive generated tokens during decode — is 3.5× higher. This is the clearest signal of a problem. ITL is purely a function of decode throughput. It shouldn’t change between setups unless the decode pod’s resources are constrained.</p>

<p><strong>KV Cache Hit Rate is still 81.3%.</strong> The EPP routing is still working correctly. Tenant sessions are being routed to the pod holding their cached KV blocks. The routing layer is fine.</p>

<h3 id="the-pd-coordinator-dashboard--the-smoking-gun">The P/D Coordinator Dashboard — The Smoking Gun</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/pd-coordinator-metrics.png" alt="P/D Coordinator Metrics — Avg TTFT (Prefill): 54.9ms, Avg True TTFT (Prefill + Decode): 54.9ms, Avg TTFT (Decode): 54.9ms, E2E Latency p50=1.69s, Prefill Duration p50=150ms, Decode Duration p50=1.67s" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    P/D Coordinator Metrics dashboard.
    Top row: Avg vLLM TTFT (Prefill) = 54.9ms, Avg True TTFT (Prefill + Decode) = 54.9ms, Avg vLLM TTFT (Decode) = 54.9ms.
    All three TTFT metrics showing the same value means NIXL KV transfer adds no observable latency — because it is not happening.
    Middle: P/D E2E Latency p50=1.69s, p95=1.97s, p99=1.99s.
    Bottom: vLLM Prefill Duration p50=150ms, vLLM Decode Duration p50=1.67s.
  </figcaption>
</figure>

<p><strong>Diagnostic checklist: is your P/D setup actually disaggregated?</strong></p>

<p>If your deployment shows all of the following, it is not disaggregated — it is aggregated serving with extra overhead:</p>

<table>
  <thead>
    <tr>
      <th>Signal</th>
      <th>Value in a broken setup</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>KV Transfer Metrics (NIXL)</td>
      <td>No Data</td>
    </tr>
    <tr>
      <td>Prefill Worker Utilization</td>
      <td>~0%</td>
    </tr>
    <tr>
      <td>Decode pod handles all throughput</td>
      <td>Yes</td>
    </tr>
    <tr>
      <td>TTFT (Prefill) = TTFT (Decode)</td>
      <td>Same value</td>
    </tr>
    <tr>
      <td>EPP Ready Pods</td>
      <td>Less than total running pods</td>
    </tr>
  </tbody>
</table>

<p>All five conditions were present in these experiments. Check this dashboard before assuming P/D disaggregation is functioning.</p>

<p>The top row of the P/D Coordinator dashboard is designed to show the latency breakdown between prefill and decode. Three separate metrics: <code class="language-plaintext highlighter-rouge">Avg vLLM TTFT (Prefill)</code>, <code class="language-plaintext highlighter-rouge">Avg True TTFT (Prefill + Decode)</code>, and <code class="language-plaintext highlighter-rouge">Avg vLLM TTFT (Decode)</code>.</p>

<p>All three show <strong>54.9ms</strong>. Identical.</p>

<p>In a working P/D disaggregation system, these would differ. The True TTFT would be higher than either individual component because it includes the NIXL KV transfer time between pods. If all three are identical, the KV transfer is contributing zero measurable time — which means the transfer is not happening.</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/pd-coordinator-nixl-no-data.png" alt="P/D Coordinator Metrics — KV Cache Transfer Metrics (NIXL Connector) section: Avg KV Transfer Time = No Data, Avg MB per Transfer = No Data, Total KV Transfers = No Data, Failed KV Transfers = 0" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    KV Cache Transfer Metrics (NIXL Connector) section of the P/D Coordinator dashboard.
    <strong>Avg KV Transfer Time: No Data. Avg MB per Transfer: No Data. Total KV Transfers: No Data.</strong>
    Failed KV Transfers: 0 — not because transfers succeeded, but because no transfers were attempted.
    KV Transfer Time Percentiles: No data. KV Transfer Post Time Percentiles: No data.
    This is the definitive confirmation that NIXL is not transferring KV cache blocks between pods.
  </figcaption>
</figure>

<p>In this system, “No Data” is not a monitoring gap — it is the primary signal that KV transfer is not happening. Most engineers look past empty dashboard panels. Here, the empty panels are the answer.</p>

<p><strong>No KV transfers happened.</strong> Zero. Not failed — just absent. NIXL didn’t move any data between the prefill and decode pods during the entire Locust run.</p>

<h3 id="the-epp-pool--only-one-ready-pod">The EPP Pool — Only One Ready Pod</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/pd-epp-pool-health.png" alt="llm-d Performance Dashboard scrolled — EPP Pool Health &amp; Load: Ready Pods = 1, EPP KV Cache Pool Utilization: 0% and 0.727%" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    llm-d Performance Dashboard lower panels.
    EPP Pool Health &amp; Load: <strong>Ready Pods = 1</strong> — despite two pods running (prefill + decode),
    the EPP is only routing to one. EPP KV Cache Pool Utilization: 0% (prefill pod) and 0.727% (decode pod).
    The decode pod is doing all the work. The prefill pod is not receiving routed traffic.
  </figcaption>
</figure>

<p>EPP Pool Health shows Ready Pods = 1. Despite two pods running and both showing 1/1 in <code class="language-plaintext highlighter-rouge">kubectl get pods</code>, the EPP only recognises one pod as ready for traffic. The prefill pod — despite being healthy — is not in the EPP’s routing pool.</p>

<h3 id="the-diagnostic-drill-down--both-pods-present-but-unequal">The Diagnostic Drill-Down — Both Pods Present But Unequal</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/pd-diagnostic-drilldown.png" alt="llm-d Diagnostic Drill-Down — KV Cache Utilization showing decode pod at 0.698% peak and prefill pod at 0%, Model Throughput decode pod climbing to 2500tps while prefill near 0, Queue Utilization decode pod active" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Diagnostic Drill-Down model serving panels. Both pods appear in the legend.
    KV Cache Utilization: decode pod reaching 0.698% peak, prefill pod at 0%.
    Model Throughput: decode pod climbing to 2,500 tps, prefill pod near zero.
    Queue Utilization: decode pod showing activity, prefill pod flat.
    The decode pod is handling all traffic. The prefill pod is running but idle.
  </figcaption>
</figure>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/pd-diagnostic-pd-section.png" alt="llm-d Diagnostic Drill-Down P/D section — Prefill Cache Hit Rate 81.2%, Per-Instance showing two pod lines, Prefill Worker Utilization near 0, Decode Worker Utilization 0.2-0.6% spikes, Prefill Queue Length flat" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Diagnostic Drill-Down P/D Disaggregation section.
    Prefix Cache Hit Rate: <strong>81.2%</strong> — EPP routing still achieving high cache hit rate.
    Prefill Worker Utilization: flat near 0% — the prefill pod is not processing requests.
    Decode Worker Utilization: 0.2–0.6% spikes — the decode pod is doing everything.
    Prefill Queue Length: flat — no requests queued for prefill.
  </figcaption>
</figure>

<p>The P/D disaggregation section of the Diagnostic Drill-Down makes the situation clear. Prefill Worker Utilization is near zero throughout the test. The prefill pod is running, consuming memory, and doing nothing. The decode pod is handling all prefill and decode — effectively running as an aggregated server with 45% GPU memory instead of 90%.</p>

<hr />

<h2 id="why-nixl-didnt-work--the-hardware-constraint">Why NIXL Didn’t Work — The Hardware Constraint</h2>

<p>NIXL is designed for KV cache transfer between pods running on <strong>separate physical GPUs</strong> connected by <strong>RDMA</strong> — InfiniBand or RoCE. This is not a configuration choice. It’s a transport layer requirement. NIXL uses <code class="language-plaintext highlighter-rouge">ibv_reg_mr</code> (<a href="https://www.rdmamojo.com/2012/09/07/ibv_reg_mr/">InfiniBand verbs memory registration</a>) to pin GPU memory for zero-copy transfer. Without an RDMA-capable network between the pods, the transport layer cannot initialise.</p>

<p>On a single GH200 with time-sliced GPU allocation:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>What the architecture expects:
  Prefill Pod → [GPU 0] → RDMA/NVLink → [GPU 1] ← Decode Pod

What actually ran:
  Prefill Pod ↘                    ↗ Decode Pod
               [Single GH200 GPU]
               (time-sliced, shared)
</code></pre></div></div>

<p>Both pods share the same physical GPU. There is no RDMA path between them — they’re in the same physical memory space. NIXL cannot establish its transport. The sidecar starts, port 5600 opens, and then nothing moves.</p>

<p>This requirement is easy to overlook because the system still appears healthy at the pod and routing layers. Pods are Running. HTTPRoute is valid. The EPP is routing. Prometheus is scraping metrics. Everything except the KV transfer layer looks operational — and the KV transfer layer shows no errors, just silence.</p>

<p>This isn’t a bug. It’s the architecture working as documented. The <a href="https://github.com/llm-d/llm-d/tree/main/guides/pd-disaggregation">llm-d pd-disaggregation guide</a> states it requires multiple GPUs — the <a href="https://github.com/llm-d/llm-d/tree/main/guides/inference-scheduling#benchmarking-report">inference-scheduling guide’s README</a> explicitly notes its default benchmark configuration targets 16 GPUs across 8 model servers. The GH200’s NVLink-C2C is designed for CPU-GPU communication within the package, not for inter-pod RDMA at the scale NIXL needs.</p>

<p>What NIXL actually needs is one of:</p>
<ul>
  <li>Multiple physical GPUs on the same node connected by NVLink (<a href="https://www.nvidia.com/en-us/data-center/nvlink/">H100 SXM with NVSwitch</a>)</li>
  <li>Multiple nodes connected by InfiniBand or RoCE</li>
</ul>

<p>A single GH200 satisfies neither condition.</p>

<hr />

<h2 id="what-the-numbers-actually-mean">What the Numbers Actually Mean</h2>

<p>The performance degradation in experiments 5–6 has three causes:</p>

<p><strong>1. Halved GPU memory per pod.</strong> <code class="language-plaintext highlighter-rouge">gpu-memory-utilization: 0.45</code> instead of 0.90 means each pod gets roughly half the KV cache budget. The decode pod — which is doing all the work — has only 45% of GPU memory available for the KV cache. This directly limits batch size and increases the probability of KV evictions, which degrades both throughput and ITL.</p>

<p><strong>2. GPU time-slicing competition.</strong> Both pods share one physical GPU. Every GPU operation from the prefill pod steals cycles from the decode pod and vice versa. Even though the prefill pod is idle, it’s not truly idle — it’s holding GPU memory allocations and context. This is why ITL went from 5ms to 17.5ms: the decode pod gets less consistent GPU access.</p>

<p><strong>3. NIXL coordination overhead.</strong> The routing sidecar still runs, still listens on port 5600, still attempts to coordinate transfers. Even with no transfers completing, the coordination layer adds processing overhead per request.</p>

<p>The result is a system that has the complexity cost of disaggregation with none of its benefits.</p>

<hr />

<h2 id="the-complete-comparison">The Complete Comparison</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Setup         Exp 1-4 (aggregated)   Exp 5-6 (P/D attempted)   Notes
──────────────────────────────────────────────────────────────────────────────
Pods          1 decode               1 prefill + 1 decode       Both pods 1/1 Running
GPU mem/pod   90%                    45%                        Halved for time-slicing
NIXL active   N/A                    No (RDMA not available)    No data in dashboard
KV Hit Rate   80.6%                  81.3%                      EPP routing: unchanged
TTFT avg      15ms                   54.9ms                     3.7× worse
ITL p50       5ms                    17.5ms                     3.5× worse
E2E p50       260ms                  1,690ms                    6.5× worse
Failures      0                      0                          Both stable
Total reqs    26,826                 ~49,996                    More requests, longer run
</code></pre></div></div>

<hr />

<h2 id="what-pd-disaggregation-actually-needs">What P/D Disaggregation Actually Needs</h2>

<p>P/D disaggregation is architecturally sound and measurably beneficial — when run on appropriate hardware. The llm-d team’s <a href="https://llm-d.ai/blog/llm-d-v0.5-sustaining-performance-at-scale">published benchmark results</a> on 16 H100 GPUs (8 vLLM pods, TP=2) show up to 99% lower TTFT and 109% higher throughput compared to a baseline Kubernetes service under shared-prefix workloads. A more detailed breakdown of the v0.4 scheduler benchmark on the same topology is in the <a href="https://llm-d.ai/blog/llm-d-v0.4-achieve-sota-inference-across-accelerators">v0.4 release post</a>. Neither is something I measured — these are llm-d’s own published numbers on appropriate hardware.</p>

<p>But “appropriate hardware” is not optional. It means:</p>

<p><strong>Minimum viable configuration:</strong></p>
<ul>
  <li>Two physical GPUs — one dedicated to prefill, one to decode</li>
  <li>High-bandwidth interconnect between them (NVLink SXM, InfiniBand, RoCE)</li>
  <li>RDMA drivers available in the container runtime</li>
</ul>

<p><strong>Production configuration:</strong></p>
<ul>
  <li>Dedicated prefill pod pool (multiple GPUs, auto-scaled to compute demand)</li>
  <li>Dedicated decode pool (multiple GPUs, auto-scaled to memory-bandwidth demand)</li>
  <li>RDMA fabric between pools</li>
  <li>The GH200’s NVLink-C2C is excellent for CPU-GPU communication but not for inter-node RDMA</li>
</ul>

<p>The fundamental insight from these experiments: <strong>P/D disaggregation is a distributed systems problem, not a Kubernetes scheduling problem.</strong> You can schedule the pods correctly, set up the EPP, configure NIXL, and deploy the routing sidecar — and still have an aggregated server if the hardware doesn’t support RDMA-based KV transfer. The architecture is only as good as the interconnect it runs on.</p>

<hr />

<h2 id="what-this-means-for-the-series">What This Means for the Series</h2>

<p>This series started with a theory: prefill and decode compete for the same resources in aggregated serving. Post 2 measured the consequences on an M4 Mac Mini. Post 3 deployed the infrastructure on a GH200. Post 4 showed EPP prefix cache routing working correctly on a single aggregated pod.</p>

<p>This post was supposed to show the next step — split prefill and decode, measure the improvement. Instead it showed why that split requires dedicated hardware.</p>

<p>This result is more actionable than a successful run would have been. Anyone planning to deploy P/D disaggregation needs to know:</p>

<ul>
  <li>Single-GPU time-slicing will not work — NIXL needs RDMA</li>
  <li>Halving GPU memory per pod on shared hardware degrades performance significantly</li>
  <li>The “2 pods running” state is not sufficient validation — check the P/D Coordinator dashboard for actual KV transfer metrics before declaring success</li>
  <li>The correct hardware starting point is at minimum 2 physical GPUs with NVLink or InfiniBand</li>
</ul>

<p>The next experiment worth running — when the GPU budget allows — is a 2-node setup with proper RDMA between prefill and decode pods. That’s what the architecture is designed for, and that’s where the TTFT numbers would actually improve rather than degrade.</p>

<hr />

<h2 id="what-the-epp-got-right">What the EPP Got Right</h2>

<p>One thing worth noting: despite everything else going wrong, the EPP routing continued to achieve 81.2% prefix cache hit rate. The routing intelligence — directing tenant sessions to pods with warm KV cache — worked correctly regardless of whether NIXL was functioning.</p>

<p>This is the right separation of concerns. The EPP’s job is routing. NIXL’s job is KV transfer. They’re independent layers. When NIXL fails, routing doesn’t fail with it. The system degrades gracefully — you get worse performance, not a broken system.</p>

<p>That’s principled architecture. It’s also why the llm-d design is worth understanding even if you’re not deploying at the scale that justifies dedicated prefill and decode pools. The routing layer’s correctness is independent of the transfer layer’s availability.</p>

<hr />

<h2 id="the-most-valuable-thing-this-experiment-taught-me">The Most Valuable Thing This Experiment Taught Me</h2>

<p>I want to be direct about this, because it’s the kind of learning that only comes from actually running the thing rather than reading the architecture docs.</p>

<p>Before these experiments, I understood P/D disaggregation conceptually — prefill is compute-bound, decode is memory-bandwidth-bound, separate them onto dedicated hardware, scale independently. The theory was clear.</p>

<p>What I didn’t fully appreciate was how non-negotiable the hardware requirement is. It’s not a performance optimisation. It’s a correctness requirement. Without RDMA between pods, NIXL cannot transfer KV cache blocks. Without KV transfer, the decode pod cannot receive the prefill pod’s output. Without that handoff, you don’t have disaggregation — you have two pods running on a single shared GPU, each with half the memory budget, competing for the same compute cycles. Which is strictly worse than one pod using all of it.</p>

<p>The GH200 taught me this in a way that no benchmark paper could. I stood up the full architecture — correct values.yaml, correct pod configuration, correct NIXL sidecar, correct port mappings — and watched Grafana show “No Data” on every single KV transfer metric. The pods were healthy. The routing was working. The architecture was incomplete because the hardware was.</p>

<p><strong>The lesson:</strong> when an architecture requires RDMA, it’s not a performance optimisation — it’s a correctness condition. The system will appear to run without it. The metrics will tell you otherwise.</p>

<p>The next experiment is a minimal 2-GPU setup with:</p>

<ul>
  <li>Dedicated prefill and decode pods on separate physical GPUs</li>
  <li>NVLink or RDMA-backed interconnect between them</li>
  <li>Verified non-zero KV Transfer metrics in the P/D Coordinator dashboard</li>
  <li>Measurable separation between prefill TTFT and decode TTFT</li>
  <li>ITL improvement relative to the aggregated baseline from experiments 1–4</li>
</ul>

<p>Success is defined: KV transfers showing actual data, prefill worker utilization above 0%, and E2E latency that improves on the 260ms p50 from experiments 1–4 — not degrades from it.</p>

<p>That comparison — aggregated (260ms p50) → P/D wrong hardware (1,690ms p50) → P/D proper RDMA (?ms p50) — will be the complete picture of what disaggregation delivers and what it costs.</p>

<hr />

<p><em>Experiments run on Lambda Labs GH200 480GB, llm-d v0.4.0, pd-disaggregation guide, Qwen3-0.6B, NIXL v0.7.1. Platform engineer with 11+ years in distributed systems going deep on LLM serving infrastructure.</em></p>

<p><em><a href="https://github.com/kraghavan">GitHub</a> · <a href="https://linkedin.com/in/karthikaraghavan">LinkedIn</a></em></p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm-infrastructure" /><category term="inference" /><category term="llm-d" /><category term="pd-disaggregation" /><category term="nixl" /><category term="rdma" /><category term="kubernetes" /><category term="vllm" /><category term="gpu" /><category term="gh200" /><category term="prefill" /><category term="decode" /><category term="inference-architecture" /><summary type="html"><![CDATA[I deployed llm-d's P/D disaggregation guide — separate prefill and decode pods, NIXL sidecar, the full architecture. The pods ran. The NIXL KV transfers showed No Data. Here is what that tells you about what disaggregation actually requires.]]></summary></entry><entry><title type="html">llm-d in Action — EPP Prefix Cache Routing and What It Actually Means</title><link href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/19/llm-d-epp-prefix-cache-results.html" rel="alternate" type="text/html" title="llm-d in Action — EPP Prefix Cache Routing and What It Actually Means" /><published>2026-04-19T00:00:00+00:00</published><updated>2026-04-19T00:00:00+00:00</updated><id>https://kraghavan.ca/llm-infrastructure/inference/2026/04/19/llm-d-epp-prefix-cache-results</id><content type="html" xml:base="https://kraghavan.ca/llm-infrastructure/inference/2026/04/19/llm-d-epp-prefix-cache-results.html"><![CDATA[<p>In the <a href="/llm-infrastructure/inference/2026/04/17/vllm-llm-d-nvidia-gh200-experiment.html">previous post</a> I documented everything that broke during the llm-d deployment on a Lambda Labs GH200. Ten gotchas, two false starts, one ticking hourly bill.</p>

<p>This post is the payoff — and more than that, it’s an attempt to say something useful beyond “look at these numbers.” The numbers are good. But the more interesting question is what they reveal about inference architecture that applies regardless of which GPU you’re running on or which serving framework you’ve chosen.</p>

<p><strong>Hardware:</strong> Lambda Labs GH200 480GB, ARM64<br />
<strong>Model:</strong> Qwen/Qwen3-0.6B<br />
<strong>Stack:</strong> llm-d v0.4.0, vllm/vllm-openai:latest, Istio gateway, kube-prometheus-stack<br />
<strong>Load testing:</strong> Locust with tenant simulation<br />
<strong>Observability:</strong> Prometheus + Grafana (llm-d Performance Dashboard, llm-d vLLM Overview)</p>

<hr />

<h2 id="the-hardware-deserves-more-than-a-footnote">The Hardware Deserves More Than a Footnote</h2>

<p>Most inference benchmarks treat hardware as a footnote — “tested on an A100” — without explaining why the hardware choice matters architecturally. The GH200 is worth understanding properly because it represents a design direction that the industry is converging on, and it changes some assumptions about what’s possible in inference.</p>

<p>One quick note before the specs: the GH200 is technically a unified memory architecture — just like the M4 Mac Mini from the previous post. CPU and GPU share the same address space without copying data between them. The Mac Mini has 16GB at roughly 200 GB/s. The GH200 has 576GB at up to 4,000 GB/s.</p>

<p>The GH200 is technically unified memory — just like the M4 Mac Mini. One costs $799. The other costs $2.29 per hour and will make you feel considerably better about your Mac Mini purchase. Same architectural principle, considerably different ambitions — and as the numbers in this post will show, considerably different outcomes.</p>

<h3 id="grace-hopper--one-package-two-chips-one-memory-bus">Grace Hopper — One Package, Two Chips, One Memory Bus</h3>

<p>The GH200 is not a GPU. It’s a <strong>Grace Hopper Superchip</strong> — NVIDIA’s Grace CPU (72 ARM Neoverse V2 cores) and an H100 Hopper GPU die, connected on the same package via <strong>NVLink-C2C</strong> (chip-to-chip).</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/grace-hopper-chip-nvidia.png" alt="Architecture of the NVIDIA GH200 Grace Hopper Superchip showing Grace CPU and Hopper GPU connected via NVLink-C2C" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    NVIDIA GH200 Grace Hopper Superchip architecture. The Grace CPU (72 ARM Neoverse V2 cores, 480GB LPDDR5X)
    and Hopper GPU (H100, 96GB HBM3e) are connected on the same package via NVLink-C2C at 900 GB/s bidirectional —
    7× the bandwidth of PCIe Gen5. This chip-to-chip interconnect is what makes unified CPU+GPU memory a practical
    reality rather than a marketing claim.
    Source: <a href="https://www.nvidia.com/en-us/data-center/grace-hopper-superchip/">NVIDIA GH200 product page</a>.
  </figcaption>
</figure>

<p>The critical number is the <strong>NVLink-C2C bandwidth: 900 GB/s bidirectional</strong>. For context:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Interconnect              Bandwidth
──────────────────────────────────────────────
PCIe 5.0 x16 (discrete)   128 GB/s
NVLink-C2C (GH200)         900 GB/s    ← 7× faster than PCIe Gen5
HBM3e on-chip (GH200)    4,000 GB/s
LPDDR5X (Grace CPU)        512 GB/s
</code></pre></div></div>

<p><em>Source: <a href="https://www.nvidia.com/en-us/data-center/grace-hopper-superchip/">NVIDIA GH200 Grace Hopper Superchip product page</a> and <a href="https://www.amax.com/content/files/2023/12/NVIDIA_Grace_Hopper_Superchip_Architecture_Overview_Whitepaper.pdf">GH200 architecture whitepaper</a>. The 7× PCIe Gen5 figure is NVIDIA’s own stated specification — “NVLink-C2C delivers up to 900 GB/s total bandwidth. This is 7x higher bandwidth than x16 PCIe Gen5 lanes.”</em></p>

<p>On a conventional discrete GPU system — an A100 or H100 in a PCIe slot — the CPU and GPU have separate memory pools connected by a 128 GB/s bus. Moving data between them is expensive. The GPU can’t efficiently use CPU DRAM for KV cache overflow because the PCIe bandwidth is 31× slower than the GPU’s on-chip HBM bandwidth (4,000 ÷ 128 = 31.25×). Any spill to CPU memory becomes a bottleneck.</p>

<p>On the GH200, the Grace CPU’s 480GB of LPDDR5X memory is accessible to the Hopper GPU at 900 GB/s over NVLink-C2C. That’s not as fast as on-chip HBM3e, but it’s fast enough to be genuinely useful. The result is a unified addressable memory space — the GPU sees up to 576GB total (96GB HBM3e + 480GB LPDDR5X) — at bandwidths that make overflow to CPU DRAM a viable architectural choice rather than a last resort.</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/grace-hopper-chip-nvidia2.png" alt="Memory architecture comparison for LLM inference — discrete GPU PCIe vs GH200 NVLink-C2C" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Left: discrete GPU (A100/H100 PCIe) — CPU and GPU have separate memory pools connected by 128 GB/s PCIe Gen5.
    KV cache overflow to CPU DRAM is 31× slower than on-chip HBM, making it unusable in practice.
    Right: GH200 Grace Hopper — CPU and GPU share a unified 576GB address space (96GB HBM3e + 480GB LPDDR5X)
    connected at 900 GB/s via NVLink-C2C. KV cache tiering to CPU memory becomes a viable architectural option,
    not a last resort. This is why llm-d's tiered KV offloading feature maps directly onto GH200 hardware.
  </figcaption>
</figure>

<h3 id="why-this-matters-for-llm-inference">Why This Matters for LLM Inference</h3>

<p>At scale, inference systems are typically <strong>memory-bandwidth bound</strong>, not compute bound. This isn’t universal — small models at low concurrency can be compute-bound during prefill, and some workloads shift the bottleneck elsewhere. But for production multi-tenant serving, the binding constraint is almost always memory: how fast the hardware can load model weights and KV cache tensors for each forward pass. Every decode step reads the full KV cache. On a 7B model with a 4K context window and 32 concurrent requests, that’s dozens of gigabytes moving through the memory subsystem per second — and the rate of that movement, not the number of CUDA cores, determines your throughput ceiling.</p>

<p>The GH200’s NVLink-C2C doesn’t solve this — HBM3e is still the primary memory bandwidth for active inference. But it changes the economics of KV cache management. Tiered KV storage (hot blocks in HBM, warm blocks in LPDDR5X, cold blocks evicted to NVMe) becomes viable in a way it isn’t on PCIe-connected systems. llm-d’s architecture diagram from the previous post already shows tiered KV cache offloading as a first-class feature — the GH200 is the hardware that makes that design practical.</p>

<p>For these experiments, we didn’t exercise KV cache tiering. The model is small and the cache pressure is low. But the architecture is there, and it’s why the GH200 was the right choice for running the full llm-d stack rather than a conventional discrete GPU setup.</p>

<hr />

<h2 id="one-mental-model-before-the-numbers">One Mental Model Before the Numbers</h2>

<p>Before looking at a single metric, here is the frame I’d encourage you to carry into any inference system analysis:</p>

<p><strong>LLM inference is a memory scheduling problem that looks like a compute problem.</strong></p>

<p>Every team I’ve seen optimise inference focuses first on compute — GPU utilization, batch size, model quantization. These matter. But the real leverage is in memory: how much of the KV cache is warm, how often prefill recomputation is avoided, how well the scheduler keeps the right data in the right tier. The system that wins at scale is the system that does the least unnecessary work — and unnecessary prefill recomputation is the biggest source of waste in multi-tenant inference.</p>

<p>This is what EPP prefix cache routing is solving. Not “make the GPU faster.” Make the system do less work.</p>

<hr />

<h2 id="what-these-experiments-actually-test">What These Experiments Actually Test</h2>

<p>Experiments 1–4 use the <code class="language-plaintext highlighter-rouge">inference-scheduling</code> guide from the llm-d repo. This deploys <strong>a single decode pod that handles both prefill and decode</strong> — aggregated serving. The values.yaml is unambiguous:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">prefill</span><span class="pi">:</span>
  <span class="na">create</span><span class="pi">:</span> <span class="no">false</span>   <span class="c1"># one pod does everything</span>
</code></pre></div></div>

<p>The architecture is:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Every request →  Istio Gateway
                      │
                      ▼
                 EPP (Endpoint Picker Plugin)
                 ┌────────────────────────────────┐
                 │  prefix-cache-scorer           │
                 │  queue-depth-scorer            │
                 │  kv-utilization-scorer         │
                 └────────────────────────────────┘
                      │
                      ▼
               Single vLLM decode pod
               (prefill + decode, one process)
               KV cache lives here
</code></pre></div></div>

<p>With one pod, there is no cross-pod routing decision to make. The EPP’s job here is narrower: route requests with matching prefix hashes back to this pod consistently, so its KV cache stays warm. Round-robin with one pod is also consistent routing — but a naive load balancer doesn’t know about prefix hashes, so it can’t make cache-aware decisions when you add a second pod later.</p>

<p><strong>What this experiment answers:</strong> Does EPP prefix-cache-aware routing actually maintain high cache utilization under realistic multi-tenant load? Does the system hold TTFT stable as concurrency grows?</p>

<p><strong>What it doesn’t answer yet:</strong> What happens when you separate prefill and decode onto dedicated pods. That’s the next post.</p>

<p>This single-pod result is the baseline. Everything in the P/D disaggregation post gets measured against what we establish here.</p>

<hr />

<h2 id="the-load-test--simulating-multi-tenant-traffic">The Load Test — Simulating Multi-Tenant Traffic</h2>

<p>The Locust script simulates two traffic types in a 4:1 ratio:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># llmd-locust.py
</span><span class="n">MODEL</span> <span class="o">=</span> <span class="s">"Qwen/Qwen3-0.6B"</span>

<span class="c1"># Three tenant personas — each with a distinct long system prompt
</span><span class="n">TENANTS</span> <span class="o">=</span> <span class="p">[</span>
    <span class="s">"You are a financial analyst assistant specializing in market data. "</span> <span class="o">*</span> <span class="mi">5</span><span class="p">,</span>
    <span class="s">"You are a DevOps engineer assistant specializing in Kubernetes and CI/CD. "</span> <span class="o">*</span> <span class="mi">5</span><span class="p">,</span>
    <span class="s">"You are a data scientist assistant specializing in ML pipelines. "</span> <span class="o">*</span> <span class="mi">5</span><span class="p">,</span>
<span class="p">]</span>

<span class="k">class</span> <span class="nc">LLMDUser</span><span class="p">(</span><span class="n">HttpUser</span><span class="p">):</span>
    <span class="n">wait_time</span> <span class="o">=</span> <span class="n">between</span><span class="p">(</span><span class="mf">0.5</span><span class="p">,</span> <span class="mi">2</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">on_start</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">tenant_prompt</span> <span class="o">=</span> <span class="n">random</span><span class="p">.</span><span class="n">choice</span><span class="p">(</span><span class="n">TENANTS</span><span class="p">)</span>  <span class="c1"># sticky for session
</span>
    <span class="o">@</span><span class="n">task</span><span class="p">(</span><span class="mi">4</span><span class="p">)</span>
    <span class="k">def</span> <span class="nf">tenant_request</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="c1"># Repeat system prompt → cache hit opportunity
</span>        <span class="bp">self</span><span class="p">.</span><span class="n">client</span><span class="p">.</span><span class="n">post</span><span class="p">(</span><span class="s">"/v1/chat/completions"</span><span class="p">,</span> <span class="n">json</span><span class="o">=</span><span class="p">{</span>
            <span class="s">"model"</span><span class="p">:</span> <span class="n">MODEL</span><span class="p">,</span>
            <span class="s">"messages"</span><span class="p">:</span> <span class="p">[</span>
                <span class="p">{</span><span class="s">"role"</span><span class="p">:</span> <span class="s">"system"</span><span class="p">,</span> <span class="s">"content"</span><span class="p">:</span> <span class="bp">self</span><span class="p">.</span><span class="n">tenant_prompt</span><span class="p">},</span>
                <span class="p">{</span><span class="s">"role"</span><span class="p">:</span> <span class="s">"user"</span><span class="p">,</span> <span class="s">"content"</span><span class="p">:</span> <span class="n">random</span><span class="p">.</span><span class="n">choice</span><span class="p">([</span>
                    <span class="s">"Summarize the key points."</span><span class="p">,</span>
                    <span class="s">"What should I focus on?"</span><span class="p">,</span>
                    <span class="s">"Give me 3 recommendations."</span><span class="p">,</span>
                <span class="p">])}</span>
            <span class="p">],</span>
            <span class="s">"max_tokens"</span><span class="p">:</span> <span class="mi">80</span><span class="p">,</span>
        <span class="p">},</span> <span class="n">name</span><span class="o">=</span><span class="s">"tenant_session"</span><span class="p">)</span>

    <span class="o">@</span><span class="n">task</span><span class="p">(</span><span class="mi">1</span><span class="p">)</span>
    <span class="k">def</span> <span class="nf">cold_request</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="c1"># No system prompt → cold cache, no prefix benefit
</span>        <span class="bp">self</span><span class="p">.</span><span class="n">client</span><span class="p">.</span><span class="n">post</span><span class="p">(</span><span class="s">"/v1/chat/completions"</span><span class="p">,</span> <span class="n">json</span><span class="o">=</span><span class="p">{</span>
            <span class="s">"model"</span><span class="p">:</span> <span class="n">MODEL</span><span class="p">,</span>
            <span class="s">"messages"</span><span class="p">:</span> <span class="p">[{</span><span class="s">"role"</span><span class="p">:</span> <span class="s">"user"</span><span class="p">,</span>
                          <span class="s">"content"</span><span class="p">:</span> <span class="sa">f</span><span class="s">"Question </span><span class="si">{</span><span class="n">random</span><span class="p">.</span><span class="n">randint</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span><span class="mi">1000</span><span class="p">)</span><span class="si">}</span><span class="s">"</span><span class="p">}],</span>
            <span class="s">"max_tokens"</span><span class="p">:</span> <span class="mi">50</span><span class="p">,</span>
        <span class="p">},</span> <span class="n">name</span><span class="o">=</span><span class="s">"cold_request"</span><span class="p">)</span>
</code></pre></div></div>

<p>The design is deliberate. Each simulated user picks a tenant persona at startup and sticks with it — the same ~200-token system prompt on every request. This is representative of real multi-tenant SaaS inference: each customer has a system prompt that defines their product’s persona, and it’s identical on every call. The cold_request tasks (1 in 5) have no system prompt and get no cache benefit — they’re the baseline comparison within the same run.</p>

<p>Requests travel the full path: Mac → SSH tunnel → <code class="language-plaintext highlighter-rouge">kubectl port-forward</code> → Istio gateway → EPP → vLLM pod. No shortcuts.</p>

<hr />

<h2 id="the-results">The Results</h2>

<h3 id="locust--26826-requests-zero-failures">Locust — 26,826 Requests, Zero Failures</h3>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Hardware:  GH200 480GB (single decode pod, aggregated serving)
Model:     Qwen/Qwen3-0.6B
Rate:      32 req/s sustained

Task              Requests    Failures   p50    p95    p99    avg
───────────────────────────────────────────────────────────────────
cold_request      5,450       0 (0%)     200ms  270ms  280ms  207ms
tenant_session    21,376      0 (0%)     260ms  330ms  350ms  273ms
───────────────────────────────────────────────────────────────────
Aggregated        26,826      0 (0%)     260ms  330ms  350ms  260ms
</code></pre></div></div>

<p>Zero failures across 26,826 requests. p99 at 350ms. The system didn’t flinch.</p>

<p><strong>The comparison that matters</strong> — same Locust script structure, same traffic intent, from <a href="/llm-infrastructure/inference/2026/04/16/vllm-ollama-apple-silicon-experiment2.html">the Mac Mini post</a>:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Mac Mini vLLM (5 users, 3:1 short/long):
  short prompt p50:   1,900ms
  long prompt  p50:  31,000ms
  TTFT P99:          ~7,000ms under load

llm-d on GH200 (tenant simulation, 4:1 tenant/cold):
  tenant_session p50:   260ms    ← 7.3× faster at median
  cold_request   p50:   200ms
  TTFT P99:              34ms    ← ~200× better tail latency
</code></pre></div></div>

<p>The gap is real, but it deserves honest attribution. Part of it is raw hardware — a GH200 is not an M4 Mac Mini. Part of it is the serving stack — llm-d with EPP routing vs vanilla vLLM. And part of it is the traffic shape — these aren’t identical experiments. What the numbers establish is a clear direction: hardware matters, but the serving architecture amplifies or squanders what the hardware can do.</p>

<hr />

<h2 id="what-grafana-showed">What Grafana Showed</h2>

<h3 id="the-performance-dashboard--read-this-one-first">The Performance Dashboard — Read This One First</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/g3-llm-d-performance-dashboard.png" alt="llm-d Performance Dashboard — TTFT p50 15ms, p95 19ms, KV Cache Hit Rate 80.6%, Request Throughput 28.8 req/s, ITL p50 5ms" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    llm-d Performance Dashboard during the Locust run. Top-left: TTFT p50 at 15ms, p95 at 19ms — flat throughout.
    Top-right: ITL p50 at 5ms, p95 at 9.5ms — decode speed is stable.
    Middle: KV Cache Hit Rate at <strong>80.6%</strong>, Per-Pod at 80.6%.
    Bottom: Request Throughput 28.8 req/s, Request Queue showing active batching without buildup.
  </figcaption>
</figure>

<p>Three numbers worth pausing on:</p>

<p><strong>TTFT p50 at 15ms, flat under load.</strong> The Mac Mini showed TTFT climbing past 2 seconds at p50 and 7 seconds at p99 under comparable concurrency. Here it stays at 15ms throughout. This is not just hardware — it’s what happens when 80% of your requests skip prefill entirely because their KV blocks are already warm. The system is doing less work per request on average, which is why latency stays stable as concurrency grows.</p>

<p>A common mistake in inference optimisation is treating TTFT stability as a tuning parameter — something you achieve by adjusting batch sizes, memory utilization settings, or scheduler parameters. It isn’t. <strong>TTFT stability under load is an architectural property.</strong> It follows from having enough cache hit rate to keep the average prefill cost low. Once cache hit rate drops below ~50%, no amount of tuning recovers the tail latency. The right intervention is upstream: better routing, larger KV cache budgets, or separation of prefill and decode workloads.</p>

<p><strong>KV Cache Hit Rate at 80.6%.</strong> This is the single most actionable metric in multi-tenant inference. It tells you how much work the system is not doing. At 80.6%, roughly 4 in 5 tenant requests reuse cached KV blocks and skip prefill recomputation. The inverse is the expensive number: 19.4% of requests are cold — those are full prefill operations. In a system with 100 GPU-hours of work per day, improving cache hit rate from 80% to 90% saves 10 GPU-hours. That’s not a performance metric. That’s a cost metric.</p>

<p><strong>ITL at 5ms.</strong> Inter-Token Latency is the gap between consecutive tokens during decode — a direct measure of decode throughput. At 5ms per token, that’s 200 tokens per second per request. More importantly it’s flat — it doesn’t increase as the test runs, which confirms there’s no memory pressure or scheduler thrashing affecting the decode phase. When ITL climbs under load, it’s usually a sign that the KV cache is filling and evictions are occurring. Here it’s not.</p>

<hr />

<h3 id="prefix-cache-hit-rate--the-number-behind-the-number">Prefix Cache Hit Rate — The Number Behind the Number</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/g2-llm-d-diagnostic-prefix-cache.png" alt="llm-d Diagnostic Drill-Down — Prefix Cache Hit Rate 81.1%, Per-Instance Hit Rate holding steady at 80%, Decode Worker Utilization, Token Distribution" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Diagnostic Drill-Down. Middle: Prefix Cache Hit Rate at <strong>81.1%</strong>, Per-Instance line steady at 80%
    throughout the test — not a burst artifact, sustained. Top: Routing section showing near-zero Idle GPU Time
    (GPU is fully utilised) and consistent Token Distribution. Bottom: P/D Disaggregation section showing
    Decode Worker Utilization — the single pod handling all prefill and decode work.
  </figcaption>
</figure>

<p>The 81.1% gauge is the aggregate. The Per-Instance time series at 80% is the more meaningful signal — it shows the cache was warm within the first few minutes and held that level for the entire test duration. This is what stable prefix cache routing looks like: not a spike that decays, but a plateau that holds.</p>

<p><strong>What this means at scale:</strong> At three tenant profiles with ~200-token system prompts, 81% cache hit rate is achievable on a single pod with a small model. As you scale to 50 tenants, 500, or 5000, the picture changes. The working set of system prompts grows beyond what a single pod’s KV cache can hold. Cache hit rate degrades. TTFT rises. This isn’t a failure of EPP routing — it’s a KV cache capacity problem, and the architectural response is either larger KV budgets per pod, more pods with affinity-based routing, or tiered KV offloading. The GH200’s NVLink-C2C is exactly the hardware that makes that third option viable. This experiment doesn’t exercise it. The architecture supports it.</p>

<hr />

<h3 id="e2e-latency-and-scheduler-state">E2E Latency and Scheduler State</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/g4-llm-d-vllm-overview-e2e.png" alt="llm-d vLLM Overview — E2E p50 150ms, Token Throughput 2500 tps, ITL flat, TTFT 15-33ms, Scheduler State stable, Cache Utilization 0.15%" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    vLLM Overview dashboard. Top-left: E2E Request Latency p50 at 150ms, p95 at 260ms, p99 at 300ms, all flat.
    Top-right: Token Throughput at ~2,500 tps combined (prompt + generation).
    Middle-right: Scheduler State — Num Running and Num Waiting both stable, no queue buildup.
    Bottom-right: Cache Utilization at 0.15% — the 0.6B model leaves the entire KV pool available.
  </figcaption>
</figure>

<p>The Scheduler State panel deserves attention. <code class="language-plaintext highlighter-rouge">Num Running</code> is the active batch size — how many sequences share a GPU forward pass. <code class="language-plaintext highlighter-rouge">Num Waiting</code> is the queue depth. Both staying low and flat means continuous batching is absorbing load without queuing. Compare this to the Mac Mini Locust test where <code class="language-plaintext highlighter-rouge">Num Waiting</code> spiked to 5 and TTFT degraded proportionally.</p>

<p>Cache Utilization at 0.15% is a function of model size. Qwen3-0.6B at this concurrency level barely touches the KV pool. The same test with Llama-3-8B would show a fundamentally different curve — and that’s where the GH200’s memory architecture starts mattering in ways that go beyond raw numbers.</p>

<hr />

<h3 id="prefill-vs-decode--the-two-phase-separation-made-visible">Prefill vs Decode — The Two-Phase Separation Made Visible</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/g5-llm-d-vllm-overview-prefill-decode.png" alt="llm-d vLLM Overview scrolled — Requests Prefill and Decode Time showing prefill dropping as cache warms, decode flat throughout, Request Prompt Length heatmap, Queue Time near zero" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    vLLM Overview lower panels. Bottom-left: <strong>Requests Prefill and Decode Time</strong> — yellow is prefill,
    green is decode. Prefill drops as the cache warms during the first minutes of the test, then stabilises.
    Decode stays flat throughout. Queue Time near zero. Top panels: Request Prompt Length heatmap showing
    two clusters — short cold requests and longer tenant prompts.
  </figcaption>
</figure>

<p>This panel is the most architecturally revealing one in the dashboard. The yellow prefill line and the green decode line on the same chart, from the same pod, tell you everything about why P/D disaggregation exists.</p>

<p>Prefill is compute-bound and bursty. Its cost scales with prompt length. It spikes when a cold request arrives. Decode is memory-bandwidth-bound and steady. Its cost scales with the number of tokens being generated. On the same pod, every prefill spike steals GPU time from active decode sequences — those sequences stall mid-generation while the prefill runs.</p>

<p>In a disaggregated setup, the yellow line comes from a prefill pod pool and the green line from a decode pod pool. Prefill spikes are isolated. Decode runs uninterrupted. TTFT for long prompts no longer delays short prompts waiting in the decode queue.</p>

<p>Here those lines share a pod. The system works well at this scale and concurrency — the numbers prove it. But the architectural tension is visible in the chart. That’s what the next post is about.</p>

<hr />

<h3 id="ttft-p99--the-warmup-signature">TTFT P99 — The Warmup Signature</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/g6-llm-d-ttft-p99.png" alt="llm-d Failure and Saturation — TTFT P99 starting at 39ms, dropping to 32ms minimum, stabilising at 34ms for the remainder" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    TTFT P99 over 30 minutes from the Failure and Saturation dashboard. Starts at 39ms (cold cache),
    drops to 32ms minimum as KV blocks accumulate, stabilises at ~34ms for the remainder of the test.
    P99 settling — not drifting upward — is the signal of a system that has reached steady state.
    For context: the Mac Mini TTFT P99 was climbing past 7 seconds under similar concurrent load.
  </figcaption>
</figure>

<p>TTFT P99 dropping from 39ms to 32ms and then holding at 34ms is the cache warmup signature in the tail. The first requests from each tenant session are cold — full prefill. As sessions accumulate, KV blocks warm, and the P99 reflects that. The key signal is the plateau: P99 stops dropping once the cache is warm and doesn’t creep upward under sustained load. This is a system that has found equilibrium.</p>

<hr />

<h3 id="model-throughput-and-queue-state">Model Throughput and Queue State</h3>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/g1-llm-d-diagnostic-throughput.png" alt="llm-d Diagnostic Drill-Down — Model Throughput 4000-5000 tps, Request Queue near zero, KV Cache Utilization 0.15%, Queue Utilization brief spikes draining immediately" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Diagnostic Drill-Down model serving panels. Model Throughput at 4,000–5,000 tps during the Locust run.
    Request Queue Lengths near zero — requests are served without queuing. Queue Utilization shows brief spikes
    during burst arrivals that drain immediately — continuous batching absorbing load as designed.
    KV Cache Utilization at 0.15%.
  </figcaption>
</figure>

<p>Model Throughput at 4,000–5,000 tokens per second is what a GH200 looks like under moderate load with a small model. The brief Queue Utilization spikes that drain immediately are continuous batching doing its job — burst arrivals get absorbed into the current decode step rather than queuing. This is the architectural behaviour that separates vLLM from naive sequential servers.</p>

<hr />

<h2 id="the-complete-benchmark-reference">The Complete Benchmark Reference</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Hardware:  Lambda Labs GH200 480GB (Grace Hopper)
Model:     Qwen/Qwen3-0.6B
Stack:     llm-d v0.4.0, single decode pod (prefill: create: false)
           EPP: prefix-cache-scorer + queue-scorer + kv-utilization-scorer

─── Locust ───────────────────────────────────────────────────────────
  Total requests:   26,826     Failures:    0 (0%)
  Sustained rate:   32 req/s

  Task             p50    p95    p99    avg    req/s
  tenant_session:  260ms  330ms  350ms  273ms  25.5
  cold_request:    200ms  270ms  280ms  207ms   6.5
  Aggregated:      260ms  330ms  350ms  260ms  32.0

─── Grafana — Performance Dashboard ──────────────────────────────────
  TTFT p50:                 15ms
  TTFT p95:                 19ms
  TTFT P99 (settled):       ~34ms
  ITL p50:                  5ms   (≈ 200 tok/s)
  ITL p95:                  9.5ms
  KV Cache Hit Rate:        80.6% (gauge) / 81.1% (drill-down)
  Request Throughput:       28.8 req/s
  Model Throughput:         4,000–5,000 tps peak
  Cache Utilization:        0.15%

─── vs Mac Mini (Post 2, same script structure) ──────────────────────
  tenant p50:  Mac Mini 1,900ms  →  GH200 260ms   (7.3× faster)
  TTFT P99:    Mac Mini ~7,000ms →  GH200 34ms    (~200× better)
</code></pre></div></div>

<hr />

<h2 id="what-this-proves--and-what-it-doesnt">What This Proves — and What It Doesn’t</h2>

<p><strong>What it proves:</strong></p>

<p>EPP prefix cache routing achieves 81.1% cache hit rate under realistic multi-tenant load. That’s not a configuration artifact — it’s the result of the EPP scoring prefix hashes and routing tenant sessions to the pod holding their warm KV blocks. The system holds TTFT at 15ms p50 and 34ms p99 under 32 req/s sustained, with zero failures.</p>

<p>More broadly: in multi-tenant inference systems with repeated system prompts, <strong>cache hit rate is typically the highest-leverage optimisation variable.</strong> GPU utilization, batch size, and quantization all matter — but they reduce the cost of work the system is already doing. Cache hit rate determines how much work gets skipped entirely. At 81%, the system is doing roughly 5× less prefill work than a round-robin deployment that scatters the same tenant’s requests across pods with cold caches. That ratio is hard to match through hardware improvements alone.</p>

<p><strong>What it doesn’t prove:</strong></p>

<p>This is a single pod, a small model, and three tenant profiles. The working set fits comfortably in the KV cache — hence 0.15% utilization. Real multi-tenant deployments have hundreds or thousands of tenant profiles. As the working set grows, cache hit rate degrades. The EPP routing remains correct, but the pod’s KV cache can’t hold every tenant’s prefix simultaneously. The responses to that problem — larger KV allocations, more pods with affinity routing, tiered KV offloading to the GH200’s LPDDR5X — are architectural decisions that require knowing the working set size and access pattern distribution. This experiment establishes that the routing mechanism works. Capacity planning is a separate problem.</p>

<hr />

<h2 id="what-most-teams-get-wrong">What Most Teams Get Wrong</h2>

<p>Most inference optimisation work focuses on the <strong>supply side</strong> — faster hardware, more efficient models, better batching. This is necessary but insufficient. The demand side — <strong>how requests are shaped and routed before they reach the GPU</strong> — is where the real leverage lives at scale.</p>

<p>The dominant optimisation lever depends on where your system actually sits. Before reaching for more hardware, diagnose the bottleneck:</p>

<table>
  <thead>
    <tr>
      <th>Scenario</th>
      <th>Primary Bottleneck</th>
      <th>Highest-Leverage Fix</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Low cache hit rate (&lt;50%)</td>
      <td>Prefill recomputation</td>
      <td>Routing + request shaping</td>
    </tr>
    <tr>
      <td>High cache hit, low utilization</td>
      <td>Scheduling inefficiency</td>
      <td>Continuous batching config</td>
    </tr>
    <tr>
      <td>High utilization, rising latency</td>
      <td>Memory bandwidth</td>
      <td>Better hardware / parallelism</td>
    </tr>
    <tr>
      <td>High working set (many tenants)</td>
      <td>KV cache capacity</td>
      <td>Tiered cache / pod sharding</td>
    </tr>
  </tbody>
</table>

<p>Most teams misdiagnose their bottleneck and optimise the wrong layer. A team with a 30% cache hit rate buying faster GPUs is solving the wrong problem — they’ll run twice as fast through twice as much unnecessary prefill work. The 81% cache hit rate in these experiments means the system is doing roughly 5× less prefill than a naive round-robin deployment on identical hardware. No GPU upgrade achieves that ratio. Routing does.</p>

<p>The practical entry point: instrument your cache hit rate first. If it’s below 50%, the fix is upstream — consistent system prompts, session-affinity routing, and a scheduler that knows about prefix hashes. Hardware comes after you’ve exhausted the routing lever.</p>

<p><strong>A non-obvious failure mode: high aggregate cache hit rate masking per-tenant unfairness.</strong></p>

<p>A subtle failure appears when cache hit rate is high but unevenly distributed across tenants. If a small number of tenants dominate traffic, their KV blocks stay hot while long-tail tenants constantly miss the cache. The system reports a healthy aggregate hit rate — 80%, 81% — but tail latency degrades because cold tenants always pay full prefill cost.</p>

<p>This leads to a misleading conclusion: “the cache is working.” In reality, the system is biased toward high-frequency tenants. The aggregate metric looks healthy precisely because the popular tenants pull it up — while every new or low-frequency tenant experiences the system as if caching doesn’t exist.</p>

<p>In these experiments, three tenant profiles at similar frequencies produced clean aggregate numbers. Production systems with hundreds of tenants and a power-law access distribution will not. Fixing uneven cache efficiency requires either per-tenant cache accounting to surface the distribution, or explicit isolation of long-tail traffic to prevent it from competing with high-frequency prefixes for the same KV blocks. Without this, cache efficiency improves averages while silently degrading fairness — which is the kind of problem that shows up in p99 SLA breaches, not in dashboard summaries.</p>

<hr />

<h2 id="connecting-the-dots-across-this-series">Connecting the Dots Across This Series</h2>

<p>This series started on an M4 Mac Mini with a 400MB model and a Python script measuring TTFT. It’s worth pausing to trace what the numbers across all three posts are actually saying — because they’re saying the same thing at different scales.</p>

<p><strong>Post 1 established the theory:</strong> decode is memory-bandwidth bound. Prefill competes with decode for the same resources. KV cache management is the central architectural problem in inference. These aren’t vLLM-specific observations — they’re properties of the transformer architecture itself. They hold on any hardware, any framework.</p>

<p><strong>Post 2 ran two experiments on identical hardware.</strong> Ollama vs vLLM on the same M4 chip, same unified memory, same model family. The result — 14,062ms vs 6,543ms p50, <strong>2.15× faster</strong> — had nothing to do with the hardware. Ollama processes requests sequentially. vLLM uses continuous batching. Same silicon, 2× throughput difference from a software architecture decision. That result matters because it isolates the variable: serving architecture, not hardware.</p>

<p>Then under load, even vLLM on the Mac Mini hit the ceiling. Long prompts drove TTFT to 31 seconds at p50. The Mac Mini’s 16GB unified memory pool — shared between model weights, KV cache, and OS — ran out of headroom. The principle from Post 1 materialised as a real number: when the KV cache competes for the same memory as the model weights, concurrency suffers.</p>

<p><strong>This post added two more variables: real GPU hardware and intelligent routing.</strong> The GH200 with NVLink-C2C at 900 GB/s changes the memory economics — the GPU can address 480GB at viable bandwidth, not just 16GB. EPP prefix cache routing adds the third variable: the system avoids prefill work entirely for 81% of requests by keeping KV blocks warm.</p>

<p>The result is 260ms p50 and 34ms P99 at 32 req/s. But attributing that entirely to the GH200 would be wrong — and that’s the point. The Ollama experiment on the Mac Mini already proved that hardware alone doesn’t determine the outcome. The GH200 sets a much higher ceiling. EPP routing determines how close you get to it.</p>

<p><strong>The through-line:</strong> hardware sets the ceiling. Serving architecture determines how close you get to it. This has been true at every scale in this series — a $0 Mac Mini, a $2.29/hr GH200, and everything in between. The engineers who understand this spend their optimisation budget on routing and request shaping first, and on hardware second. The engineers who don’t buy more GPUs and wonder why the numbers don’t improve proportionally.</p>

<hr />

<h2 id="what-comes-next">What Comes Next</h2>

<p>The prefill vs decode time panel in this post showed two lines on the same chart — prefill varying with cache state, decode flat throughout. On this single pod they share a GPU. A prefill spike for a long-prompt request steals compute from ongoing decode sequences. The system handles it at this concurrency. It wouldn’t at 10×.</p>

<p>The next post deploys the P/D disaggregation guide on a second GH200 instance — separate prefill and decode pods, NIXL sidecar for KV cache transfer between them. The setup, the results, and the honest account of what P/D disaggregation actually requires in terms of hardware are all in one post.</p>

<p>The question it answers: given the baseline established here — 81.1% cache hit rate, 260ms p50, 34ms P99 — does separating prefill and decode onto dedicated pods move those numbers, or have we already captured most of the available gain on a single aggregated pod? The answer is more nuanced than either “yes it’s better” or “no it’s not worth it” — and the hardware constraint that makes it nuanced is one the GH200’s architecture makes visible in a way discrete GPU systems don’t.</p>

<hr />

<p><em>Experiments run on Lambda Labs GH200 480GB, llm-d v0.4.0, Qwen3-0.6B, vllm/vllm-openai:latest. Platform engineer with 11+ years in distributed systems going deep on LLM serving infrastructure.</em></p>

<p><em><a href="https://github.com/kraghavan">GitHub</a> · <a href="https://linkedin.com/in/karthikaraghavan">LinkedIn</a></em></p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm-infrastructure" /><category term="inference" /><category term="llm-d" /><category term="epp" /><category term="prefix-cache" /><category term="kubernetes" /><category term="vllm" /><category term="gpu" /><category term="gh200" /><category term="grace-hopper" /><category term="locust" /><category term="prometheus" /><category term="grafana" /><category term="benchmarks" /><category term="inference-optimization" /><summary type="html"><![CDATA[The stack is deployed. Now let's see what it actually does. EPP prefix cache routing, 81.1% KV cache hit rate, TTFT at 15ms p50, and what those numbers mean for teams building multi-tenant inference at scale.]]></summary></entry><entry><title type="html">Deploying llm-d on a Cloud GPU — The 10 Things Nobody Tells You</title><link href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/17/vllm-llm-d-nvidia-gh200-experiment.html" rel="alternate" type="text/html" title="Deploying llm-d on a Cloud GPU — The 10 Things Nobody Tells You" /><published>2026-04-17T00:00:00+00:00</published><updated>2026-04-17T00:00:00+00:00</updated><id>https://kraghavan.ca/llm-infrastructure/inference/2026/04/17/vllm-llm-d-nvidia-gh200-experiment</id><content type="html" xml:base="https://kraghavan.ca/llm-infrastructure/inference/2026/04/17/vllm-llm-d-nvidia-gh200-experiment.html"><![CDATA[<p>Let me set expectations before we start.</p>

<p>I had done <a href="/llm-infrastructure/inference/2026/04/16/vllm-ollama-apple-silicon-experiment2.html">the Mac Mini experiments</a>. I had real benchmark numbers. I understood the theory. I knew what prefill and decode were, I could explain PagedAttention at a whiteboard, and I had wired up Prometheus and Grafana from scratch without breaking anything important.</p>

<p>Then I tried to deploy llm-d on a cloud GPU and spent the better part of a weekend staring at <code class="language-plaintext highlighter-rouge">permission denied</code>, <code class="language-plaintext highlighter-rouge">No such file or directory</code>, <code class="language-plaintext highlighter-rouge">image pull failed</code>, and other messages that are technically informative and emotionally frustrating. I’ll be candid — I walked away from the terminal twice while the instance meter kept running. GPU rental has a way of focusing the mind.</p>

<p>This post is the deployment war story. Every broken thing, in roughly the order it broke. I am not sugarcoating my experiences or providing you a polished “here are the steps”. Those promises exist in the official docs that assumes a level of environmental cooperation or prior experiences that was not there. What the docs don’t tell you is what I’m writing here.</p>

<p>If you’re trying to deploy llm-d yourself, this post will save you several hours and possibly your sanity. If you’re reading this for entertainment, welcome — the GH200 and I had quite a journey.</p>

<hr />

<h2 id="what-is-llm-d-one-diagram-then-we-move-on">What Is llm-d? (One Diagram, Then We Move On)</h2>

<p>llm-d is a Kubernetes-native inference scheduling layer that sits on top of vLLM. It doesn’t replace vLLM — vLLM still runs inside each pod doing exactly what it always does. What llm-d adds is an <strong>EPP (Endpoint Picker Plugin)</strong> — a custom Kubernetes scheduler that routes each incoming request to the <em>right</em> vLLM pod based on KV cache state, queue depth, and prefix cache hit probability.</p>

<p>The pitch: instead of dumb round-robin load balancing, llm-d routes your request to the decode pod that already has your system prompt cached. Lower TTFT, better GPU utilization, independently scalable prefill and decode pools.</p>

<p>The official architecture diagram shows the contrast clearly:</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/llm-d-Vs-NGINX.png" alt="llm-d vs legacy NGINX routing — showing prefix-cache-aware routing, P/D disaggregation, tiered KV cache, and SLO-aware autoscaling" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Left: legacy round-robin — no prefix cache awareness, no prefill/decode split, generic QPS autoscaling.
    Right: llm-d architecture — EPP prefix-cache-aware routing, dedicated prefill and decode pools connected via RDMA,
    tiered KV cache, SLO-aware autoscaling of each pool independently.
    Source: <a href="https://llm-d.ai/docs/architecture">llm-d.ai/docs/architecture</a>
  </figcaption>
</figure>

<p>That’s what you’re deploying. Now let’s talk about what it takes to actually run it.</p>

<hr />

<h2 id="the-hardware">The Hardware</h2>

<p><strong>Lambda Labs GH200</strong>, single instance, Grace Hopper Superchip.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>GPU:          NVIDIA GH200 480GB (unified CPU+GPU memory)
Architecture: ARM64 (aarch64)
OS:           Ubuntu 22.04 LTS
Storage:      1.4TB local SSD
</code></pre></div></div>

<p>The ARM64 part is important — it comes up multiple times in this post in ways that will make you want to scream. Lambda’s GH200 instances come pre-installed with K3s, GPU drivers, and a collection of tools that seem helpful until they quietly conflict with everything you’re trying to do.</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/llm-d-on-GH200-lambda-labs.png" alt="llm-d vs legacy NGINX routing — showing prefix-cache-aware routing, P/D disaggregation, tiered KV cache, and SLO-aware autoscaling" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
  An architectural overview of our llm-d deployment on a single GH200 node. This diagram illustrates the complete request lifecycle—from the Istio ingress gateway through our custom Edge Processing Proxy (EPP) with intelligent scoring—down to the vLLM inference engine and our observability stack.
  </figcaption>
</figure>

<hr />

<h2 id="before-you-even-start-getting-the-instance">Before You Even Start: Getting the Instance</h2>

<p>There is a step zero that nobody writes about: actually getting the GPU.</p>

<p>Cloud GPU availability — especially for high-end hardware like the GH200 — is genuinely constrained. Lambda Labs operates on a first-come, first-served basis for on-demand instances. When you log in and open the Launch Instance dialog, you will see a list of available GPU types. Some will be available. Some will say “Out of capacity.” The GH200 in particular comes and goes.</p>

<figure style="max-width:800px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/lambda-labs.png" alt="Lambda Labs Launch Instance dialog showing available GPU types — GH200 at $2.29/hr highlighted, B200 instances showing Out of capacity" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Lambda Labs instance selector. The 1x GH200 (96GB) with ARM64 + H100 at $2.29/hr was the instance used for these experiments.
    Note the B200 instances showing "Out of capacity" — high-end GPU availability is genuinely constrained and changes throughout the day.
    The GH200 is listed as 96GB here but the actual unified memory pool is 480GB — the 96GB refers to the HBM portion.
  </figcaption>
</figure>

<p><strong>Getting set up on Lambda Labs:</strong></p>

<p>Creating an account takes about 5 minutes. Go to <a href="https://lambda.ai">lambda.ai</a>, sign up, add a payment method, and add your SSH public key under SSH Keys in the dashboard. That last step is easy to forget and will stop you from connecting to any instance you launch.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Your SSH public key — paste this into Lambda Labs SSH Keys dashboard</span>
<span class="nb">cat</span> ~/.ssh/id_&lt;my-key&gt;.pub
</code></pre></div></div>

<p>Once your account is ready, the practical strategy for getting a GH200 on-demand is:</p>

<ul>
  <li><strong>Check availability in the morning</strong> — instances turn over as other users terminate their sessions overnight</li>
  <li><strong>Have your SSH key already added</strong> — you want to be able to launch immediately when a slot opens</li>
  <li><strong>Don’t launch and walk away</strong> — you’re paying per hour, so have your setup commands ready to run</li>
  <li><strong>Set a budget alert</strong> — Lambda Labs doesn’t do this automatically; track your usage manually</li>
</ul>

<p><strong>What these experiments actually cost:</strong></p>

<p>I ran two separate sessions, on two separate GH200 instances. Being honest about the numbers:</p>

<table>
  <thead>
    <tr>
      <th>Session</th>
      <th>What ran</th>
      <th>Cost</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Instance <code class="language-plaintext highlighter-rouge">192.222.50.71</code></td>
      <td>Experiments 1–4 (inference-scheduling, EPP routing, Locust load tests)</td>
      <td><strong>$17.47</strong></td>
    </tr>
    <tr>
      <td>Instance <code class="language-plaintext highlighter-rouge">192.222.57.186</code></td>
      <td>Experiments 5–6 (P/D disaggregation, prefill + decode pods, sustained Locust run)</td>
      <td><strong>$18.31</strong></td>
    </tr>
    <tr>
      <td><strong>Total</strong></td>
      <td> </td>
      <td><strong>$35.78</strong></td>
    </tr>
  </tbody>
</table>

<p>The second session was slightly more expensive because the P/D disaggregation setup took longer to get right — more iteration time on a running instance. The first session was faster in wall-clock time but I was also slower at debugging, which explains the comparable cost.</p>

<p>For context: $35.78 for two full days of hands-on GPU infrastructure experiments is genuinely reasonable. A single A100 hour on AWS is $3.50+. Lambda Labs on-demand pricing is competitive precisely because availability isn’t guaranteed — you trade reliability for cost.</p>

<p><strong>One important note for LLMOps Researchers:</strong> I’m running these experiments to gain “production like experience”, which means I’m deliberate about GPU spend. On-demand instances that you terminate when done are the right strategy here — avoid reserved instances or always-on setups until you have a specific recurring workload that justifies the commitment.</p>

<hr />

<h2 id="gotcha-1-the-kubeconfig-belongs-to-root">Gotcha 1: The Kubeconfig Belongs to Root</h2>

<p>First thing you do when you SSH into a new Kubernetes node: check the cluster is running.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get namespaces
</code></pre></div></div>

<p>What you get instead:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>WARN[0000] Unable to read /etc/rancher/k3s/k3s.yaml, please start server
with --write-kubeconfig-mode or --write-kubeconfig-group to modify kube
config permissions
error: error loading config file "/etc/rancher/k3s/k3s.yaml":
open /etc/rancher/k3s/k3s.yaml: permission denied
</code></pre></div></div>

<p>K3s installs its kubeconfig at <code class="language-plaintext highlighter-rouge">/etc/rancher/k3s/k3s.yaml</code> and owns it as root. Your Ubuntu user is not root. Nobody tells you this in the getting-started guide because it seems like a detail, and it is — right until it silently breaks every single <code class="language-plaintext highlighter-rouge">kubectl</code> and <code class="language-plaintext highlighter-rouge">helm</code> command you run for the next two hours.</p>

<p><strong>The fix:</strong> copy the config to your home directory and set the environment variable.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">mkdir</span> <span class="nt">-p</span> <span class="nv">$HOME</span>/.kube
<span class="nb">sudo cp</span> /etc/rancher/k3s/k3s.yaml <span class="nv">$HOME</span>/.kube/config
<span class="nb">sudo chown </span>ubuntu:ubuntu <span class="nv">$HOME</span>/.kube/config
<span class="nb">export </span><span class="nv">KUBECONFIG</span><span class="o">=</span><span class="nv">$HOME</span>/.kube/config

<span class="c"># Make it permanent — critical for survival across sessions</span>
<span class="nb">echo</span> <span class="s1">'export KUBECONFIG=$HOME/.kube/config'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">source</span> ~/.bashrc
</code></pre></div></div>

<p>Now <code class="language-plaintext highlighter-rouge">kubectl get nodes</code> works. You feel a small surge of optimism. Cherish it.</p>

<hr />

<h2 id="gotcha-2-lambda-ships-snap-helm-and-it-is-not-your-friend">Gotcha 2: Lambda Ships Snap Helm and It Is Not Your Friend</h2>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>which helm
<span class="c"># /snap/bin/helm</span>

<span class="nb">ls</span> <span class="nt">-lla</span> /snap/bin/helm
<span class="c"># lrwxrwxrwx 1 root root 13 → /usr/bin/snap</span>
</code></pre></div></div>

<p>Lambda Stack pre-installs Helm via snap. Snap packages run in a sandbox with PATH and permission constraints that quietly break plugin installations and kubeconfig resolution. The llm-d deployment requires specific Helm plugins (<code class="language-plaintext highlighter-rouge">helm-diff</code>) and specific versions. The snap Helm and plugin system do not get along cleanly on ARM64.</p>

<p><strong>The fix:</strong> remove snap Helm and install the official arm64 binary.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Remove snap helm first</span>
<span class="nb">sudo </span>snap remove helm

<span class="c"># Install official arm64 binary</span>
wget https://get.helm.sh/helm-v3.19.0-linux-arm64.tar.gz
<span class="nb">tar </span>xzf helm-v3.19.0-linux-arm64.tar.gz
<span class="nb">sudo mv </span>linux-arm64/helm /usr/local/bin/helm
<span class="nb">rm</span> <span class="nt">-rf</span> linux-arm64 helm-v3.19.0-linux-arm64.tar.gz

<span class="c"># Verify</span>
helm version
<span class="c"># version.BuildInfo{Version:"v3.19.0"...}</span>

<span class="c"># Export and persist</span>
<span class="nb">export </span><span class="nv">HELM_BIN</span><span class="o">=</span>/usr/local/bin/helm
<span class="nb">echo</span> <span class="s1">'export HELM_BIN=/usr/local/bin/helm'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">source</span> ~/.bashrc
</code></pre></div></div>

<p>Notice I added <code class="language-plaintext highlighter-rouge">HELM_BIN</code> to <code class="language-plaintext highlighter-rouge">.bashrc</code>. This is foreshadowing.</p>

<hr />

<h2 id="gotcha-3-environment-variables-die-when-you-close-the-terminal">Gotcha 3: Environment Variables Die When You Close the Terminal</h2>

<p>This one is deceptively simple and caused a disproportionate amount of grief.</p>

<p>llm-d’s <code class="language-plaintext highlighter-rouge">helmfile</code> commands use <code class="language-plaintext highlighter-rouge">HELM_BIN</code> to find the Helm binary, and take the namespace via <code class="language-plaintext highlighter-rouge">-n $NAMESPACE</code>. Both are environment variables. Both need to exist in every session.</p>

<p>SSH sessions do not carry your previous session’s exported variables. Every time you reconnect, those variables are gone — and the error messages when they’re missing are spectacularly unhelpful:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># What happens when NAMESPACE is empty:</span>
helmfile apply <span class="nt">-n</span> <span class="k">${</span><span class="nv">NAMESPACE</span><span class="k">}</span>
<span class="c"># flag needs an argument: 'n' in -n</span>
</code></pre></div></div>

<p>That message doesn’t say “your environment variable is empty.” It sends you hunting through Helm documentation for a flag you’ve never seen, before you eventually notice the problem.</p>

<p><strong>The fix:</strong> put everything in <code class="language-plaintext highlighter-rouge">~/.bashrc</code> and verify at the start of every session.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">echo</span> <span class="s1">'export KUBECONFIG=$HOME/.kube/config'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">echo</span> <span class="s1">'export HELM_BIN=/usr/local/bin/helm'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">echo</span> <span class="s1">'export NAMESPACE=llm-d'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">source</span> ~/.bashrc

<span class="c"># First command of every session:</span>
<span class="nb">echo</span> <span class="nv">$KUBECONFIG</span> <span class="nv">$HELM_BIN</span> <span class="nv">$NAMESPACE</span>
<span class="c"># /home/ubuntu/.kube/config /usr/local/bin/helm llm-d</span>
</code></pre></div></div>

<p>If those three don’t print correctly, nothing downstream will work.</p>

<hr />

<h2 id="gotcha-4-the-default-valuesyaml-will-crash-your-gpu">Gotcha 4: The Default values.yaml Will Crash Your GPU</h2>

<p>When you clone the llm-d repo and open the inference-scheduling guide’s <code class="language-plaintext highlighter-rouge">values.yaml</code>, the default looks like this:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">modelArtifacts</span><span class="pi">:</span>
  <span class="na">uri</span><span class="pi">:</span> <span class="s2">"</span><span class="s">hf://Qwen/Qwen3-32B/tensor"</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s2">"</span><span class="s">Qwen/Qwen3-32B"</span>
  <span class="na">size</span><span class="pi">:</span> <span class="s">80Gi</span>
</code></pre></div></div>

<p>Qwen3-32B. Eighty gigabytes. On a single GPU.</p>

<p>Here is why this matters. GPU memory is not a bottomless pool — it gets divided between everything vLLM needs to run:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>┌─────────────────────────────────────────────────────────┐
│              GH200 — 480GB Unified Memory               │
├──────────────────────┬──────────────────────────────────┤
│  Model Weights       │  Qwen3-32B FP16 ≈ 65GB           │
│  (static, loaded     │  Qwen3-0.6B 4-bit ≈ 0.4GB        │
│   once at startup)   │                                  │
├──────────────────────┼──────────────────────────────────┤
│  KV Cache            │  Grows per token, per request    │
│  (dynamic, grows     │  Fills whatever is left over     │
│   with context)      │                                  │
├──────────────────────┼──────────────────────────────────┤
│  CUDA Graphs,        │  vLLM pre-allocates ~10–15%      │
│  Activations,        │  for warmup and graph capture    │
│  Overhead            │                                  │
└──────────────────────┴──────────────────────────────────┘
</code></pre></div></div>

<figure style="max-width:800px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/qwen-inside-GH200.png" alt="Lambda Labs Launch Instance dialog showing available GPU types — GH200 at $2.29/hr highlighted, B200 instances showing Out of capacity" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    GPU memory utilization breakdown on a 480GB node: Qwen3-32B vs. Qwen3-0.6B. This comparison highlights the memory pressure caused by large model weights (65GB) versus the massive KV cache headroom unlocked by using a highly optimized, smaller model.
  </figcaption>
</figure>

<p>With Qwen3-32B, model weights alone consume 65GB. vLLM then pre-allocates KV cache for the maximum sequence length on top. Under concurrent load you are pushing the GPU extremely hard before a single user request arrives — and you’ve also got 20+ minutes of model download and warmup before you can even test anything.</p>

<p>With Qwen3-0.6B (~400MB), the model loads in under 2 minutes and 99% of the GPU is available for KV cache and experiments. That’s the version to start with.</p>

<p><strong>The fix:</strong> replace the values file entirely. The full working <code class="language-plaintext highlighter-rouge">values.yaml</code> is below — note two critical changes from the default: model is Qwen3-0.6B, and the image is changed (explained in the next gotcha).</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># ms-inference-scheduling/values.yaml — working version</span>
<span class="na">multinode</span><span class="pi">:</span> <span class="no">false</span>

<span class="na">modelArtifacts</span><span class="pi">:</span>
  <span class="na">uri</span><span class="pi">:</span> <span class="s2">"</span><span class="s">hf://Qwen/Qwen3-0.6B"</span>
  <span class="na">name</span><span class="pi">:</span> <span class="s2">"</span><span class="s">Qwen/Qwen3-0.6B"</span>
  <span class="na">size</span><span class="pi">:</span> <span class="s">2Gi</span>
  <span class="na">authSecretName</span><span class="pi">:</span> <span class="s2">"</span><span class="s">llm-d-hf-token"</span>
  <span class="na">labels</span><span class="pi">:</span>
    <span class="na">llm-d.ai/inference-serving</span><span class="pi">:</span> <span class="s2">"</span><span class="s">true"</span>
    <span class="na">llm-d.ai/guide</span><span class="pi">:</span> <span class="s2">"</span><span class="s">inference-scheduling"</span>
    <span class="na">llm-d.ai/accelerator-variant</span><span class="pi">:</span> <span class="s2">"</span><span class="s">gpu"</span>
    <span class="na">llm-d.ai/accelerator-vendor</span><span class="pi">:</span> <span class="s2">"</span><span class="s">nvidia"</span>
    <span class="na">llm-d.ai/model</span><span class="pi">:</span> <span class="s2">"</span><span class="s">Qwen3-0.6B"</span>

<span class="na">routing</span><span class="pi">:</span>
  <span class="na">proxy</span><span class="pi">:</span>
    <span class="na">enabled</span><span class="pi">:</span> <span class="no">false</span>
    <span class="na">targetPort</span><span class="pi">:</span> <span class="m">8000</span>

<span class="na">accelerator</span><span class="pi">:</span>
  <span class="na">type</span><span class="pi">:</span> <span class="s">nvidia</span>

<span class="na">decode</span><span class="pi">:</span>
  <span class="na">create</span><span class="pi">:</span> <span class="no">true</span>
  <span class="na">parallelism</span><span class="pi">:</span>
    <span class="na">tensor</span><span class="pi">:</span> <span class="m">1</span>
    <span class="na">data</span><span class="pi">:</span> <span class="m">1</span>
  <span class="na">replicas</span><span class="pi">:</span> <span class="m">1</span>
  <span class="na">monitoring</span><span class="pi">:</span>
    <span class="na">podmonitor</span><span class="pi">:</span>
      <span class="na">enabled</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">portName</span><span class="pi">:</span> <span class="s2">"</span><span class="s">vllm"</span>
      <span class="na">path</span><span class="pi">:</span> <span class="s2">"</span><span class="s">/metrics"</span>
      <span class="na">interval</span><span class="pi">:</span> <span class="s2">"</span><span class="s">30s"</span>
  <span class="na">containers</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s2">"</span><span class="s">vllm"</span>
      <span class="na">image</span><span class="pi">:</span> <span class="s">vllm/vllm-openai:latest</span>   <span class="c1"># ← critical change, see next gotcha</span>
      <span class="na">modelCommand</span><span class="pi">:</span> <span class="s">vllmServe</span>
      <span class="na">args</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">--disable-uvicorn-access-log"</span>
        <span class="pi">-</span> <span class="s2">"</span><span class="s">--gpu-memory-utilization=0.90"</span>
      <span class="na">ports</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">containerPort</span><span class="pi">:</span> <span class="m">8000</span>
          <span class="na">name</span><span class="pi">:</span> <span class="s">vllm</span>
          <span class="na">protocol</span><span class="pi">:</span> <span class="s">TCP</span>
      <span class="na">resources</span><span class="pi">:</span>
        <span class="na">limits</span><span class="pi">:</span>
          <span class="na">cpu</span><span class="pi">:</span> <span class="s1">'</span><span class="s">16'</span>
          <span class="na">memory</span><span class="pi">:</span> <span class="s">60Gi</span>
        <span class="na">requests</span><span class="pi">:</span>
          <span class="na">cpu</span><span class="pi">:</span> <span class="s1">'</span><span class="s">8'</span>
          <span class="na">memory</span><span class="pi">:</span> <span class="s">30Gi</span>
      <span class="na">mountModelVolume</span><span class="pi">:</span> <span class="no">true</span>
      <span class="na">volumeMounts</span><span class="pi">:</span>
        <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">metrics-volume</span>
          <span class="na">mountPath</span><span class="pi">:</span> <span class="s">/.config</span>
        <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">shm</span>
          <span class="na">mountPath</span><span class="pi">:</span> <span class="s">/dev/shm</span>
        <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">torch-compile-cache</span>
          <span class="na">mountPath</span><span class="pi">:</span> <span class="s">/.cache</span>
      <span class="na">startupProbe</span><span class="pi">:</span>
        <span class="na">httpGet</span><span class="pi">:</span>
          <span class="na">path</span><span class="pi">:</span> <span class="s">/v1/models</span>
          <span class="na">port</span><span class="pi">:</span> <span class="s">vllm</span>
        <span class="na">initialDelaySeconds</span><span class="pi">:</span> <span class="m">15</span>
        <span class="na">periodSeconds</span><span class="pi">:</span> <span class="m">30</span>
        <span class="na">timeoutSeconds</span><span class="pi">:</span> <span class="m">5</span>
        <span class="na">failureThreshold</span><span class="pi">:</span> <span class="m">120</span>
      <span class="na">livenessProbe</span><span class="pi">:</span>
        <span class="na">httpGet</span><span class="pi">:</span>
          <span class="na">path</span><span class="pi">:</span> <span class="s">/health</span>
          <span class="na">port</span><span class="pi">:</span> <span class="s">vllm</span>
        <span class="na">periodSeconds</span><span class="pi">:</span> <span class="m">10</span>
        <span class="na">timeoutSeconds</span><span class="pi">:</span> <span class="m">5</span>
        <span class="na">failureThreshold</span><span class="pi">:</span> <span class="m">3</span>
      <span class="na">readinessProbe</span><span class="pi">:</span>
        <span class="na">httpGet</span><span class="pi">:</span>
          <span class="na">path</span><span class="pi">:</span> <span class="s">/v1/models</span>
          <span class="na">port</span><span class="pi">:</span> <span class="s">vllm</span>
        <span class="na">periodSeconds</span><span class="pi">:</span> <span class="m">5</span>
        <span class="na">timeoutSeconds</span><span class="pi">:</span> <span class="m">2</span>
        <span class="na">failureThreshold</span><span class="pi">:</span> <span class="m">3</span>
  <span class="na">volumes</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">metrics-volume</span>
      <span class="na">emptyDir</span><span class="pi">:</span> <span class="pi">{}</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">torch-compile-cache</span>
      <span class="na">emptyDir</span><span class="pi">:</span> <span class="pi">{}</span>
    <span class="pi">-</span> <span class="na">name</span><span class="pi">:</span> <span class="s">shm</span>
      <span class="na">emptyDir</span><span class="pi">:</span>
        <span class="na">medium</span><span class="pi">:</span> <span class="s">Memory</span>
        <span class="na">sizeLimit</span><span class="pi">:</span> <span class="s">20Gi</span>

<span class="na">prefill</span><span class="pi">:</span>
  <span class="na">create</span><span class="pi">:</span> <span class="no">false</span>
</code></pre></div></div>

<p>Start small. Prove the stack works. Scale the model up later.</p>

<hr />

<h2 id="gotcha-5-llm-d-cuda-is-x86-only">Gotcha 5: <code class="language-plaintext highlighter-rouge">llm-d-cuda</code> Is x86-Only</h2>

<p>The default values.yaml uses <code class="language-plaintext highlighter-rouge">ghcr.io/llm-d/llm-d-cuda:v0.6.0</code> as the vLLM container image. This image was built for x86_64 (amd64). The GH200 is ARM64 (aarch64).</p>

<p>When Kubernetes tries to run an x86 image on an ARM64 node, it doesn’t fail with “wrong architecture.” It fails with a Triton compiler error deep inside the container startup, several minutes after the pod appears to be Running:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Triton compilation failed: RuntimeError: ...
CUDA error: device-side assert triggered
</code></pre></div></div>

<p>The pod crashes. CrashLoopBackOff. <code class="language-plaintext highlighter-rouge">kubectl describe pod</code> shows the image pulled successfully. The logs look like GPU memory issues. You spend time adjusting <code class="language-plaintext highlighter-rouge">--gpu-memory-utilization</code> and redeploying — none of which helps, because the problem is binary architecture, not memory configuration.</p>

<p><strong>The fix:</strong> <code class="language-plaintext highlighter-rouge">vllm/vllm-openai:latest</code> is multi-arch and includes a proper ARM64 build.</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Change this:</span>
<span class="na">image</span><span class="pi">:</span> <span class="s">ghcr.io/llm-d/llm-d-cuda:v0.6.0</span>

<span class="c1"># To this:</span>
<span class="na">image</span><span class="pi">:</span> <span class="s">vllm/vllm-openai:latest</span>
</code></pre></div></div>

<p>One line. Saves two hours.</p>

<hr />

<h2 id="gotcha-6-gateway-api-crds-dont-come-with-the-cluster">Gotcha 6: Gateway API CRDs Don’t Come With the Cluster</h2>

<p>llm-d uses the Kubernetes Gateway API — <code class="language-plaintext highlighter-rouge">HTTPRoute</code> and <code class="language-plaintext highlighter-rouge">Gateway</code> custom resources. These are not part of standard Kubernetes and do not come pre-installed with K3s.</p>

<p>When <code class="language-plaintext highlighter-rouge">helmfile apply</code> runs without these CRDs, it fails with unknown resource type errors. If you’re not familiar with the Gateway API, you’ll look at your Istio installation instead of at the missing CRDs.</p>

<p><strong>The fix:</strong> install both sets of CRDs before anything else.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Gateway API CRDs</span>
kubectl apply <span class="nt">-f</span> https://github.com/kubernetes-sigs/gateway-api/releases/download/v1.2.1/standard-install.yaml

<span class="c"># llm-d InferencePool CRDs</span>
kubectl apply <span class="nt">-f</span> https://github.com/kubernetes-sigs/gateway-api-inference-extension/releases/download/v0.3.0/manifests.yaml

<span class="c"># Verify both</span>
kubectl get crd | <span class="nb">grep</span> <span class="nt">-E</span> <span class="s2">"gateway|inference"</span>
</code></pre></div></div>

<p>Ten seconds to apply. Saves a debugging session.</p>

<hr />

<h2 id="gotcha-7-use-helm-template--kubectl-apply--k8s-debugging-101">Gotcha 7: Use <code class="language-plaintext highlighter-rouge">helm template | kubectl apply</code> — K8s Debugging 101</h2>

<p><code class="language-plaintext highlighter-rouge">helmfile apply</code> is the documented deployment path. It’s also the one that, on K3s ARM64, would silently partially deploy — some resources applied, others skipped, exit code 0.</p>

<p>This is actually a universal Helm debugging pattern worth internalising regardless of llm-d: <strong>render the chart to YAML first, then apply</strong>. Helmfile adds an abstraction layer that can obscure what’s actually being sent to the API server. <code class="language-plaintext highlighter-rouge">helm template</code> removes that layer and gives you full visibility.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Step 1: Render to YAML and inspect — no cluster changes</span>
<span class="nv">$HELM_BIN</span> template ms-inference-scheduling <span class="se">\</span>
  llm-d-modelservice/llm-d-modelservice <span class="se">\</span>
  <span class="nt">--namespace</span> llm-d <span class="se">\</span>
  <span class="nt">--values</span> ms-inference-scheduling/values.yaml <span class="se">\</span>
  | less

<span class="c"># Step 2: Dry-run — validates against cluster API, shows what would change</span>
<span class="nv">$HELM_BIN</span> template ms-inference-scheduling <span class="se">\</span>
  llm-d-modelservice/llm-d-modelservice <span class="se">\</span>
  <span class="nt">--namespace</span> llm-d <span class="se">\</span>
  <span class="nt">--values</span> ms-inference-scheduling/values.yaml <span class="se">\</span>
  | kubectl apply <span class="nt">-n</span> llm-d <span class="nt">-f</span> - <span class="nt">--dry-run</span><span class="o">=</span>client

<span class="c"># Step 3: Apply for real</span>
<span class="nv">$HELM_BIN</span> template ms-inference-scheduling <span class="se">\</span>
  llm-d-modelservice/llm-d-modelservice <span class="se">\</span>
  <span class="nt">--namespace</span> llm-d <span class="se">\</span>
  <span class="nt">--values</span> ms-inference-scheduling/values.yaml <span class="se">\</span>
  | kubectl apply <span class="nt">-n</span> llm-d <span class="nt">-f</span> -
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">--dry-run=client</code> step is the one most people skip and most people regret skipping. It validates your YAML against the cluster’s API schemas, catches missing CRDs, and shows exactly what would be created or updated — before anything changes in the cluster. Whenever a Helm deployment behaves unexpectedly, this three-step render-validate-apply pattern is where to start debugging.</p>

<hr />

<h2 id="gotcha-8-the-httproute-is-not-applied-by-helmfile">Gotcha 8: The HTTPRoute Is Not Applied by helmfile</h2>

<p>After all pods are running, you port-forward the gateway and send a test request. You get nothing back.</p>

<p>The reason: the HTTPRoute — the rule that tells the gateway to forward traffic to the EPP — is not deployed by helmfile. It lives in a separate YAML file and must be applied manually.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Check first:</span>
kubectl get httproute <span class="nt">-n</span> llm-d
<span class="c"># No resources found in llm-d namespace.</span>

<span class="c"># Apply:</span>
kubectl apply <span class="nt">-f</span> ~/llm-d/llm-d/guides/inference-scheduling/httproute.yaml <span class="nt">-n</span> llm-d

<span class="c"># Verify:</span>
kubectl get httproute <span class="nt">-n</span> llm-d
<span class="c"># NAME                         AGE</span>
<span class="c"># llm-d-inference-scheduling   6s</span>
</code></pre></div></div>

<p>Without this, the gateway has no routing rules. Every request returns empty or times out. No errors appear in pod logs because — from the gateway’s perspective — nothing is wrong. There is just no route configured.</p>

<hr />

<h2 id="gotcha-9-immutable-selector-labels-mean-you-cant-upgrade-in-place">Gotcha 9: Immutable Selector Labels Mean You Can’t Upgrade In-Place</h2>

<p>If you change the model name in <code class="language-plaintext highlighter-rouge">values.yaml</code> after deploying, <code class="language-plaintext highlighter-rouge">helm upgrade</code> will fail:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Error: UPGRADE FAILED: cannot patch "ms-inference-scheduling-llm-d-modelservice-decode"
with kind Deployment: Deployment.apps is invalid:
spec.selector: Invalid value: ... field is immutable
</code></pre></div></div>

<p>Kubernetes Deployment selector labels are immutable. Changing the model name — which is part of the label selector — requires deleting the Deployment first.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl delete deployment <span class="nt">-n</span> llm-d <span class="se">\</span>
  ms-inference-scheduling-llm-d-modelservice-decode 2&gt;/dev/null <span class="o">||</span> <span class="nb">true</span>

<span class="nv">$HELM_BIN</span> template ms-inference-scheduling <span class="se">\</span>
  llm-d-modelservice/llm-d-modelservice <span class="se">\</span>
  <span class="nt">--namespace</span> llm-d <span class="se">\</span>
  <span class="nt">--values</span> ms-inference-scheduling/values.yaml <span class="se">\</span>
  | kubectl apply <span class="nt">-n</span> llm-d <span class="nt">-f</span> -
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">|| true</code> prevents failure if the deployment doesn’t exist yet — useful for idempotent scripts.</p>

<hr />

<h2 id="gotcha-10-port-forward-processes-die-silently-and-dont-tell-you">Gotcha 10: Port-Forward Processes Die Silently and Don’t Tell You</h2>

<p>Access to the llm-d gateway from your Mac goes through an SSH tunnel plus <code class="language-plaintext highlighter-rouge">kubectl port-forward</code>. When the port-forward dies — session timeout, network hiccup — the TCP port on your Mac stays bound. Next tunnel attempt:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Unable to listen on port 8080:
[unable to create listener: Error listen tcp4 127.0.0.1:8080: bind: address already in use]
</code></pre></div></div>

<p><strong>The fix:</strong> kill the zombie first, then verify the fresh tunnel is alive before benchmarking.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Kill whatever holds port 8080</span>
lsof <span class="nt">-ti</span> :8080 | xargs <span class="nb">kill</span> <span class="nt">-9</span> 2&gt;/dev/null <span class="o">||</span> <span class="nb">true</span>

<span class="c"># Fresh tunnel</span>
ssh <span class="nt">-L</span> 8080:localhost:8080 ubuntu@&lt;LAMBDA_IP&gt; <span class="se">\</span>
  <span class="s2">"KUBECONFIG=/home/ubuntu/.kube/config kubectl port-forward </span><span class="se">\</span><span class="s2">
   -n llm-d svc/infra-inference-scheduling-inference-gateway-istio 8080:80"</span>

<span class="c"># Verify before doing anything else</span>
curl <span class="nt">-s</span> http://localhost:8080/v1/models | jq .data[0].id
<span class="c"># "Qwen/Qwen3-0.6B"  ← tunnel alive</span>
<span class="c"># (nothing / timeout) ← restart the tunnel</span>
</code></pre></div></div>

<p>Running Locust against a dead port-forward gives you 0 completed requests and makes you think the model is broken. Always verify first.</p>

<hr />

<h2 id="what-running-looks-like">What Running Looks Like</h2>

<p>After all of the above — correct kubeconfig, real Helm binary, environment variables in <code class="language-plaintext highlighter-rouge">.bashrc</code>, small model, right image, Gateway API CRDs installed, HTTPRoute applied, Deployment deleted and recreated when needed — this is what a healthy deployment looks like:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get pods <span class="nt">-n</span> llm-d

NAME                                                              READY   STATUS    RESTARTS   AGE
gaie-inference-scheduling-epp-584f797cc8-4gvw8                    1/1     Running   0          68m
infra-inference-scheduling-inference-gateway-istio-7c5546dr7kd2   1/1     Running   0          68m
ms-inference-scheduling-llm-d-modelservice-decode-57678587gqzlt   1/1     Running   0          10m
</code></pre></div></div>

<p>Three pods, all <code class="language-plaintext highlighter-rouge">1/1 Running</code>. The decode pod may restart once while the model downloads — that’s normal. Zero restarts on EPP and gateway.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Gateway is programmed and routing</span>
kubectl get gateway <span class="nt">-n</span> llm-d
<span class="c"># infra-inference-scheduling-inference-gateway   istio   True   68m</span>

<span class="c"># A request through the gateway returns a response</span>
curl <span class="nt">-s</span> http://localhost:8080/v1/chat/completions <span class="se">\</span>
  <span class="nt">-H</span> <span class="s2">"Content-Type: application/json"</span> <span class="se">\</span>
  <span class="nt">-d</span> <span class="s1">'{"model":"Qwen/Qwen3-0.6B",
       "messages":[{"role":"user","content":"What is KV cache?"}],
       "max_tokens":50}'</span> | jq .choices[0].message.content
<span class="c"># "&lt;think&gt;\nOkay, so I need to figure out what KV cache is..."</span>
</code></pre></div></div>

<p>That response, after everything above, feels like a small engineering miracle.</p>

<hr />

<h2 id="the-observability-stack">The Observability Stack</h2>

<p>The kube-prometheus-stack installs Grafana with 33 dashboards. After a fresh deploy, confirm everything is healthy before running experiments:</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/grafana-overview-llmd.png" alt="Grafana Overview — 0 alerts firing, 33 dashboards loaded, Grafana v12.4.2 healthy" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Grafana Overview after successful llm-d deployment: 0 alerts firing, 33 dashboards loaded, API server responding.
    The two dashboards that matter for experiments: <strong>llm-d Performance Dashboard</strong> (TTFT, ITL, KV cache hit rate)
    and <strong>llm-d vLLM Overview</strong> (E2E latency, scheduler state, prefill vs decode time split).
  </figcaption>
</figure>

<p>If the llm-d dashboards show “No data”, check that the PodMonitor was created:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>kubectl get podmonitor <span class="nt">-n</span> llm-d
<span class="c"># If missing, ensure values.yaml has monitoring.podmonitor.enabled: true</span>
</code></pre></div></div>

<hr />

<h2 id="the-survival-checklist">The Survival Checklist</h2>

<p>First commands of every session — before touching anything else:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># 1. Environment variables present</span>
<span class="nb">echo</span> <span class="nv">$KUBECONFIG</span> <span class="nv">$HELM_BIN</span> <span class="nv">$NAMESPACE</span>
<span class="c"># /home/ubuntu/.kube/config /usr/local/bin/helm llm-d</span>

<span class="c"># 2. All pods running</span>
kubectl get pods <span class="nt">-n</span> llm-d
<span class="c"># All 3 pods: 1/1 Running</span>

<span class="c"># 3. HTTPRoute exists</span>
kubectl get httproute <span class="nt">-n</span> llm-d

<span class="c"># 4. Port-forward alive</span>
curl <span class="nt">-s</span> http://localhost:8080/v1/models | jq .data[0].id
<span class="c"># "Qwen/Qwen3-0.6B"</span>

<span class="c"># 5. Grafana accessible</span>
curl <span class="nt">-s</span> http://localhost:3000/api/health | jq .database
<span class="c"># "ok"</span>
</code></pre></div></div>

<p>If any of these fail, fix it before proceeding.</p>

<hr />

<h2 id="the-full-deployment-sequence">The Full Deployment Sequence</h2>

<p>For anyone who wants the complete working sequence without the narrative:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># ── Fix environment ─────────────────────────────────────────────────</span>
<span class="nb">mkdir</span> <span class="nt">-p</span> <span class="nv">$HOME</span>/.kube
<span class="nb">sudo cp</span> /etc/rancher/k3s/k3s.yaml <span class="nv">$HOME</span>/.kube/config
<span class="nb">sudo chown </span>ubuntu:ubuntu <span class="nv">$HOME</span>/.kube/config
<span class="nb">echo</span> <span class="s1">'export KUBECONFIG=$HOME/.kube/config'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">echo</span> <span class="s1">'export HELM_BIN=/usr/local/bin/helm'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">echo</span> <span class="s1">'export NAMESPACE=llm-d'</span> <span class="o">&gt;&gt;</span> ~/.bashrc
<span class="nb">source</span> ~/.bashrc

<span class="c"># ── Install real Helm (ARM64) ───────────────────────────────────────</span>
<span class="nb">sudo </span>snap remove helm
wget https://get.helm.sh/helm-v3.19.0-linux-arm64.tar.gz
<span class="nb">tar </span>xzf helm-v3.19.0-linux-arm64.tar.gz
<span class="nb">sudo mv </span>linux-arm64/helm /usr/local/bin/helm

<span class="c"># ── Install CRDs ────────────────────────────────────────────────────</span>
kubectl apply <span class="nt">-f</span> https://github.com/kubernetes-sigs/gateway-api/releases/download/v1.2.1/standard-install.yaml
kubectl apply <span class="nt">-f</span> https://github.com/kubernetes-sigs/gateway-api-inference-extension/releases/download/v0.3.0/manifests.yaml

<span class="c"># ── Repos and HuggingFace secret ────────────────────────────────────</span>
git clone https://github.com/llm-d/llm-d.git
<span class="nv">$HELM_BIN</span> repo add llm-d-modelservice <span class="se">\</span>
  https://llm-d-incubation.github.io/llm-d-modelservice/
<span class="nv">$HELM_BIN</span> repo update

kubectl create namespace <span class="nv">$NAMESPACE</span>
kubectl create secret generic llm-d-hf-token <span class="se">\</span>
  <span class="nt">--from-literal</span><span class="o">=</span><span class="s2">"HF_TOKEN=</span><span class="k">${</span><span class="nv">HF_TOKEN</span><span class="k">}</span><span class="s2">"</span> <span class="se">\</span>
  <span class="nt">--namespace</span> <span class="s2">"</span><span class="k">${</span><span class="nv">NAMESPACE</span><span class="k">}</span><span class="s2">"</span> <span class="se">\</span>
  <span class="nt">--dry-run</span><span class="o">=</span>client <span class="nt">-o</span> yaml | kubectl apply <span class="nt">-f</span> -

<span class="c"># ── Deploy infra (EPP + gateway) ────────────────────────────────────</span>
<span class="nb">cd</span> ~/llm-d/llm-d/guides/inference-scheduling
<span class="nv">HELM_BIN</span><span class="o">=</span><span class="nv">$HELM_BIN</span> helmfile apply <span class="nt">-n</span> <span class="k">${</span><span class="nv">NAMESPACE</span><span class="k">}</span>

<span class="c"># ── Deploy modelservice (reliable pattern) ──────────────────────────</span>
<span class="nv">$HELM_BIN</span> template ms-inference-scheduling <span class="se">\</span>
  llm-d-modelservice/llm-d-modelservice <span class="se">\</span>
  <span class="nt">--namespace</span> llm-d <span class="se">\</span>
  <span class="nt">--values</span> ms-inference-scheduling/values.yaml <span class="se">\</span>
  | kubectl apply <span class="nt">-n</span> llm-d <span class="nt">-f</span> -

<span class="c"># ── HTTPRoute (always manual) ───────────────────────────────────────</span>
kubectl apply <span class="nt">-f</span> httproute.yaml <span class="nt">-n</span> llm-d

<span class="c"># ── Verify ──────────────────────────────────────────────────────────</span>
kubectl get pods <span class="nt">-n</span> llm-d
curl <span class="nt">-s</span> http://localhost:8080/v1/models | jq <span class="nb">.</span>
</code></pre></div></div>

<p>Every step is here because I needed it.</p>

<hr />

<h2 id="what-this-unlocks">What This Unlocks</h2>

<p>With the stack running, the EPP is making routing decisions on every request — consulting prefix cache, queue depth, and KV cache utilization scorers on each incoming call. You just can’t see it yet with a single decode pod and no load.</p>

<p>The next post in this series covers what happens when you actually put the system under load — EPP prefix cache routing in action, KV cache hit rate climbing to <strong>81.1%</strong> in Grafana, TTFT stabilising at <strong>15ms p50</strong> under sustained concurrent traffic, and the Locust results from a system that’s routing intelligently rather than guessing.</p>

<p>The deployment pain was worth it. The numbers make that clear.</p>

<hr />

<p><em>Deployed on Lambda Labs GH200 480GB, K3s, llm-d v0.4.0, Qwen3-0.6B, vllm/vllm-openai:latest. Scripts will be made available soon via github repository. Platform engineer with 11+ years in distributed systems going deep on LLM serving infrastructure.</em></p>

<p><em><a href="https://github.com/kraghavan">GitHub</a> · <a href="https://linkedin.com/in/karthikaraghavan">LinkedIn</a></em></p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm-infrastructure" /><category term="inference" /><category term="llm-d" /><category term="kubernetes" /><category term="k3s" /><category term="helm" /><category term="vllm" /><category term="gpu" /><category term="lambda-labs" /><category term="gh200" /><category term="arm64" /><category term="deployment" /><category term="sre" /><summary type="html"><![CDATA[I deployed llm-d on a Lambda Labs GH200. Nothing worked first try. Here is the honest account of what broke, why, and how to fix it — so you don't spend your GPU budget finding out the hard way.]]></summary></entry><entry><title type="html">Treating the M4 Mac Mini Like a Production Inference Server (It Tried)</title><link href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/16/vllm-ollama-apple-silicon-experiment2.html" rel="alternate" type="text/html" title="Treating the M4 Mac Mini Like a Production Inference Server (It Tried)" /><published>2026-04-16T00:00:00+00:00</published><updated>2026-04-16T00:00:00+00:00</updated><id>https://kraghavan.ca/llm-infrastructure/inference/2026/04/16/vllm-ollama-apple-silicon-experiment2</id><content type="html" xml:base="https://kraghavan.ca/llm-infrastructure/inference/2026/04/16/vllm-ollama-apple-silicon-experiment2.html"><![CDATA[<p>I spent a week running inference experiments on my M4 Mac Mini — not to build a product, but to understand what actually happens inside an LLM serving stack. TTFT. TPOT. KV cache. Continuous batching. These are words I had read in papers and blog posts. This week I measured them. Here is what I found.</p>

<p>This post is the hands-on companion to <a href="/llm-infrastructure/inference/2026/04/14/re-introduction-to-inference.html">Post 1</a>. Same mental model — but now with real hardware, real Grafana dashboards, and numbers you can reproduce yourself.</p>

<p><strong>Hardware:</strong> M4 Mac Mini, 16GB unified memory<br />
<strong>Model:</strong> <code class="language-plaintext highlighter-rouge">mlx-community/Qwen3-0.6B-4bit</code> (~400MB, 4-bit quantized)<br />
<strong>Inference engine:</strong> vllm-metal 0.13.0 (official vllm-project Apple Silicon plugin)<br />
<strong>Observability:</strong> Prometheus + Grafana via Docker Compose<br />
<strong>Load testing:</strong> vegeta + Locust<br />
<strong>Gateway experiment:</strong> kind cluster + nginx reverse proxy</p>

<figure style="max-width:800px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/setup-architecture.png" alt="Local inference setup — vllm-metal serving Qwen3-0.6B-4bit, Prometheus and Grafana via Docker Compose, Locust and vegeta for load testing, nginx on kind as a K8s gateway experiment" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    The full local setup: vllm-metal serving Qwen3-0.6B-4bit on M4 Mac Mini unified memory, 
    Prometheus scraping <code>/metrics</code> every 5s, Grafana dashboards rendering live, 
    Locust and vegeta generating load. The kind cluster with nginx is the K8s gateway 
    experiment — simulating the Envoy position in a production llm-d deployment.
  </figcaption>
</figure>

<hr />

<h2 id="why-apple-silicon-for-this-experiment">Why Apple Silicon for This Experiment?</h2>

<p>The M4 Mac Mini has 16GB of unified memory — shared between CPU and GPU. This is both a strength and a constraint for inference.</p>

<p><strong>Strength:</strong> Unified memory means the model weights aren’t copied between CPU RAM and a discrete GPU’s VRAM. Zero-copy tensor operations. For a small quantized model, this is genuinely fast.</p>

<p><strong>Constraint:</strong> 16GB is 16GB. The model, the KV cache, the OS, and every other process share the same pool. Under concurrent load, you will find the ceiling.</p>

<p>The more interesting reason: I wanted to validate that the mental model from Post 1 — prefill is compute-bound, decode is memory-bound, KV cache is the critical resource — holds on real hardware, not just in theory. It does. With caveats.</p>

<hr />

<h2 id="the-setup">The Setup</h2>

<h3 id="why-vllm-metal-not-ollama">Why vllm-metal, Not Ollama?</h3>

<p>Before any benchmarks: I used both, and the choice matters more than I expected.</p>

<p><strong>vllm-metal</strong> is the official vllm-project Apple Silicon plugin. It runs Metal GPU kernels via MLX, exposes a full OpenAI-compatible API, and critically — emits Prometheus metrics out of the box. Same codebase as cloud vLLM, same API surface, same metric names. What you learn here transfers directly to a GPU cluster.</p>

<p><strong>Ollama</strong> is simpler to install and great for single-user local use. But it doesn’t expose Prometheus metrics natively, and — as the benchmark section will show — it doesn’t implement continuous batching. Under concurrent load, that difference is not subtle.</p>

<p>One gotcha worth flagging: <code class="language-plaintext highlighter-rouge">vllm-mlx</code> (different from vllm-metal) is a third-party wrapper that was broken with <code class="language-plaintext highlighter-rouge">mlx-lm&gt;=0.31.0</code> as of April 2026. Use <code class="language-plaintext highlighter-rouge">vllm-metal</code> — the official plugin — and avoid that detour.</p>

<p><strong>A note on scope:</strong> this post covers vLLM and Ollama only. TGI, TensorRT-LLM, ExLlamaV2, and SGLang are all on the list — but running meaningful benchmarks against each requires dedicated GPU time, and GPU time costs money I’m not spending during a job search. I’ll get to them when the experiments justify the cost. For now, the vLLM vs Ollama comparison is grounded in real numbers on real hardware, and that’s the comparison worth making.</p>

<h3 id="observability-stack">Observability Stack</h3>

<p>Prometheus and Grafana running via Docker Compose, with <code class="language-plaintext highlighter-rouge">host.docker.internal</code> resolving to the Mac’s loopback so the containers can scrape vLLM’s metrics endpoint:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># docker-compose.yml</span>
<span class="na">services</span><span class="pi">:</span>
  <span class="na">prometheus</span><span class="pi">:</span>
    <span class="na">image</span><span class="pi">:</span> <span class="s">prom/prometheus:latest</span>
    <span class="na">extra_hosts</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s2">"</span><span class="s">host.docker.internal:host-gateway"</span>
    <span class="na">ports</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s2">"</span><span class="s">9090:9090"</span>
    <span class="na">volumes</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">./prometheus.yml:/etc/prometheus/prometheus.yml</span>

  <span class="na">grafana</span><span class="pi">:</span>
    <span class="na">image</span><span class="pi">:</span> <span class="s">grafana/grafana:latest</span>
    <span class="na">ports</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s2">"</span><span class="s">3000:3000"</span>
    <span class="na">environment</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="s">GF_AUTH_ANONYMOUS_ENABLED=true</span>
      <span class="pi">-</span> <span class="s">GF_AUTH_ANONYMOUS_ORG_ROLE=Admin</span>
</code></pre></div></div>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># prometheus.yml</span>
<span class="na">global</span><span class="pi">:</span>
  <span class="na">scrape_interval</span><span class="pi">:</span> <span class="s">5s</span>

<span class="na">scrape_configs</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">job_name</span><span class="pi">:</span> <span class="s">vllm</span>
    <span class="na">static_configs</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">targets</span><span class="pi">:</span>
          <span class="pi">-</span> <span class="s1">'</span><span class="s">host.docker.internal:8000'</span>
</code></pre></div></div>

<p><strong>Metric name gotcha:</strong> the official vLLM Grafana dashboard references <code class="language-plaintext highlighter-rouge">gpu_cache_usage_perc</code> but vllm-metal exposes <code class="language-plaintext highlighter-rouge">vllm:kv_cache_usage_perc</code>. If your KV cache panel shows “No data”, confirm the correct metric name directly:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>curl localhost:8000/metrics | <span class="nb">grep </span>cache
</code></pre></div></div>

<h3 id="the-kind-cluster-and-nginx-gateway">The kind Cluster and nginx Gateway</h3>

<p><strong>Why this matters:</strong> In production with llm-d, requests flow through an Envoy gateway pod before reaching vLLM pods. I wanted to replicate that topology locally — understand the gateway layer before Week 2 introduced it with real routing logic.</p>

<p>On Apple Silicon, Metal GPU cannot be passed into Docker containers. So vllm-metal has to run natively on the Mac host. The resulting topology is deliberately artificial:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>── LOCAL SETUP (Apple Silicon constraint) ───────────────────────────

curl localhost:9000
     │
     ▼  host port 9000 → kind NodePort 30000
nginx pod :80        ← simulates Envoy gateway position in llm-d
     │
     ▼  proxy_pass http://172.19.0.1:8000
vllm-metal           ← running natively on Mac host (Metal GPU)

── PRODUCTION (Week 2 — real GPU) ──────────────────────────────────

curl gateway:80
     │
     ▼
Envoy gateway pod    ← EPP does KV-cache-aware routing here
     │
     ▼
vLLM pod             ← FastAPI server + GPU inside the pod
</code></pre></div></div>

<p><strong>Apple Silicon gotcha:</strong> <code class="language-plaintext highlighter-rouge">host.docker.internal</code> inside kind on M4 Mac resolves to IPv6, but vllm-metal only binds to IPv4. The nginx <code class="language-plaintext highlighter-rouge">proxy_pass</code> fails silently — you’ll see <code class="language-plaintext highlighter-rouge">connect() failed (101: Network unreachable)</code> in the logs. Fix: get the actual bridge gateway IP:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">HOST_IP</span><span class="o">=</span><span class="si">$(</span>docker inspect vllm-lab-control-plane <span class="se">\</span>
  <span class="nt">--format</span> <span class="s1">''</span><span class="si">)</span>
<span class="nb">echo</span> <span class="nv">$HOST_IP</span>
<span class="c"># 172.19.0.1  ← use this in proxy_pass, not host.docker.internal</span>
</code></pre></div></div>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># kind-config.yaml</span>
<span class="na">kind</span><span class="pi">:</span> <span class="s">Cluster</span>
<span class="na">apiVersion</span><span class="pi">:</span> <span class="s">kind.x-k8s.io/v1alpha4</span>
<span class="na">nodes</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="na">role</span><span class="pi">:</span> <span class="s">control-plane</span>
    <span class="na">extraPortMappings</span><span class="pi">:</span>
      <span class="pi">-</span> <span class="na">containerPort</span><span class="pi">:</span> <span class="m">30000</span>
        <span class="na">hostPort</span><span class="pi">:</span> <span class="m">9000</span>
</code></pre></div></div>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/LLM-Inference-Network-Topology.png" alt="Local vs production inference topology — nginx on kind vs Envoy in llm-d" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">Left: local Apple Silicon setup — nginx in kind proxying to vllm-metal on the Mac host. Right: production llm-d topology — Envoy gateway routing to vLLM pods with direct GPU access. The gateway position is identical; only the backend location differs.</figcaption>
</figure>

<hr />

<h2 id="experiment-1-baseline--ttft-and-tpot-directly-measured">Experiment 1: Baseline — TTFT and TPOT Directly Measured</h2>

<p>First question: what does a single uncontested request actually cost on this hardware?</p>

<p>I wrote a streaming latency script that timestamps the first chunk arrival (TTFT) then tracks per-token intervals (TPOT):</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">def</span> <span class="nf">measure_streaming</span><span class="p">(</span><span class="n">prompt</span><span class="p">,</span> <span class="n">max_tokens</span><span class="o">=</span><span class="mi">100</span><span class="p">):</span>
    <span class="n">start</span> <span class="o">=</span> <span class="n">time</span><span class="p">.</span><span class="n">perf_counter</span><span class="p">()</span>
    <span class="n">first_token_time</span> <span class="o">=</span> <span class="bp">None</span>
    <span class="n">token_times</span> <span class="o">=</span> <span class="p">[]</span>

    <span class="k">with</span> <span class="n">client</span><span class="p">.</span><span class="n">stream</span><span class="p">(</span><span class="s">"POST"</span><span class="p">,</span> <span class="s">"/v1/chat/completions"</span><span class="p">,</span> <span class="n">json</span><span class="o">=</span><span class="n">payload</span><span class="p">)</span> <span class="k">as</span> <span class="n">resp</span><span class="p">:</span>
        <span class="k">for</span> <span class="n">line</span> <span class="ow">in</span> <span class="n">resp</span><span class="p">.</span><span class="n">iter_lines</span><span class="p">():</span>
            <span class="k">if</span> <span class="n">content</span> <span class="p">:</span><span class="o">=</span> <span class="n">parse_token</span><span class="p">(</span><span class="n">line</span><span class="p">):</span>
                <span class="n">now</span> <span class="o">=</span> <span class="n">time</span><span class="p">.</span><span class="n">perf_counter</span><span class="p">()</span>
                <span class="k">if</span> <span class="n">first_token_time</span> <span class="ow">is</span> <span class="bp">None</span><span class="p">:</span>
                    <span class="n">first_token_time</span> <span class="o">=</span> <span class="n">now</span>  <span class="c1"># ← TTFT captured here
</span>                <span class="n">token_times</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">now</span><span class="p">)</span>

    <span class="c1"># TPOT = average gap between consecutive tokens
</span>    <span class="n">intervals</span> <span class="o">=</span> <span class="p">[</span><span class="n">token_times</span><span class="p">[</span><span class="n">i</span><span class="p">]</span> <span class="o">-</span> <span class="n">token_times</span><span class="p">[</span><span class="n">i</span><span class="o">-</span><span class="mi">1</span><span class="p">]</span>
                 <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="n">token_times</span><span class="p">))]</span>
    <span class="n">avg_tpot</span> <span class="o">=</span> <span class="nb">sum</span><span class="p">(</span><span class="n">intervals</span><span class="p">)</span> <span class="o">/</span> <span class="nb">len</span><span class="p">(</span><span class="n">intervals</span><span class="p">)</span>
</code></pre></div></div>

<p><strong>Results:</strong></p>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Short prompt (~20 tokens)</th>
      <th>Long prompt (~500 tokens)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>TTFT</strong></td>
      <td><strong>341ms</strong></td>
      <td><strong>487ms</strong> (+42%)</td>
    </tr>
    <tr>
      <td><strong>TPOT</strong></td>
      <td><strong>3.4ms</strong></td>
      <td><strong>4.2ms</strong> (barely changed)</td>
    </tr>
    <tr>
      <td>Throughput</td>
      <td>145.8 tok/s</td>
      <td>110.2 tok/s</td>
    </tr>
  </tbody>
</table>

<p>The asymmetry is the point. TTFT increased 42% when the prompt got 25× longer — more tokens to process in parallel during prefill. But TPOT barely moved (3.4ms → 4.2ms) because decode generates one token at a time regardless of prompt length. Once the model starts generating, the input is already in the KV cache and irrelevant to decode speed.</p>

<blockquote>
  <p>TPOT is determined by model size and hardware bandwidth. TTFT is determined by how long your user made their prompt.</p>
</blockquote>

<hr />

<h2 id="experiment-2-prefix-cache--51-ttft-reduction-for-free">Experiment 2: Prefix Cache — 51% TTFT Reduction for Free</h2>

<p>KV cache stores computed key-value tensors for each token so they don’t need recomputing on subsequent steps. Prefix caching extends this across requests: if two requests share the same system prompt, the second reuses the KV cache blocks from the first.</p>

<p>I tested this with a long shared system prompt (~50 repetitions, creating ~200 tokens of identical prefix):</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">SYSTEM_PROMPT</span> <span class="o">=</span> <span class="s">"You are a helpful assistant. "</span> <span class="o">*</span> <span class="mi">50</span>  <span class="c1"># long shared prefix
</span>
<span class="n">chat</span><span class="p">(</span><span class="s">"What is 2+2?"</span><span class="p">,</span>   <span class="s">"First request (cold cache)"</span><span class="p">)</span>
<span class="n">chat</span><span class="p">(</span><span class="s">"What is 3+3?"</span><span class="p">,</span>   <span class="s">"Second request (warm cache)"</span><span class="p">)</span>
<span class="n">chat</span><span class="p">(</span><span class="s">"What is 4+4?"</span><span class="p">,</span>   <span class="s">"Third request (warmer cache)"</span><span class="p">)</span>
</code></pre></div></div>

<p><strong>Results:</strong></p>

<table>
  <thead>
    <tr>
      <th>Request</th>
      <th>TTFT</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>First (cold cache)</td>
      <td><strong>753ms</strong></td>
      <td>Full prefill — all tokens computed</td>
    </tr>
    <tr>
      <td>Second (warm cache)</td>
      <td><strong>367ms</strong></td>
      <td>51% reduction — prefix blocks reused</td>
    </tr>
    <tr>
      <td>Third (warmer cache)</td>
      <td><strong>364ms</strong></td>
      <td>Marginal further improvement</td>
    </tr>
    <tr>
      <td>Session cache hit ratio</td>
      <td><strong>17.7%</strong></td>
      <td>Across the full test session</td>
    </tr>
  </tbody>
</table>

<p>51% TTFT reduction. Zero model changes. No infrastructure changes. Just sending the same system prompt byte-for-byte across requests.</p>

<p>The operational implication: your production system prompt should be at the front of every request, identical every time. Anything that mutates it per-request — timestamp injection, per-user personalization in the system prompt, A/B testing different prompts — kills the cache hit rate and silently taxes every user’s TTFT.</p>

<p>This is also the per-request proof of what llm-d’s EPP prefix-cache scorer does at cluster scale: route requests to the decode pod that already holds relevant KV cache blocks. What I measured locally as a 51% reduction is what the EPP maximises across dozens of pods.</p>

<hr />

<h2 id="experiment-3-kv-cache-pressure-under-concurrent-load">Experiment 3: KV Cache Pressure Under Concurrent Load</h2>

<p>I fired 4 long concurrent requests simultaneously — each asking for 500 output tokens — to observe how continuous batching handled them:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># kv_pressure.py
</span><span class="k">def</span> <span class="nf">send_long_request</span><span class="p">(</span><span class="n">i</span><span class="p">):</span>
    <span class="n">r</span> <span class="o">=</span> <span class="n">httpx</span><span class="p">.</span><span class="n">post</span><span class="p">(</span><span class="s">"http://localhost:8000/v1/chat/completions"</span><span class="p">,</span>
        <span class="n">json</span><span class="o">=</span><span class="p">{</span><span class="s">"model"</span><span class="p">:</span> <span class="n">MODEL</span><span class="p">,</span>
              <span class="s">"messages"</span><span class="p">:</span> <span class="p">[{</span><span class="s">"role"</span><span class="p">:</span> <span class="s">"user"</span><span class="p">,</span>
                           <span class="s">"content"</span><span class="p">:</span> <span class="sa">f</span><span class="s">"Write a very long essay about distributed systems topic </span><span class="si">{</span><span class="n">i</span><span class="si">}</span><span class="s">. Be extremely verbose and detailed."</span><span class="p">}],</span>
              <span class="s">"max_tokens"</span><span class="p">:</span> <span class="mi">500</span><span class="p">},</span>
        <span class="n">timeout</span><span class="o">=</span><span class="mi">120</span><span class="p">)</span>
    <span class="n">tokens</span> <span class="o">=</span> <span class="n">r</span><span class="p">.</span><span class="n">json</span><span class="p">()[</span><span class="s">"usage"</span><span class="p">][</span><span class="s">"completion_tokens"</span><span class="p">]</span>
    <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">"Request </span><span class="si">{</span><span class="n">i</span><span class="si">}</span><span class="s">: </span><span class="si">{</span><span class="n">tokens</span><span class="si">}</span><span class="s"> tokens in </span><span class="si">{</span><span class="n">elapsed</span><span class="si">:</span><span class="p">.</span><span class="mi">1</span><span class="n">f</span><span class="si">}</span><span class="s">s (</span><span class="si">{</span><span class="n">tokens</span><span class="o">/</span><span class="n">elapsed</span><span class="si">:</span><span class="p">.</span><span class="mi">1</span><span class="n">f</span><span class="si">}</span><span class="s"> tok/s)"</span><span class="p">)</span>

<span class="k">with</span> <span class="n">concurrent</span><span class="p">.</span><span class="n">futures</span><span class="p">.</span><span class="n">ThreadPoolExecutor</span><span class="p">(</span><span class="n">max_workers</span><span class="o">=</span><span class="mi">4</span><span class="p">)</span> <span class="k">as</span> <span class="n">ex</span><span class="p">:</span>
    <span class="n">futures</span> <span class="o">=</span> <span class="p">[</span><span class="n">ex</span><span class="p">.</span><span class="n">submit</span><span class="p">(</span><span class="n">send_long_request</span><span class="p">,</span> <span class="n">i</span><span class="p">)</span> <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">4</span><span class="p">)]</span>
</code></pre></div></div>

<p><strong>Results:</strong></p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Request 0: 500 tokens in 24.9s (20.1 tok/s)
Request 1: 500 tokens in 24.9s (20.1 tok/s)
Request 2: 500 tokens in 24.9s (20.1 tok/s)
Request 3: 500 tokens in 24.9s (20.1 tok/s)
</code></pre></div></div>

<p>All four completed simultaneously — continuous batching working correctly. In a naive sequential server, 4 requests of this size would take roughly 4× the single-request time. Instead, vLLM batched decode steps across all four active requests in a single GPU pass per iteration.</p>

<p>During this test, <code class="language-plaintext highlighter-rouge">vllm:kv_cache_usage_perc</code> climbed to 4% in Grafana and returned to baseline when all requests completed. On a 0.6B model with these short prompts, plenty of headroom. The same pattern on a larger model pushes KV cache toward the 85% danger threshold where evictions begin and latency spikes.</p>

<hr />

<h2 id="experiment-4-locust-mixed-traffic--where-the-m4-hits-its-ceiling">Experiment 4: Locust Mixed Traffic — Where the M4 Hits Its Ceiling</h2>

<p>Real traffic isn’t uniform. I configured Locust to simulate a 3:1 mix of short chatbot-style prompts and long document-summarization prompts:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">InferenceUser</span><span class="p">(</span><span class="n">HttpUser</span><span class="p">):</span>
    <span class="n">wait_time</span> <span class="o">=</span> <span class="n">between</span><span class="p">(</span><span class="mf">0.5</span><span class="p">,</span> <span class="mi">2</span><span class="p">)</span>

    <span class="o">@</span><span class="n">task</span><span class="p">(</span><span class="mi">3</span><span class="p">)</span>
    <span class="k">def</span> <span class="nf">short_request</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>   <span class="c1"># 75% of traffic — "What is 2+2?" etc, max_tokens=50
</span>
    <span class="o">@</span><span class="n">task</span><span class="p">(</span><span class="mi">1</span><span class="p">)</span>
    <span class="k">def</span> <span class="nf">long_request</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>    <span class="c1"># 25% of traffic — "Explain transformer attention...", max_tokens=200
</span></code></pre></div></div>

<p><strong>Results at 5 concurrent users:</strong></p>

<table>
  <thead>
    <tr>
      <th>Task</th>
      <th>avg</th>
      <th>min</th>
      <th>p50</th>
      <th>max</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>short_prompt</td>
      <td>9,471ms</td>
      <td>710ms</td>
      <td><strong>1,900ms</strong></td>
      <td>23,219ms</td>
    </tr>
    <tr>
      <td>long_prompt</td>
      <td>16,830ms</td>
      <td>3,152ms</td>
      <td><strong>31,000ms</strong></td>
      <td>30,508ms</td>
    </tr>
  </tbody>
</table>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/locust-test-2.png" alt="Grafana during Locust mixed traffic — E2E latency p50/p95/p99, queue time, inter-token latency, token generation rate" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Top-left: Token Generation — spike when the Locust test starts, trailing off as the M4 saturates under mixed load.
    Top-right: Request Generation Length heatmap — two clear clusters (short bottom, long top) confirming the 3:1 traffic mix is exercised.
    Middle-left: E2E Request Latency p50/p95/p99 — P99 reaches ~1 minute for long prompts. P50 looks acceptable but hides the long-tail pain.
    Middle-right: Queue Time — spikes to 0.25s during the burst, showing requests queuing before prefill even starts.
    Bottom-left: Inter Token Latency — stays flat at 5–10ms throughout. Decode is not the bottleneck. It is prefill queuing that is killing TTFT.
    Bottom-right: Max Generation Token in Sequence Group — peaks at ~100 tokens, showing the batch composition during the test.
  </figcaption>
</figure>

<p>The long prompt p50 of 31 seconds is not a bug — it’s the fundamental prefill/decode competition at scale. Long prompts trigger expensive prefill operations that block decode steps for all concurrent requests. Short-prompt users feel it as TTFT spikes. Long-prompt users wait in a growing queue.</p>

<p>Notice that Inter Token Latency stays flat throughout. <strong>Once a request gets GPU time for decode, it’s fine. The problem is always getting to the front of the queue.</strong> This is exactly the problem P/D disaggregation solves — dedicate separate GPUs to prefill so long prompts never preempt decode.</p>

<hr />

<h2 id="experiment-5-vllm-vs-ollama--the-head-to-head">Experiment 5: vLLM vs Ollama — The Head-to-Head</h2>

<p>I benchmarked vllm-metal against Ollama using vegeta at a sustained 3 req/s over 30 seconds. The primary comparison is Ollama qwen2.5:0.5b vs vllm-metal Qwen3-0.6B-4bit — same model family, same approximate parameter count, different serving engines. Mistral 7B is included as a reference only.</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/LLM-Latency-Comparison.png" alt="Bar chart — Ollama vs vLLM-metal latency at p50, p90, p95. vLLM 2.15x faster at p50." style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">vLLM-metal vs Ollama at sustained 3 req/s. Same hardware, comparable model sizes. The gap is continuous batching, not raw compute.</figcaption>
</figure>

<table>
  <thead>
    <tr>
      <th>Engine</th>
      <th>Model</th>
      <th>p50</th>
      <th>p95</th>
      <th>Min</th>
      <th>Success</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Ollama</td>
      <td>mistral 7B <em>(reference — 10× larger)</em></td>
      <td>15,979ms</td>
      <td>26,896ms</td>
      <td>5,157ms</td>
      <td>100%</td>
    </tr>
    <tr>
      <td>Ollama</td>
      <td>qwen2.5:0.5b <em>(primary comparison)</em></td>
      <td>14,062ms</td>
      <td>20,012ms</td>
      <td>2,569ms</td>
      <td>100%</td>
    </tr>
    <tr>
      <td>Ollama</td>
      <td>qwen3.5 (large)</td>
      <td>timeout</td>
      <td>timeout</td>
      <td>13,039ms</td>
      <td><strong>2.2%</strong></td>
    </tr>
    <tr>
      <td><strong>vllm-metal</strong></td>
      <td><strong>Qwen3-0.6B-4bit</strong> <em>(primary comparison)</em></td>
      <td><strong>6,543ms</strong></td>
      <td><strong>10,952ms</strong></td>
      <td><strong>974ms</strong></td>
      <td><strong>100%</strong></td>
    </tr>
  </tbody>
</table>

<p><strong>vLLM at p50: 2.15× faster. At p95: 1.83× faster.</strong></p>

<p>The minimum latency of 974ms — sub-second — is the clearest signal: when the server isn’t saturated, continuous batching delivers a first response before Ollama has even started processing. Ollama’s 2,569ms minimum reflects its sequential model — each request waits for the previous one to complete before the GPU is available.</p>

<p>The qwen3.5 failure (2.2% success) is instructive. A larger model at 3 req/s causes Ollama’s queue to back up until clients time out. vllm-metal handles the same rate at 100% success because it batches multiple requests into each GPU forward pass rather than serialising them.</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/locust-test-1.png" alt="Grafana — scheduler state (num running vs num waiting), token throughput, TTFT over 2 minutes, cache utilisation" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Top-left: <code>gpu_cache_usage_perc</code> shows "No data" — this is the wrong metric name for vllm-metal. Use <code>vllm:kv_cache_usage_perc</code> instead.
    Top-right: Token Throughput — spikes to ~80 tok/s during the load test, confirming concurrent batching is active.
    Middle-left: Requests Waiting vs Running — spikes at 14:45 are the concurrent requests being admitted. Queue depth briefly reaches 5 before draining.
    Middle-right: Scheduler State — Num Running peaks at 4–5 simultaneously, all requests making progress at once.
    Bottom-left: TTFT over 2m — climbs during load, recovers as the queue clears. The correlation between queue depth and TTFT is direct.
    Bottom-right: Cache Utilisation — peaks at ~4% during load, returns to baseline after. Plenty of KV cache headroom on a 0.6B model.
  </figcaption>
</figure>

<hr />

<h2 id="experiment-6-the-nginx-k8s-gateway--what-the-proxy-layer-actually-costs">Experiment 6: The nginx K8s Gateway — What the Proxy Layer Actually Costs</h2>

<p>With the kind cluster running and nginx proxying to vllm-metal, I ran inference requests through the full gateway path. I used <code class="language-plaintext highlighter-rouge">max_tokens=20</code> — tiny inference — so the measured latency is mostly proxy traversal overhead:</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>vegeta attack <span class="nt">-rate</span><span class="o">=</span>3/s <span class="nt">-duration</span><span class="o">=</span>15s <span class="se">\</span>
  <span class="nt">-targets</span><span class="o">=</span>&lt;<span class="o">(</span><span class="nb">echo</span> <span class="s2">"POST http://localhost:9000/v1/chat/completions
Content-Type: application/json
@/tmp/vllm_gateway.json"</span><span class="o">)</span> | vegeta report
</code></pre></div></div>

<p><strong>Results (45 requests, 3 req/s, max_tokens=20):</strong></p>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>p50 latency</td>
      <td><strong>232ms</strong></td>
      <td>localhost:9000 → kind → nginx → vllm-metal</td>
    </tr>
    <tr>
      <td>p95 latency</td>
      <td><strong>277ms</strong></td>
      <td> </td>
    </tr>
    <tr>
      <td>Min latency</td>
      <td><strong>163ms</strong></td>
      <td>Mostly proxy traversal + tiny inference</td>
    </tr>
    <tr>
      <td>Success rate</td>
      <td><strong>100%</strong></td>
      <td>45/45 — gateway adds no failures</td>
    </tr>
  </tbody>
</table>

<p>The 163ms minimum reflects proxy traversal cost, not inference time — <code class="language-plaintext highlighter-rouge">max_tokens=20</code> on a 0.6B model generates tokens in tens of milliseconds. The meaningful result is 100% success at sustained rate. The gateway adds overhead but is not a bottleneck and does not drop requests.</p>

<p>In production, Envoy adds single-digit milliseconds — it’s purpose-built for high-throughput proxying. The nginx simulation here adds more, but the structural lesson holds: a gateway layer in front of vLLM does not meaningfully affect inference latency. What matters in llm-d is the EPP’s routing intelligence — prefix cache scoring, queue depth scoring, KV utilisation scoring — not the proxy overhead itself.</p>

<hr />

<h2 id="what-grafana-showed--the-full-picture">What Grafana Showed — The Full Picture</h2>

<p>The dashboard below captures the most informative view — TTFT latency percentiles, the prefill vs decode time split, finish reasons, and prompt length distribution:</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/locust-test-3.png" alt="Grafana full overview — TTFT latency p50/p95/p99, Prefill and Decode Time separated, Finish Reason, Request Prompt Length" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">
    Top-left: Time To First Token Latency — P99 spikes to ~7s under load while P50 stays under 2s. The gap between P50 and P99 is the prefill queue effect.
    Top-right: Request Prompt Length heatmap — two clusters confirm short vs long prompt traffic mix is being exercised correctly.
    Bottom-left: Finish Reason — "length" dominates, meaning requests hit max_tokens as expected. No unexpected aborts or errors.
    Bottom-right (highlighted): Requests Prefill and Decode Time — green is prefill, yellow is decode. Prefill varies with prompt length; decode stays flat. This is the visual proof of the two-phase separation. In a P/D disaggregated deployment, these two lines come from separate pod pools.
  </figcaption>
</figure>

<p>Three takeaways from Grafana that weren’t obvious before running the experiments:</p>

<p><strong>TPOT is a red herring under load.</strong> Inter Token Latency stayed flat throughout every experiment — even when E2E latency climbed to 31 seconds for long prompts. The per-token decode speed is stable. The problem is always pre-decode queuing.</p>

<p><strong>The prefill/decode time split is visible and separable.</strong> Prefill varies with prompt length, decode stays constant. In a disaggregated setup each line would come from a different pool of pods, independently scalable.</p>

<p><strong>KV cache utilisation is your early warning system.</strong> Peak of 4% during these experiments — plenty of headroom for a 0.6B model. On a larger model or busier system, the moment this crosses 85% is your fire alarm.</p>

<hr />

<h2 id="the-connection-to-week-2">The Connection to Week 2</h2>

<p>Everything measured this week points to the same structural problem: in aggregated serving, prefill and decode compete for the same resources. Long prompts delay short ones. High-concurrency workloads cause cascading TTFT degradation that no amount of hardware scaling can fully fix — because the problem is architectural, not computational.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>── AGGREGATED SERVING (what Week 1 showed) ──────────────────────────

Request A (long prompt)  → [  prefill 487ms  ][  decode decode decode ...  ]
Request B (short prompt) → [WAITING...       ][  prefill 341ms  ][ decode  ]
Request C (short prompt) → [WAITING.....................][prefill ][ decode  ]

── P/D DISAGGREGATION (what Week 2 will fix) ────────────────────────

Prefill pool: [ A-prefill ][ B-prefill ][ C-prefill ]  ← compute-bound
Decode pool:  [ A-decode  ][ B-decode  ][ C-decode  ]  ← memory-bandwidth-bound

Decode pool never blocks on prefill. TTFT stays consistent under load.
</code></pre></div></div>

<p>The numbers from this week — TTFT 341ms vs 487ms, prefix cache 51% reduction, 31-second long-prompt p50 under load — are the baseline. Week 2 is the comparison.</p>

<hr />

<h2 id="the-complete-benchmark-reference">The Complete Benchmark Reference</h2>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Hardware: M4 Mac Mini, 16GB unified memory
Model:    mlx-community/Qwen3-0.6B-4bit
Engine:   vllm-metal 0.13.0

─── Single request baseline ──────────────────────────────
  TTFT (short prompt, ~20 tokens):  341ms
  TTFT (long prompt, ~500 tokens):  487ms  (+42%)
  TPOT (short):                     3.4ms  (≈ 294 tok/s)
  TPOT (long):                      4.2ms  (barely changed)
  Throughput (single request):      145.8 tok/s

─── Prefix cache ─────────────────────────────────────────
  Cold TTFT (first request):        753ms
  Warm TTFT (same prefix):          367ms  (51% reduction)
  Session cache hit ratio:          17.7%

─── KV pressure (4 concurrent × 500 tokens) ─────────────
  Wall time (all 4 concurrent):     24.9s
  Per-request throughput:           20.1 tok/s
  Result: continuous batching confirmed

─── Mixed load (5 users, 3:1 short/long via Locust) ─────
  short_prompt: avg=9,471ms  min=710ms  p50=1,900ms  max=23,219ms
  long_prompt:  avg=16,830ms min=3,152ms p50=31,000ms max=30,508ms

─── Ollama vs vLLM (3 req/s, 30s, vegeta) ───────────────
  Ollama / mistral 7B p50:         15,979ms  (reference — 10× larger)
  Ollama / qwen2.5:0.5b p50:       14,062ms  (primary comparison)
  Ollama / qwen3.5 (large):        timeout   (2.2% success)
  vLLM  / Qwen3-0.6B-4bit p50:     6,543ms
  vLLM advantage at p50:            2.15× faster
  vLLM advantage at p95:            1.83× faster

─── nginx K8s gateway (max_tokens=20, 45 requests) ──────
  p50:  232ms  |  p95: 277ms  |  min: 163ms  |  Success: 100%
  Note: mostly proxy overhead — max_tokens=20 is tiny inference
</code></pre></div></div>

<hr />

<h2 id="what-this-points-to">What This Points To</h2>

<p>The Mac Mini experiments answered the questions they were designed for. TTFT/TPOT/KV cache behave exactly as the theory predicts. Continuous batching is real and measurable. The gateway layer adds overhead but doesn’t drop requests. And Ollama’s lack of continuous batching is not a footnote — it’s the difference between a useful serving system and one that falls over at 3 requests per second with a moderately sized model.</p>

<p>What the Mac Mini can’t answer: what happens when you separate prefill and decode onto dedicated hardware? What does EPP prefix-cache-aware routing look like in practice? And eventually — how do TGI, TensorRT-LLM, and SGLang compare under the same load test conditions? Those experiments need cloud GPU budget earmarked for specific Week 2 and Week 3 labs. When they happen, they’ll get their own posts with real numbers.</p>

<hr />

<p><strong>Next up:</strong> Post 3 covers llm-d deployment on a Lambda Labs GH200 — the ten things nobody tells you before you try to run a Helm-based inference scheduler on K3s, including the NIXL/RDMA failure that explains why single-GPU P/D disaggregation doesn’t work the way you’d hope.</p>

<hr />

<p><em>All experiments run on M4 Mac Mini 16GB, vllm-metal 0.13.0, Qwen3-0.6B-4bit. Scripts will be made available soon via github repository. I’m an platform engineer with 11+ years in distributed systems currently going deep on LLM serving. I write what I actually measured, including the parts that hit walls.</em></p>

<p><em><a href="https://github.com/kraghavan">GitHub</a> · <a href="https://linkedin.com/in/karthikaraghavan">LinkedIn</a></em></p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm-infrastructure" /><category term="inference" /><category term="vllm" /><category term="ollama" /><category term="apple-silicon" /><category term="m4" /><category term="prometheus" /><category term="grafana" /><category term="nginx" /><category term="kubernetes" /><category term="benchmarks" /><category term="sre" /><summary type="html"><![CDATA[I treated an M4 Mac Mini as a production-like inference environment — wired up Prometheus, Grafana, a kind cluster with nginx, and ran real load tests. Here's what the numbers actually showed.]]></summary></entry><entry><title type="html">What Is LLM Inference, Really? A Deep Technical Walkthrough</title><link href="https://kraghavan.ca/llm-infrastructure/inference/2026/04/14/re-introduction-to-inference.html" rel="alternate" type="text/html" title="What Is LLM Inference, Really? A Deep Technical Walkthrough" /><published>2026-04-14T00:00:00+00:00</published><updated>2026-04-14T00:00:00+00:00</updated><id>https://kraghavan.ca/llm-infrastructure/inference/2026/04/14/re-introduction-to-inference</id><content type="html" xml:base="https://kraghavan.ca/llm-infrastructure/inference/2026/04/14/re-introduction-to-inference.html"><![CDATA[<p>Let me be honest with you. When I started working on LLM infrastructure, I had eleven years of distributed systems experience. I knew Kafka, Kubernetes, Prometheus. I could debug a partition rebalance in my sleep.</p>

<p>And yet the first time someone asked me <em>what actually happens during inference</em>, I said something like “the model reads the prompt and generates tokens.” Which is technically true the same way “a database reads your query and returns rows” is technically true — accurate, useless, and deeply embarrassing for someone drawing a principal engineer’s salary.</p>

<p>This post is what I wish I’d had on day one. We’re going to walk through the entire inference pipeline — from the moment your request arrives to the moment you see text on screen — with real examples, honest explanations of where the performance goes, and enough detail that you can actually reason about production problems.</p>

<p>No “and then the transformer does its thing.” No skipped steps. Strap in.</p>

<hr />

<figure style="max-width:480px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/gemini-generated-llm-inference-pipeline.png" alt="LLM Inference Pipeline" style="width:100%;" />
</figure>

<hr />

<h2 id="1-what-is-inference">1. What Is Inference?</h2>

<p><strong>Training</strong> is where you take a massive dataset, run it through a model millions of times, and slowly adjust billions of numerical weights until the model gets good at predicting the next word. Training is done once (or occasionally). It costs millions of dollars in GPU-hours and requires a team of researchers.</p>

<p><strong>Inference</strong> is what happens afterward, every time someone uses the model. It’s the model <em>using</em> those learned weights to respond to new input. No weights change. No learning happens. It’s pure forward-pass computation.</p>

<p>Think of it like this: training is baking the bread. Inference is slicing it and serving it to customers. The bread (weights) is done. The kitchen (inference engine) just has to plate it fast enough that the queue doesn’t back up to the street.</p>

<p>The inference engine is the runtime that takes the frozen model weights and executes them against an input. The same weights can run on Ollama, vLLM, TensorRT-LLM, or TGI — and get meaningfully different performance from each. The weights don’t change. The execution strategy does.</p>

<p>This distinction matters operationally: <strong>inference is not a solved problem</strong>. Serving a model efficiently at scale is a full engineering discipline.</p>

<hr />

<h2 id="2-the-artifact-whats-actually-in-that-10gb-download">2. The Artifact: What’s Actually in That 10GB Download?</h2>

<p>When you run <code class="language-plaintext highlighter-rouge">ollama pull mistral</code> or grab a model from HuggingFace, you aren’t just downloading a “program.” You’re downloading a massive, frozen brain in a box. If you’ve ever wondered why a model that “just chats” takes up 10GB of your SSD, it’s because it is packed with billions of tiny numerical “preferences” the model learned during its training phase.</p>

<p>Think of the <strong>GGUF</strong> (or <strong>Safetensors</strong>) file as a giant Ikea flat-pack box. To build the working model, you need two things: the <strong>Instruction Manual</strong> and the <strong>Hardware</strong>.</p>

<p>What’s inside a 7B parameter model file:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>GGUF file structure (simplified):
├── Header
│   ├── Model architecture (LlamaForCausalLM)
│   ├── Vocabulary (32000 tokens + their embeddings)
│   ├── Context length (4096, 8192, etc.)
│   └── Hyperparameters (n_layers, n_heads, etc.)
│
└── Weight tensors:
    ├── token_embeddings        [32000 × 4096]   ← the embedding matrix
    ├── layer.0.attention.q     [4096 × 4096]    ← Query projection weights
    ├── layer.0.attention.k     [4096 × 4096]    ← Key projection weights
    ├── layer.0.attention.v     [4096 × 4096]    ← Value projection weights
    ├── layer.0.attention.out   [4096 × 4096]    ← Output projection
    ├── layer.0.ffn.up          [4096 × 11008]   ← Feed-forward up
    ├── layer.0.ffn.down        [11008 × 4096]   ← Feed-forward down
    ├── ... × 32 layers
    └── output_norm + lm_head   [32000 × 4096]   ← Final projection to logits
</code></pre></div></div>

<h3 id="the-manual-the-header">The “Manual” (The Header)</h3>
<p>This is the first few kilobytes of the file. It tells the inference engine (like Ollama or vLLM) how to put the brain together. It includes:</p>
<ul>
  <li><strong>The Architecture</strong>: Identifies the model type (e.g., <code class="language-plaintext highlighter-rouge">LlamaForCausalLM</code>) so the engine knows which math rules to apply.</li>
  <li><strong>The Vocabulary</strong>: A dictionary of roughly 32,000 to 128,000 “tokens” (the syllables the model speaks).</li>
  <li><strong>The Hyperparameters</strong>: Crucial settings like the number of layers (32 or 80) and the context length (how much it can remember).</li>
</ul>

<h3 id="the-hardware-the-tensors">The “Hardware” (The Tensors)</h3>
<p>The rest of that file is just rows and rows of numbers called <strong>Weights</strong>. Every inference request is essentially looking up values from these matrices and multiplying them together—32 times over.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">The “Part”</th>
      <th style="text-align: left">What it actually does in plain English</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong><code class="language-plaintext highlighter-rouge">token_embeddings</code></strong></td>
      <td style="text-align: left"><strong>The Translator.</strong> Turns human text into the model’s internal number-language.</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong><code class="language-plaintext highlighter-rouge">attention.q, k, v</code></strong></td>
      <td style="text-align: left"><strong>The Highlighters.</strong> Helps the model decide which part of your sentence is important.</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong><code class="language-plaintext highlighter-rouge">ffn.up</code> &amp; <code class="language-plaintext highlighter-rouge">ffn.down</code></strong></td>
      <td style="text-align: left"><strong>The Reasoning Muscles.</strong> Does the heavy lifting of processing and transforming information.</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong><code class="language-plaintext highlighter-rouge">lm_head</code></strong></td>
      <td style="text-align: left"><strong>The Microphone.</strong> Turns the final internal math back into a word you can read.</td>
    </tr>
  </tbody>
</table>

<h3 id="quantization-shrinking-the-brain">Quantization: Shrinking the Brain</h3>
<p>You might notice some files are 15GB while others are 4GB for the same model. This is <strong>Quantization</strong>—the art of compression. We turn high-precision 16-bit floats into lower-precision integers (like 4-bit).</p>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Precision</th>
      <th style="text-align: left">Bits per weight</th>
      <th style="text-align: left">7B Model Size</th>
      <th style="text-align: left">The SRE Reality</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>FP16</strong></td>
      <td style="text-align: left">16</td>
      <td style="text-align: left">~14GB</td>
      <td style="text-align: left">Requires an A100. Pristine quality.</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>INT8</strong></td>
      <td style="text-align: left">8</td>
      <td style="text-align: left">~7GB</td>
      <td style="text-align: left">Fits on a high-end gaming GPU. Minimal loss.</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>INT4 (Q4_K_M)</strong></td>
      <td style="text-align: left">4</td>
      <td style="text-align: left">~4GB</td>
      <td style="text-align: left"><strong>The Sweet Spot.</strong> Fits on a MacBook. Faster throughput.</td>
    </tr>
  </tbody>
</table>

<p><strong>Why SREs love INT4:</strong> Lower precision = smaller tensors = faster memory transfers. Because decoding is memory-bound, an INT4 model often delivers <strong>20-40% better TPOT</strong> (tokens per second) than the “full” version because the memory bus isn’t screaming as loud.</p>

<p><strong>The takeaway:</strong> You aren’t executing code; you are loading a massive, math-heavy lookup table. GGUF is your single-file “box,” and quantization is how you fit that box into a smaller truck (your GPU).</p>

<hr />

<h2 id="3-the-three-phases-a-map-before-the-territory">3. The Three Phases: A Map Before the Territory</h2>

<p>Every inference request goes through three broad phases. They are not equally expensive, not equally parallelizable, and not equally friendly to your p99 latency.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>┌──────────────────────────────────────────────────────────────────┐
│  TOKENIZATION  │  Prefill (Prompt Processing)   │ Decode         │
│    (CPU)       │           (GPU, compute)       │ Loop(GPU, Mem) │
│                │                                │                │
│                │                                │ current →      │
│  Text → IDs    │  Embed → Position → Attention  │ next token     │
└──────────────────────────────────────────────────────────────────┘
     Fast          Scales with prompt length        Slow
</code></pre></div></div>

<ul>
  <li><strong>Tokenization</strong>: Split the text into token IDs the model understands. CPU-bound. Fast.</li>
  <li><strong>Prefill</strong>: Process the entire prompt through the model. GPU compute-bound. Scales with prompt length.</li>
  <li><strong>Decode</strong>: Generate output tokens one at a time. GPU memory-bound. Runs in a loop until done.</li>
</ul>

<p>Each phase has its own bottleneck. Let’s go through them one by one.</p>

<hr />

<h2 id="4-tokenization-chopping-text-into-numbers">4. Tokenization: Chopping Text Into Numbers</h2>

<p>Before a single GPU operation happens, your text has to be converted into a format the model can work with: a sequence of integers called token IDs.</p>

<p>A token is not a character, and it’s not a word. It’s a chunk of text that appears frequently enough in the training corpus to deserve its own ID. There are several ways to build this vocabulary — WordPiece (used by BERT), Unigram (used by SentencePiece), and others — but the dominant approach in modern LLMs is Byte Pair Encoding (BPE): a compression algorithm that iteratively merges the most common pairs of characters or subwords into single tokens until it reaches a target vocabulary size.</p>

<p>The result is a vocabulary of roughly 32,000–128,000 tokens, each with a corresponding integer ID. The model never sees your text — it sees a list of numbers.</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/encoding-bpe.png" alt="Tokenization with BPE" style="width:100%;" />
</figure>

<p>Take our example prompt: <code class="language-plaintext highlighter-rouge">"The cat sat"</code></p>

<p>After tokenization, this becomes something like:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>"The"  → 1026
" cat" → 5992
" sat" → 3290
</code></pre></div></div>
<p>Token IDs: <code class="language-plaintext highlighter-rouge">[1026, 5992, 3290]</code></p>

<p>Note the space before “cat” and “sat” — it’s part of the token. Tokenizers care about whitespace because it affects meaning and frequency.</p>

<h3 id="is-tokenization-cpu-bound">Is Tokenization CPU-Bound?</h3>

<p>Yes. The tokenizer is usually written in Rust (HuggingFace’s <code class="language-plaintext highlighter-rouge">tokenizers</code> crate) or C++ for exactly this reason. For most requests it’s fast enough to be invisible — microseconds for a short prompt.</p>

<p>Where it bites you: <strong>very long documents</strong> fed to batch processing jobs. A 100,000-token context requires processing 100,000 token lookups. It’s still fast relative to GPU work, but it’s the one step in the pipeline running on CPU that you can’t just throw more GPU at.</p>

<p><strong>How it’s improved:</strong> Parallelizing tokenization across CPU cores for batch workloads. Or — and this is the real fix — <strong>not re-tokenizing the same content repeatedly</strong>. If you have a shared system prompt you send to every request, tokenizing it once and caching the result is free latency.</p>

<hr />

<h2 id="5-prefill-the-model-reads-your-prompt">5. Prefill: The Model Reads Your Prompt</h2>

<p>Now we have token IDs. The model needs to turn those IDs into something it can reason about. This is <strong>prefill</strong> — the model processing the entire prompt in one shot.</p>

<p>Prefill has two sub-steps that are easy to conflate: <strong>embedding lookup</strong> and the actual <strong>transformer forward pass</strong>. Let’s take them in order.</p>

<h3 id="the-embedding-matrix">The Embedding Matrix</h3>

<p>Every token ID maps to a high-dimensional vector of floating-point numbers called an <strong>embedding</strong>. These vectors live in the model’s embedding matrix — a giant lookup table with one row per vocabulary token and one column per embedding dimension.</p>

<p>For a model with a 32,000-token vocabulary and 4,096 embedding dimensions, this matrix has shape <code class="language-plaintext highlighter-rouge">[32000, 4096]</code>. At 16-bit float precision, that’s about 256MB just for the embedding layer.</p>

<p>Our example <code class="language-plaintext highlighter-rouge">[1026, 5992, 3290]</code> becomes:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Token ID 1026 → embedding row 1026 → [0.12, -0.43, 0.81, ..., 0.07]  (4096 values)
Token ID 5992 → embedding row 5992 → [-0.34, 0.91, 0.12, ..., -0.22] (4096 values)
Token ID 3290 → embedding row 3290 → [0.67, 0.05, -0.88, ..., 0.44]  (4096 values)
</code></pre></div></div>

<p>I’m simplifying to 8 dimensions here so this fits on a page. In reality it’s 4,096 or 8,192 dimensions depending on the model.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Simplified (3D instead of 4096D), just to show the shape:

"The"  → [0.12, -0.43,  0.81]
" cat" → [-0.34,  0.91,  0.12]
" sat" → [0.67,  0.05, -0.88]

Shape: [3 tokens × 3 dims] = a matrix of floats
</code></pre></div></div>

<p>These vectors aren’t random. They’re the result of training — the model has learned that “cat” and “dog” live close together in this space, and “cat” and “quantum mechanics” are far apart. The geometry encodes semantic meaning.</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/embedding-lookup-process.png" alt="Embedding Lookup Process" style="width:100%;" />
</figure>

<h3 id="how-do-the-model-weights-help-here">How Do the Model Weights Help Here?</h3>

<p>The embedding matrix IS the model weights, specifically. The 10GB (or 40GB, or 70GB) file you download — the GGUF or safetensors file — contains all the weight matrices the model learned during training. The embedding lookup is literally indexing into one of those weight matrices by row number.</p>

<p>When you run inference, you’re not computing anything creative. You’re doing matrix math against frozen numbers that were tuned over millions of training iterations.</p>

<hr />

<h2 id="6-positional-embeddings-teaching-the-model-about-order">6. Positional Embeddings: Teaching the Model About Order</h2>

<p>Here’s a problem: the embedding lookup is a table lookup. It doesn’t care that “cat” is token 2 and “sat” is token 3. Two requests with the same tokens in different orders would produce identical embeddings.</p>

<p>But order matters enormously. “The cat sat on the dog” and “The dog sat on the cat” have the same tokens and very different meanings.</p>

<p><strong>Positional embeddings</strong> solve this by adding a position-aware vector to each token’s embedding. The model learns that “token at position 1” feels different from “token at position 5,” even if the token ID is the same.</p>

<h3 id="how-is-it-calculated">How Is It Calculated?</h3>

<p>There are two main approaches:</p>

<p><strong>Sinusoidal (original Transformers paper):</strong> Compute a fixed sine/cosine wave pattern based on position and dimension index. Deterministic, no learned parameters.</p>

<p><strong>RoPE (Rotary Position Embedding):</strong> Used by Llama, Qwen, Mistral, and most modern models. Instead of adding a vector, it <em>rotates</em> the query and key vectors by an angle proportional to position. The result: the dot product between two token representations naturally captures their relative distance. Elegant, and generalizes better to longer contexts than the training data.</p>

<p>Continuing our example. After adding positional information:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>"The"  at position 0: [0.12, -0.43, 0.81] + pos(0) → [0.15, -0.40, 0.84]
" cat" at position 1: [-0.34, 0.91, 0.12] + pos(1) → [-0.31, 0.88, 0.09]
" sat" at position 2: [0.67, 0.05, -0.88] + pos(2) → [0.65, 0.03, -0.86]
</code></pre></div></div>

<p>The position vectors are small adjustments. Their real value is that when attention is computed later, the model can tell whether two tokens are adjacent or 200 positions apart.</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/positional-embeddings-diagram.png" alt="Positional Embeddings Diagram" style="width:100%;" />
</figure>

<h3 id="cpu-bottleneck-in-prefill">CPU Bottleneck in Prefill?</h3>

<p>Embedding lookup and positional encoding are fast operations. The real CPU bottleneck in prefill is less about these steps and more about <strong>data movement</strong>: loading the right weight tensors from CPU RAM to GPU VRAM before the transformer forward pass can begin.</p>

<p>For very large models that don’t fully fit in VRAM, the CPU-GPU transfer becomes the bottleneck — you’re constantly paging weight blocks in. This is why model quantization matters: a 4-bit quantized model uses less VRAM, fits entirely on GPU, and eliminates this transfer overhead. More on that in a moment.</p>

<hr />

<h2 id="7-the-transformer-layers-where-the-real-work-happens">7. The Transformer Layers: Where the Real Work Happens</h2>

<p>After embedding + positional encoding, we have a matrix of shape <code class="language-plaintext highlighter-rouge">[sequence_length × embedding_dim]</code>. This matrix now passes through N transformer layers — 32 layers for Llama-3.2-3B, 80 layers for Llama-3.1-70B.</p>

<p>Each layer applies:</p>
<ol>
  <li><strong>Self-attention</strong>: every token looks at every other token and decides what’s relevant</li>
  <li><strong>Feed-forward network (FFN)</strong>: each token’s representation is independently transformed</li>
</ol>

<p>This is where the model’s “reasoning” happens — and where most of the GPU compute goes during prefill. All tokens are processed in parallel within a layer, making prefill compute-bound. More tokens = more compute = higher TTFT.</p>

<p>We’ll cover the attention mechanism in detail in section 9. First, let’s see what comes out.</p>

<hr />

<h2 id="8-decoding-one-token-at-a-time-forever">8. Decoding: One Token at a Time, Forever</h2>

<p>After prefill, the model produces its first output token. Then it produces another. Then another. Each token depends on all previous tokens. This is the <strong>decode loop</strong>.</p>

<p>Here’s what makes decode fundamentally different from prefill: <strong>you can’t parallelize it</strong>. Token N can’t be computed until token N-1 exists. It’s inherently sequential.</p>

<p>Let’s walk through two steps with our example. Our prompt was “The cat sat” and let’s say the model is going to output “on the mat.”</p>

<h3 id="decode-step-1-predicting-on">Decode Step 1: Predicting “on”</h3>

<p>After prefill, we have KV cache entries for “The”, “ cat”, “ sat” (we’ll explain KV cache shortly). Now:</p>

<ol>
  <li>The model takes the last token’s representation (“ sat”) and runs it through the transformer layers</li>
  <li>At each layer, attention is computed between “ sat” and all previous tokens via the KV cache</li>
  <li>The final layer outputs a vector of size <code class="language-plaintext highlighter-rouge">[vocabulary_size]</code> — one score per possible next token. This is called the <strong>logits</strong> vector.</li>
  <li>The logits are converted to probabilities via softmax</li>
  <li>A token is sampled from this distribution (more below)</li>
  <li>Result: token ID for “ on” → <code class="language-plaintext highlighter-rouge">" on"</code> is emitted as the first output token</li>
</ol>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>KV cache: ["The", " cat", " sat"]
Current:  " sat" (last input token)
Attention: " sat" attends to "The", " cat", " sat"
Output logits: [0.001, 0.003, ..., 0.45 (" on"), ..., 0.002]
Sample: " on" ✓
</code></pre></div></div>

<h3 id="decode-step-2-predicting-the">Decode Step 2: Predicting “the”</h3>

<p>Now “ on” has been generated. We add it to context:</p>

<ol>
  <li>Embed token “ on” → one new embedding vector (just <em>one</em> token, not the whole sequence)</li>
  <li>Add positional embedding for position 4</li>
  <li>Run through transformer layers, attending to KV cache for [“The”, “ cat”, “ sat”, “ on”]</li>
  <li>Output logits → sample → “ the”</li>
</ol>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>KV cache: ["The", " cat", " sat", " on"]  ← one entry added
Current:  " on" (new last token)
Attention: " on" attends to all four previous tokens
Output logits: [..., 0.67 (" the"), ...]
Sample: " the" ✓
</code></pre></div></div>

<p>And so it continues: “ mat” → “.” → <code class="language-plaintext highlighter-rouge">&lt;end&gt;</code> token → stop.</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/key-value-cache-growth.png" alt="Key Value Cache Growth" style="width:100%;" />
</figure>

<h3 id="the-sampling-step-where-creativity-lives">The Sampling Step (Where Creativity Lives)</h3>

<p>The logits give you a probability distribution. How you sample from it is where temperature, top-k, and top-p come in:</p>

<ul>
  <li><strong>Greedy (temperature=0)</strong>: always pick the highest probability token. Deterministic. Boring for creative tasks, good for code.</li>
  <li><strong>Temperature &gt; 1</strong>: flatten the distribution. More randomness, more surprising outputs, more hallucinations.</li>
  <li><strong>Temperature &lt; 1</strong>: sharpen the distribution. More conservative, more predictable.</li>
  <li><strong>Top-k</strong>: only sample from the top K most probable tokens. Ignores the long tail.</li>
  <li><strong>Top-p (nucleus sampling)</strong>: only sample from the smallest set of tokens whose cumulative probability exceeds p. Adaptive — sometimes that’s 2 tokens, sometimes 50.</li>
</ul>

<p>This step is trivially cheap computationally but has enormous impact on output quality. As an SRE, you don’t usually tune this — but you will get bug reports when someone’s temperature=2.0 config makes the model output Shakespeare from a JSON API endpoint.</p>

<hr />

<h2 id="9-why-memory-is-the-decode-bottleneck">9. Why Memory Is the Decode Bottleneck</h2>

<p>Here’s the thing about decode that makes it hard to optimize: on every single decode step, the model needs to run attention against <strong>all previous tokens</strong>. Not a summary of them. All of them. Via the KV cache.</p>

<p>For a 1000-token conversation, every decode step reads 1000 rows of KV tensors from GPU memory. For a 32-layer model, that’s 32 reads of a large tensor. For a 7B model, the KV entry for a single token at a single layer is tens of kilobytes.</p>

<p>The GPU’s compute cores can execute these operations fast. But they’re waiting on HBM (High Bandwidth Memory) to deliver the data. The memory bus saturates before the compute does.</p>

<p><strong>The GPU is memory-bound during decode, not compute-bound.</strong></p>

<p>This is why adding more CUDA cores doesn’t help decode performance as much as adding more memory bandwidth. It’s why H100s are faster than A100s for serving despite similar compute specs — the memory bandwidth jump matters more for decode than the FLOP count.</p>

<p>A rough intuition: during prefill, GPU utilization is high and memory is barely stressed. During decode, GPU compute is mostly idle and the memory bus is screaming.</p>

<hr />

<h2 id="10-kv-cache-the-most-important-data-structure-in-inference">10. KV Cache: The Most Important Data Structure in Inference</h2>

<p>We keep mentioning the KV cache. Let’s make it concrete.</p>

<p>During the attention step in each transformer layer, every token produces two vectors: a <strong>Key</strong> (K) and a <strong>Value</strong> (V). These are used in attention computation: other tokens use your Key to decide how much to attend to you, and then use your Value to extract information from you.</p>

<p>During decode, token N needs to compute attention against tokens 1 through N-1. If we recomputed K and V for all previous tokens on every step, we’d be doing O(N²) work per decode step. That’s catastrophic.</p>

<p>The KV cache solves this: after computing K and V for a token, we <strong>store</strong> them. On the next decode step, we only compute K and V for the new token and look up the rest from cache.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>After prefill of "The cat sat":
KV cache = {
  layer_0: { K: [k_The, k_cat, k_sat], V: [v_The, v_cat, v_sat] }
  layer_1: { K: [...], V: [...] }
  ...  (32 layers total)
}

After generating " on":
KV cache = {
  layer_0: { K: [k_The, k_cat, k_sat, k_on], V: [v_The, v_cat, v_sat, v_on] }
  ...
}
← one new entry appended per layer per decode step
</code></pre></div></div>

<p>The cache grows with every token generated. When the KV cache fills GPU memory:</p>
<ul>
  <li>New requests queue (they have nowhere to store their KV tensors)</li>
  <li>Long requests get partially evicted and have to recompute (latency spike)</li>
  <li>In the worst case: OOM crash</li>
</ul>

<p>KV cache occupancy is the single most important resource to monitor in a serving system. It determines how many concurrent requests you can serve and how long those requests can be. When <code class="language-plaintext highlighter-rouge">vllm:kv_cache_usage_perc</code> starts approaching 0.9, you’re about to have a bad time.</p>

<h3 id="prefix-caching-free-speedups">Prefix Caching: Free Speedups</h3>

<p>If two requests share the same system prompt, their KV cache entries for that prefix are identical. Prefix caching stores those entries once and reuses them.</p>

<p>In practice on my M4 Mac Mini:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Without prefix cache (cold):  TTFT 753ms
With prefix cache (warm):     TTFT 367ms
Savings:                       51% reduction in TTFT
Zero model changes required.
</code></pre></div></div>

<p>This is why your production system prompt should be at the beginning of every request, and why it should be identical byte-for-byte across requests. Drift in the system prompt = cache misses = higher TTFT = sad users.</p>

<hr />

<h2 id="11-attention-the-mechanism-that-makes-it-work">11. Attention: The Mechanism That Makes It Work</h2>

<p>Let’s go one level deeper into what happens at each transformer layer. Attention is the core operation. Everything else is bookkeeping.</p>

<h3 id="self-attention-in-plain-english">Self-Attention in Plain English</h3>

<p>For each token, attention computes: <em>“which other tokens should I be paying attention to, and by how much?”</em></p>

<p>It does this via three learned projections of each token’s embedding:</p>
<ul>
  <li><strong>Query (Q)</strong>: “what am I looking for?”</li>
  <li><strong>Key (K)</strong>: “what do I offer?”</li>
  <li><strong>Value (V)</strong>: “what information do I contain?”</li>
</ul>

<p>For each token, you compute its dot product with every other token’s Key. High dot product = high attention score = attend more to that token. The scores are normalized via softmax, then used to weight-sum all the Value vectors.</p>

<p>Example with “The cat sat”:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Token: " sat"
Q_sat · K_The  = 0.8  → attend heavily to "The"
Q_sat · K_cat  = 0.9  → attend most to " cat" (makes sense)
Q_sat · K_sat  = 0.3  → attend a little to itself

Attention weights after softmax: [0.35, 0.55, 0.10]

Output = 0.35 × V_The + 0.55 × V_cat + 0.10 × V_sat
</code></pre></div></div>

<p>The output for “ sat” is now a blend of information from all tokens, weighted by relevance. After 32 such layers, the model has a rich, contextualized representation of every token in the sequence.</p>

<figure style="max-width:720px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/attention-mechanism.png" alt="Attention Mechanism" style="width:100%;" />
</figure>

<h3 id="paged-attention-virtual-memory-for-kv-cache">Paged Attention: Virtual Memory for KV Cache</h3>

<p>Standard attention assumes the KV cache is one contiguous block of memory per request. This is wasteful: you have to pre-allocate the maximum possible sequence length upfront, and if the request ends early, that memory is wasted until the request completes.</p>

<p><strong>PagedAttention</strong> (the key innovation in vLLM) borrows from OS virtual memory. Instead of one contiguous block, KV cache is stored in <strong>fixed-size pages</strong> (blocks) that can be non-contiguous in physical GPU memory. A page table maps logical token positions to physical blocks.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Without PagedAttention:
  Request A: [KKKKKKKKKK........] ← pre-allocated 20 slots, using 10, wasting 10
  Request B: [KKKKKK............] ← pre-allocated 20 slots, using 6, wasting 14

With PagedAttention:
  Block pool: [B1][B2][B3][B4][B5][B6][B7][B8]...
  Request A:  blocks B1, B3, B7 (non-contiguous, allocated on demand)
  Request B:  blocks B2, B4    (uses only what it needs)
</code></pre></div></div>

<p>The result: <strong>much higher memory utilization</strong>, more concurrent requests, less waste. Prefix cache blocks can be shared between requests with identical prefixes — only one copy of the system prompt’s KV entries needed, regardless of how many requests use it.</p>

<p>PagedAttention is why vLLM typically serves 2-4x more concurrent requests than a naive implementation on the same hardware.</p>

<hr />

<h2 id="12-continuous-batching-the-throughput-unlock">12. Continuous Batching: The Throughput Unlock</h2>

<p>Early inference servers were naive: accept a batch of requests, run them all through the model together, return all responses. Simple.</p>

<p>The problem: requests finish at different times. Short requests had to wait for long requests to complete before the next batch could start. GPU utilization looked like a sawtooth wave.</p>

<p><strong>Continuous batching</strong> (also called iteration-level scheduling) fixes this. Instead of batching at the request level, the inference engine batches at the <strong>decode step</strong> level. Every iteration, it assembles the currently active tokens — some mid-generation, some just starting — into a single GPU operation.</p>

<p>When a request finishes, its slot is immediately available for a new request. When a new request arrives, it joins the active batch at the next iteration rather than waiting for the next batch boundary.</p>

<p>The result: GPU utilization stays high, latency for new requests is low, and throughput scales with the number of concurrent requests the KV cache can support — not with some fixed batch size parameter you tuned last Tuesday.</p>

<p>vLLM, TGI, and TensorRT-LLM all implement continuous batching. Ollama does not (as of early 2025). This is one of the primary reasons vLLM serves at 2x the throughput of Ollama under concurrent load.</p>

<hr />

<h2 id="13-the-metrics-that-matter">13. The Metrics That Matter</h2>

<p>Now that you know what’s happening, the metrics become obvious rather than mysterious.</p>

<figure style="max-width:900px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/grafana-metrics.png" alt="Grafana Metrics Dashboard" style="width:100%;" />
  <figcaption style="font-size:0.85rem;color:#888;margin-top:0.5rem;">Real metrics from a running llm-d deployment: TTFT p50 at 15ms, ITL p50 at 5ms, KV cache prefix hit rate at 80.6% — exactly the four numbers you should have on your wall during an incident.</figcaption>
</figure>

<h3 id="ttft--time-to-first-token">TTFT — Time to First Token</h3>

<p><strong>Definition:</strong> Wall clock time from request submission to first output token.</p>

<p><strong>What it captures:</strong> Prefill time + queuing time. If your GPU is busy, TTFT absorbs the wait.</p>

<p><strong>PromQL:</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>histogram_quantile(0.95,
  sum(rate(vllm:time_to_first_token_seconds_bucket[2m])) by (le)
)
</code></pre></div></div>

<p><strong>SLO guidance:</strong> &lt; 500ms for interactive chat. &lt; 2s is tolerable. &gt; 5s and users think it’s broken.</p>

<p><strong>Root causes when high:</strong></p>
<ul>
  <li>Long prompts (expected — prefill scales with length)</li>
  <li>GPU under heavy load, requests queuing</li>
  <li>Insufficient prefill capacity (in P/D disaggregated setups)</li>
</ul>

<hr />

<h3 id="itl--inter-token-latency-aka-tpot">ITL — Inter-Token Latency (aka TPOT)</h3>

<p><strong>Definition:</strong> Average time between consecutive output tokens during decode. Inverse of token generation speed.</p>

<p><strong>What it captures:</strong> Decode throughput per active request. Memory bandwidth is the primary lever.</p>

<p><strong>PromQL:</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>histogram_quantile(0.95,
  sum(rate(vllm:time_per_output_token_seconds_bucket[2m])) by (le)
)
</code></pre></div></div>

<p><strong>SLO guidance:</strong> &lt; 30ms is fast, streaming feels smooth. &gt; 100ms and you notice the typewriter effect.</p>

<p><strong>Root causes when high:</strong></p>
<ul>
  <li>Too many concurrent requests (KV cache reads competing)</li>
  <li>Large model + small GPU memory bandwidth</li>
  <li>KV cache approaching capacity</li>
</ul>

<hr />

<h3 id="kv-cache-hit-ratio">KV Cache Hit Ratio</h3>

<p><strong>Definition:</strong> Fraction of prompt tokens whose KV vectors were served from prefix cache vs recomputed.</p>

<p><strong>What it captures:</strong> Effectiveness of prefix caching. High hit ratio = lower TTFT for repeated system prompts.</p>

<p><strong>PromQL:</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>vllm:gpu_prefix_cache_hit_rate
</code></pre></div></div>

<p><strong>Target:</strong> &gt; 0.5 for most chat workloads with consistent system prompts. Near 0 means your prompts are fully unique (batch processing, no shared prefix).</p>

<hr />

<h3 id="kv-cache-usage">KV Cache Usage</h3>

<p><strong>Definition:</strong> Fraction of total KV cache capacity currently occupied.</p>

<p><strong>PromQL:</strong></p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>vllm:gpu_cache_usage_perc
</code></pre></div></div>

<p><strong>Alert threshold:</strong> &gt; 0.85. At 0.9+, vLLM starts evicting in-progress requests, causing recomputation and latency spikes. At 1.0, new requests queue entirely.</p>

<hr />

<h3 id="scaling-strategy-by-traffic-shape">Scaling Strategy by Traffic Shape</h3>

<p>This is where the SRE work actually lives:</p>

<table>
  <thead>
    <tr>
      <th>Traffic Pattern</th>
      <th>Symptom</th>
      <th>Action</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Many short prompts, many users</td>
      <td>TTFT fine, ITL rising, KV cache full</td>
      <td>Scale out (more replicas), or reduce <code class="language-plaintext highlighter-rouge">max_model_len</code></td>
    </tr>
    <tr>
      <td>Few long prompts, long outputs</td>
      <td>TTFT high, ITL high, KV cache full fast</td>
      <td>Larger GPU memory, or P/D disaggregation</td>
    </tr>
    <tr>
      <td>Bursty traffic, idle baseline</td>
      <td>P99 TTFT spikes, P50 fine</td>
      <td>Horizontal scaling + request queuing</td>
    </tr>
    <tr>
      <td>Consistent system prompt across requests</td>
      <td>High TTFT on cold start only</td>
      <td>Enable prefix caching (already default in vLLM &gt;= 0.4)</td>
    </tr>
    <tr>
      <td>Mixed short and long context</td>
      <td>Unpredictable KV usage</td>
      <td>Set per-request <code class="language-plaintext highlighter-rouge">max_tokens</code> limits strictly</td>
    </tr>
  </tbody>
</table>

<p><strong>The strategic insight:</strong> short prompt, many concurrent users → <strong>decode is the bottleneck</strong>, optimize for memory bandwidth and parallelism across requests. Long context, few users → <strong>prefill is the bottleneck</strong> and KV cache pressure is the constraint; P/D disaggregation helps by giving prefill its own GPU.</p>

<hr />

<h2 id="14-where-does-the-time-actually-go">14. Where Does the Time Actually Go?</h2>

<p>After running these experiments on real hardware, here’s the honest answer:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Typical inference request (short prompt, moderate load):

Tokenization:          ~0.5ms   (CPU, negligible)
Embedding lookup:      ~1ms     (GPU memory read)
Prefill (32 layers):   ~40ms    (GPU compute, scales with prompt length)
First token decode:    ~3-5ms   (GPU memory read, KV cache write)
...each subsequent token: ~3-5ms

Total TTFT:            ~45ms under no load
Total TTFT at p95:     300-500ms under load (queuing dominates)
</code></pre></div></div>

<p><strong>Where load makes it worse:</strong></p>

<ol>
  <li><strong>Queuing before prefill starts</strong>: your request sits behind other long prefills. TTFT absorbs the entire queue wait.</li>
  <li><strong>KV cache contention during decode</strong>: more concurrent requests = more KV cache reads per step = higher ITL for everyone.</li>
  <li><strong>Memory fragmentation</strong>: without PagedAttention, wasted KV cache blocks reduce effective concurrency.</li>
</ol>

<p><strong>What’s predicted to improve this:</strong></p>

<ul>
  <li><strong>Speculative decoding</strong>: a small “draft” model generates 4-5 tokens speculatively; the large model verifies them in one forward pass. If accepted, 4 tokens for the price of ~1.5 forward passes. Reduces ITL dramatically under low concurrency, hurts at high concurrency (wasted draft compute).</li>
  <li><strong>P/D disaggregation</strong>: dedicated prefill GPUs handle prompt processing, dedicated decode GPUs handle generation. Eliminates the resource contention between phases. Requires fast interconnect (NVLink or RDMA) for KV transfer.</li>
  <li><strong>Flash Attention 3</strong>: kernel-level optimization that keeps attention computation in SRAM longer, reducing HBM reads. Already default in vLLM on H100.</li>
</ul>

<hr />

<h2 id="15-the-inference-engines-worth-knowing">15. The Inference Engines Worth Knowing</h2>

<p>Not all inference engines are created equal, and the right tool depends on your constraints.</p>

<figure style="max-width:800px;margin:2rem auto;text-align:center;">
  <img src="/assets/images/llm-inference/llm-inference-engine-comparison.png" alt="LLM Inference Engines Comparison" style="width:100%;" />
</figure>

<h3 id="ollama">Ollama</h3>
<ul>
  <li><strong>Origin:</strong> Open source, community</li>
  <li><strong>Strengths:</strong> Dead simple to run, supports Apple Silicon natively, GGUF format</li>
  <li><strong>Weaknesses:</strong> No continuous batching (as of early 2025), worse throughput under concurrent load</li>
  <li><strong>When to use:</strong> Local development, single-user experiments, quick model testing</li>
  <li><strong>When not to use:</strong> Serving more than one user concurrently</li>
  <li><strong>GitHub:</strong> <a href="https://github.com/ollama/ollama">github.com/ollama/ollama</a></li>
</ul>

<h3 id="vllm">vLLM</h3>
<ul>
  <li><strong>Origin:</strong> UC Berkeley, now a major open-source project with significant industry contributors</li>
  <li><strong>Strengths:</strong> PagedAttention, continuous batching, Prometheus metrics out of the box, P/D disaggregation via llm-d</li>
  <li><strong>Weaknesses:</strong> More complex setup, CUDA-first (Apple Silicon support via vllm-metal is experimental)</li>
  <li><strong>When to use:</strong> Production serving, multi-user, research with real load</li>
  <li><strong>When not to use:</strong> You just want to run one model locally and don’t want to think about it</li>
  <li><strong>GitHub:</strong> <a href="https://github.com/vllm-project/vllm">github.com/vllm-project/vllm</a></li>
</ul>

<h3 id="tgi-text-generation-inference">TGI (Text Generation Inference)</h3>
<ul>
  <li><strong>Origin:</strong> HuggingFace</li>
  <li><strong>Strengths:</strong> First-class support for new HuggingFace models, FlashAttention, tensor parallelism</li>
  <li><strong>Weaknesses:</strong> Slower to adopt innovations than vLLM, somewhat opinionated config</li>
  <li><strong>When to use:</strong> You’re already in the HuggingFace ecosystem and want good defaults</li>
  <li><strong>GitHub:</strong> <a href="https://github.com/huggingface/text-generation-inference">github.com/huggingface/text-generation-inference</a></li>
</ul>

<h3 id="tensorrt-llm">TensorRT-LLM</h3>
<ul>
  <li><strong>Origin:</strong> NVIDIA</li>
  <li><strong>Strengths:</strong> Best possible performance on NVIDIA hardware, optimized kernels, inference graph compilation</li>
  <li><strong>Weaknesses:</strong> NVIDIA-only, complex setup, compiled engines are model+hardware-specific (can’t move them)</li>
  <li><strong>When to use:</strong> You have a fixed model, fixed NVIDIA hardware, and need maximum performance</li>
  <li><strong>When not to use:</strong> You want flexibility, you’re running experiments, or you don’t own your hardware</li>
  <li><strong>GitHub:</strong> <a href="https://github.com/NVIDIA/TensorRT-LLM">github.com/NVIDIA/TensorRT-LLM</a></li>
</ul>

<h3 id="the-meta--research-options">The META / Research Options</h3>
<ul>
  <li><strong>llama.cpp</strong> — <a href="https://github.com/ggerganov/llama.cpp">github.com/ggerganov/llama.cpp</a>: The CPU-first runtime. Runs quantized models on CPU, reasonably fast, the ancestor of Ollama.</li>
  <li><strong>ExLlamaV2</strong> — <a href="https://github.com/turboderp-org/exllamav2">github.com/turboderp-org/exllamav2</a>: Highly optimized for RTX GPUs specifically. EXL2 quantization format is more sophisticated than GPTQ or AWQ — per-layer bit allocation instead of uniform quantization.</li>
  <li><strong>MLC-LLM</strong> — <a href="https://github.com/mlc-ai/mlc-llm">github.com/mlc-ai/mlc-llm</a>: Cross-platform (compiles to CUDA, Metal, Vulkan). Good for deploying to diverse hardware.</li>
</ul>

<hr />

<h2 id="16-the-languages-behind-it-all">16. The Languages Behind It All</h2>

<p>If you open the source code of a modern inference engine, here’s what you’ll find:</p>

<p><strong>Python</strong>: The top layer. API server, request handling, scheduling logic, metric collection. vLLM’s scheduler and OpenAI-compatible API are Python. This is also where most bugs live.</p>

<p><strong>CUDA (C++)</strong>: The performance layer. Attention kernels, memory management, GPU operations. Flash Attention is CUDA. PagedAttention’s physical block management is CUDA. If Python is the restaurant, CUDA is the kitchen.</p>

<p><strong>Rust</strong>: The fast utilities layer. HuggingFace’s <code class="language-plaintext highlighter-rouge">tokenizers</code> library is Rust — because tokenizing millions of requests fast matters. NIXL (the KV cache transfer layer in llm-d) has Rust/C++ components. Growing presence in inference tooling.</p>

<p><strong>Go</strong>: The orchestration layer. Kubernetes operators, control plane tooling, health checks, routing logic. If you’re writing infrastructure <em>around</em> inference — operators, routers, schedulers — Go is where the work happens.</p>

<p><strong>C++ (non-CUDA)</strong>: llama.cpp is pure C++ with optional CUDA/Metal backends. TensorRT-LLM has heavy C++ in the engine.</p>

<p><strong>For SREs/DevOps:</strong> You live in Python (scripts, load tests), Go (operators, K8s controllers), and YAML (unfortunately). CUDA is worth being able to <em>read</em> — not write, just understand why a kernel fusion matters and what a grid/block size means. Rust fluency is a genuine differentiator if you want to contribute upstream.</p>

<hr />

<h2 id="17-what-cpu-vs-memory-intensive-means-summarized">17. What CPU vs. Memory Intensive Means, Summarized</h2>

<p>After all of the above, here’s the clean summary of which hardware resource each step stresses:</p>

<table>
  <thead>
    <tr>
      <th>Step</th>
      <th>Hardware</th>
      <th>Why</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Tokenization</td>
      <td>CPU</td>
      <td>Text processing, hash lookups, BPE merges</td>
    </tr>
    <tr>
      <td>Embedding lookup</td>
      <td>GPU memory</td>
      <td>Row lookup in large weight matrix</td>
    </tr>
    <tr>
      <td>Positional encoding</td>
      <td>GPU compute</td>
      <td>Fast arithmetic, small matrix</td>
    </tr>
    <tr>
      <td>Prefill (attention + FFN)</td>
      <td>GPU compute</td>
      <td>Matrix multiplications, all tokens in parallel</td>
    </tr>
    <tr>
      <td>Decode attention</td>
      <td>GPU memory bandwidth</td>
      <td>KV cache read per step, memory-bound</td>
    </tr>
    <tr>
      <td>Decode FFN</td>
      <td>GPU compute</td>
      <td>Weight matrix multiply per step</td>
    </tr>
    <tr>
      <td>KV cache management</td>
      <td>GPU memory</td>
      <td>Allocation, paging, eviction</td>
    </tr>
    <tr>
      <td>Sampling (logit → token)</td>
      <td>GPU compute</td>
      <td>Softmax + sample, fast</td>
    </tr>
  </tbody>
</table>

<p>The pattern: <strong>prefill is compute-bound, decode is memory-bound</strong>. This is the fundamental tension that all inference optimization — P/D disaggregation, speculative decoding, PagedAttention, quantization — is ultimately trying to resolve.</p>

<hr />

<h2 id="18-what-an-sre-actually-needs-to-know">18. What an SRE Actually Needs to Know</h2>

<p>You don’t need to write CUDA. You don’t need to derive the attention formula. But you do need a mental model that lets you answer these questions in production:</p>

<ul>
  <li><strong>Why is TTFT high?</strong> → Prefill bottleneck or queuing. Long prompts? GPU saturated?</li>
  <li><strong>Why is ITL degrading?</strong> → KV cache pressure. Too many concurrent requests. Memory bandwidth saturating.</li>
  <li><strong>Why did the GPU OOM?</strong> → KV cache exhausted. Too many long requests, no eviction headroom.</li>
  <li><strong>Why is throughput low?</strong> → No continuous batching. Poor concurrency config. Batch size too small.</li>
  <li><strong>Why does prefix caching not help?</strong> → System prompt is changing per-request. Fix the app layer.</li>
  <li><strong>Which GPU should I buy?</strong> → For inference: memory bandwidth matters more than FLOP count. H100 &gt; A100 for serving not because of compute but because of HBM3 bandwidth.</li>
  <li><strong>Why is quantization worth it?</strong> → A 4-bit model serves faster (decode is memory-bound, smaller tensors = faster reads) and fits on cheaper hardware. Quality loss is usually acceptable.</li>
</ul>

<p>The mental model in one sentence: <strong>LLM inference is split between a compute-hungry prefill phase and a memory-hungry decode phase, connected by a KV cache that is your most critical resource to manage.</strong></p>

<p>Everything else — PagedAttention, continuous batching, P/D disaggregation, speculative decoding, quantization — is an optimization layered on top of that fundamental structure.</p>

<hr />

<h2 id="the-summary-a-mental-model-for-production">The Summary: A Mental Model for Production</h2>

<p>If you’ve made it this far, you’ve realized that LLM inference isn’t magic; it’s a measurable, optimizable systems engineering challenge. The execution pipeline breaks down into three distinct phases with unique bottlenecks: <strong>Tokenization</strong> (CPU-bound), <strong>Prefill</strong> (GPU compute-bound), and <strong>Decode</strong> (GPU memory-bound).</p>

<p>To help you debug that 2:00 AM latency spike, here is the final synthesis of the mechanics we’ve covered:</p>

<h3 id="the-war-room-reference-table">The “War Room” Reference Table</h3>

<table>
  <thead>
    <tr>
      <th style="text-align: left">Phase</th>
      <th style="text-align: left">Core Mechanism</th>
      <th style="text-align: left">Primary Bottleneck</th>
      <th style="text-align: left">SRE Metric to Watch</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left"><strong>Ingress</strong></td>
      <td style="text-align: left"><strong>Tokenization</strong></td>
      <td style="text-align: left">CPU / Latency</td>
      <td style="text-align: left">Tokenizer Latency</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Processing</strong></td>
      <td style="text-align: left"><strong>Prefill</strong></td>
      <td style="text-align: left">GPU Compute (FLOPs)</td>
      <td style="text-align: left"><strong>TTFT</strong> (Time to First Token)</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>Generation</strong></td>
      <td style="text-align: left"><strong>Decode Loop</strong></td>
      <td style="text-align: left">Memory Bandwidth</td>
      <td style="text-align: left"><strong>ITL/TPOT</strong> (Inter-token Latency)</td>
    </tr>
    <tr>
      <td style="text-align: left"><strong>State</strong></td>
      <td style="text-align: left"><strong>KV Cache</strong></td>
      <td style="text-align: left">VRAM Capacity</td>
      <td style="text-align: left">Cache Usage % &amp; Hit Rate</td>
    </tr>
  </tbody>
</table>

<h3 id="the-final-principles-your-tldr">The Final Principles (Your TL;DR)</h3>

<ul>
  <li><strong>Weights are Static Data</strong>: The GGUF or Safetensors file is essentially a massive, math-heavy lookup table. You aren’t executing code; you are performing matrix math against frozen numbers.</li>
  <li><strong>Quantization is a Free Lunch</strong>: Lowering precision (e.g., to INT4) reduces tensor size, which directly loosens the memory bottleneck during decoding, often improving throughput by <strong>20-40%</strong>.</li>
  <li><strong>The KV Cache is Your Most Precious Resource</strong>: It prevents $O(N^2)$ recomputation by storing token state. Managing this via <strong>PagedAttention</strong> and <strong>Prefix Caching</strong> is what separates a toy demo from a production-grade service.</li>
  <li><strong>Attention is the Relationship Engine</strong>: It uses Queries, Keys, and Values to calculate which tokens matter to each other. It’s why the model understands context, but it’s also why memory pressure scales with your prompt length.</li>
  <li><strong>Continuous Batching is the Efficiency Unlock</strong>: By batching at the “word” level rather than the “request” level, you keep the GPU busy even when individual users have wildly different response lengths.</li>
</ul>

<p>The ultimate constraint in scaling model serving isn’t raw compute power, but memory bandwidth and the strict management of the KV Cache. By understanding the mechanical realities beneath the hood—like PagedAttention, continuous batching, and quantization—infrastructure engineers can move past guesswork and systematically optimize for the metrics that dictate user experience: <strong>TTFT</strong> and <strong>TPOT</strong>.</p>

<h2 id="conclusion-the-field-is-moving-the-fundamentals-arent">Conclusion: The Field Is Moving, The Fundamentals Aren’t</h2>

<p>The implementation details of LLM inference in 2025/2026 are changing fast enough to give you whiplash, but the underlying physics of the problem haven’t moved an inch. Prefill will always be compute-hungry. Decode will always be memory-hungry. Attention will always scale quadratically with context length unless someone breaks the math. These aren’t framework quirks; they are the mechanical realities of how transformers work.</p>

<p>Transitioning to LLMOps requires a fundamental shift in how we manage system state. We are no longer scaling stateless pods; we are actively managing distributed GPU memory. The engineering headroom to optimize this is enormous, and the landscape is shifting rapidly:</p>

<ul>
  <li>
    <p><strong>The model size curve is bending:</strong> Smaller, highly-optimized 7B models are now punching above the weight of older 70B giants, distributing the inference problem across a much wider variety of hardware.</p>
  </li>
  <li>
    <p><strong>The memory bottleneck is softening:</strong> Bleeding-edge KV cache compression techniques are reducing per-token memory footprint from kilobytes down to a handful of bytes, loosening the strict constraints of the decode phase.</p>
  </li>
  <li>
    <p><strong>The edge is becoming viable:</strong> As inference pushes to mobile NPUs and WebGPU, serving a 3B parameter model starts to look less like a Kubernetes workload and more like a firmware binary.</p>
  </li>
</ul>

<p>Yet, the operational reality remains unchanged. When a model is in production and serving real traffic, someone has to know why TTFT spiked at 2am, why the KV cache hit 95% utilization under Tuesday’s load, and why the p99 ITL is three times the p50.</p>

<p>Mastering the mechanics of inference separates a fragile AI prototype from a resilient production platform. The inference stack will keep evolving. The need for a rigorous mental model to debug it won’t.</p>

<hr />

<p><strong>Next up:</strong> In the next post, we’ll take these first principles and see how they dictate the architectural trade-offs behind the major inference engines: Ollama, vLLM, TGI, and TensorRT-LLM.</p>

<hr />

<p><em>I’m an infrastructure engineer with 11+ years in distributed systems (D-Wave, Enbala, MasterCard, Cisco), currently going deep on LLM serving and inference optimization. This series is grounded in hands-on experiments — Mac Mini to Lambda Labs GH200 to RunPod A100 clusters. I write what I actually learned, including the parts that didn’t work.</em></p>

<p><em>Find me on GitHub: <a href="https://github.com/kraghavan">kraghavan</a></em></p>

<p><em>Find me on Linkedin: <a href="https://linkedin.com/in/karthikaraghavan">Karthika Raghavan</a></em></p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm-infrastructure" /><category term="inference" /><category term="vllm" /><category term="inference" /><category term="ttft" /><category term="tpot" /><category term="kv-cache" /><category term="attention" /><category term="tokenization" /><category term="sre" /><category term="transformers" /><summary type="html"><![CDATA[An Engineer's annotated tour through what actually happens when you hit send — from bytes to tokens to embeddings to attention to the word your model finally spits out. No skipped steps. No "and then magic happens."]]></summary></entry><entry><title type="html">Schema Travels Architecture</title><link href="https://kraghavan.ca/2026/04/06/schema-travels-architecture.html" rel="alternate" type="text/html" title="Schema Travels Architecture" /><published>2026-04-06T00:00:00+00:00</published><updated>2026-04-06T00:00:00+00:00</updated><id>https://kraghavan.ca/2026/04/06/schema-travels-architecture</id><content type="html" xml:base="https://kraghavan.ca/2026/04/06/schema-travels-architecture.html"><![CDATA[<h1 id="translating-sql-to-nosql-architecture-deep-dive">Translating SQL to NoSQL: Architecture Deep-Dive</h1>

<p><em>Part 1 of 2: Design decisions, trade-offs, and algorithms behind schema-travels</em></p>

<hr />

<h2 id="why-i-built-this">Why I Built This</h2>

<p>Migrating from a relational SQL database to a NoSQL paradigm is notoriously difficult to automate. Every DBA has war stories: the naive migration that turned a 3-table JOIN into three round trips, or the “just flatten everything” approach that created 50GB documents.</p>

<p>The problem I chose: <strong>How do you automate a context-aware SQL-to-NoSQL schema migration without relying on raw, hallucination-prone LLM outputs?</strong></p>

<p>The key insight: algorithms are excellent at graph clustering; LLMs are not. But algorithms lack business context. So I built a dual-engine system where deterministic algorithms do the math, and an LLM acts as a reviewing Principal Architect—bounded, structured, and unable to hallucinate schemas into existence.</p>

<p>This post walks through every architectural decision in <a href="https://github.com/kraghavan/schema-travels">schema-travels</a>, including the trade-offs I considered and the bugs that taught me humility.</p>

<hr />

<h2 id="system-overview">System Overview</h2>

<h3 id="architecture-diagram-generated-by-notebooklm">Architecture Diagram (generated by NotebookLM)</h3>
<p><img src="/assets/images/schema-travels/schema-travels-architecture.png" alt="Schema Travels Architecture" />
<em>The Schema Travels architecture: multi-provider AI review with specialized MongoDB and DynamoDB migration flows</em></p>

<h3 id="components">Components</h3>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>┌──────────────────────────────────────────────────────────────────────────────┐
│                              schema-travels                                  │
│                                                                              │
│  ┌────────────────────────────────────────────────────────────────────────┐  │
│  │                        Deterministic Engine                            │  │
│  │                                                                        │  │
│  │  ┌─────────────┐    ┌─────────────┐    ┌─────────────┐                 │  │
│  │  │  SQL Log    │    │  Access     │    │  Target     │                 │  │
│  │  │  Parser     │───▶│  Pattern    │───▶│  Schema     │                 │  │
│  │  │             │    │  Analyzer   │    │  Designer   │                 │  │
│  │  │ • PostgreSQL│    │             │    │             │                 │  │
│  │  │ • MySQL     │    │ • HotJoins  │    │ • MongoDB   │                 │  │
│  │  │ • 10K+ qps  │    │ • Mutations │    │ • DynamoDB  │                 │  │
│  │  └─────────────┘    │ • Co-access │    │ • Union-Find│                 │  │
│  │                     └─────────────┘    └──────┬──────┘                 │  │
│  └───────────────────────────────────────────────┼────────────────────────┘  │
│                                                  │                           │
│                                    Algorithmic Draft (JSON)                  │
│                                                  │                           │
│  ┌───────────────────────────────────────────────▼────────────────────────┐  │
│  │                         LLM Review Layer                               │  │
│  │                                                                        │  │
│  │  ┌─────────────┐    ┌─────────────┐    ┌─────────────┐                 │  │
│  │  │  Provider   │    │  Advisor    │    │  Pydantic   │                 │  │
│  │  │  Protocol   │───▶│  (Reviewer) │───▶│  Validator  │                 │  │
│  │  │             │    │             │    │             │                 │  │
│  │  │ • Claude    │    │ • Critique  │    │ • Bounded   │                 │  │
│  │  │ • GPT-4o    │    │ • Refine    │    │ • Typed     │                 │  │
│  │  │ • Gemini    │    │ • Explain   │    │ • No schema │                 │  │
│  │  │ • Ollama    │    │             │    │   invention │                 │  │
│  │  └─────────────┘    └─────────────┘    └──────┬──────┘                 │  │
│  └───────────────────────────────────────────────┼────────────────────────┘  │
│                                                  │                           │
│                                    Reviewed Design (JSON)                    │
│                                                  │                           │
│  ┌───────────────────────────────────────────────▼────────────────────────┐  │
│  │                         Output &amp; Caching                               │  │
│  │                                                                        │  │
│  │  ┌─────────────┐    ┌─────────────┐    ┌─────────────┐                 │  │
│  │  │  Cache      │    │  Terraform  │    │  NoSQL      │                 │  │
│  │  │  Manager    │    │  Generator  │    │  Workbench  │                 │  │
│  │  │             │    │             │    │  Export     │                 │  │
│  │  │ • Strict    │    │ • .tf files │    │             │                 │  │
│  │  │ • Relaxed   │    │ • GSI defs  │    │ • Import    │                 │  │
│  │  │ • ~3s hits  │    │ • Capacity  │    │   ready     │                 │  │
│  │  └─────────────┘    └─────────────┘    └─────────────┘                 │  │
│  └────────────────────────────────────────────────────────────────────────┘  │
└──────────────────────────────────────────────────────────────────────────────┘
</code></pre></div></div>

<hr />

<h2 id="component-1-the-statistical-ground-truth">Component 1: The Statistical Ground Truth</h2>

<h3 id="the-problem">The Problem</h3>

<p>You can design a relational database in a vacuum using normal forms. You <em>cannot</em> design a NoSQL database without knowing the access patterns.</p>

<p>Feeding an LLM just the <code class="language-plaintext highlighter-rouge">CREATE TABLE</code> statements produces generic, unoptimized schemas. It’s like asking an architect to design a house without knowing if it’s for a family of four or a fraternity.</p>

<h3 id="my-solution-log-based-pattern-analysis">My Solution: Log-Based Pattern Analysis</h3>

<p>Before any AI is invoked, the pipeline ingests thousands of raw SQL queries (up to 10K in my benchmarks). Two analyzers extract the structural signals:</p>

<table>
  <thead>
    <tr>
      <th>Analyzer</th>
      <th>What It Measures</th>
      <th>Why It Matters</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>HotJoinAnalyzer</strong></td>
      <td>Co-access frequency between tables</td>
      <td>If <code class="language-plaintext highlighter-rouge">orders</code> and <code class="language-plaintext highlighter-rouge">order_items</code> are JOINed in 95% of queries, they belong together</td>
    </tr>
    <tr>
      <td><strong>MutationAnalyzer</strong></td>
      <td>Write patterns per table</td>
      <td>High-mutation tables need different caching strategies</td>
    </tr>
  </tbody>
</table>

<p>The output is a weighted co-access matrix—essentially a graph where edge weights represent how often two tables appear together in queries.</p>

<h3 id="design-decision-static-schema-vs-log-perusal">Design Decision: Static Schema vs. Log Perusal</h3>

<p><strong>Trade-off considered:</strong></p>

<table>
  <thead>
    <tr>
      <th>Approach</th>
      <th>Speed</th>
      <th>Accuracy</th>
      <th>Limitations</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Static schema only</td>
      <td>&lt;1s</td>
      <td>~60%</td>
      <td>Misses actual usage patterns</td>
    </tr>
    <tr>
      <td>Log perusal</td>
      <td>5-30s</td>
      <td>~90%</td>
      <td>Requires query logs</td>
    </tr>
  </tbody>
</table>

<p><strong>My choice:</strong> Log perusal is non-negotiable. A schema where <code class="language-plaintext highlighter-rouge">users</code> and <code class="language-plaintext highlighter-rouge">user_preferences</code> are separate tables tells you nothing about whether they’re accessed together. Query logs tell you everything.</p>

<p><strong>Lesson learned:</strong> Early versions didn’t weight by query frequency. A table JOINed once in a rare admin query got the same weight as one JOINed 10,000 times per hour. Adding frequency weighting dramatically improved recommendations.</p>

<hr />

<h2 id="component-2-mongodb-document-designer">Component 2: MongoDB Document Designer</h2>

<h3 id="the-problem-1">The Problem</h3>

<p>MongoDB’s core design question: <strong>Embed or Reference?</strong></p>

<table>
  <thead>
    <tr>
      <th>Strategy</th>
      <th>When to Use</th>
      <th>Risk</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Embed</strong></td>
      <td>High co-access, bounded growth</td>
      <td>Document bloat (16MB limit)</td>
    </tr>
    <tr>
      <td><strong>Reference</strong></td>
      <td>Independent access, unbounded growth</td>
      <td>N+1 query patterns</td>
    </tr>
  </tbody>
</table>

<p>Getting this wrong is expensive. Embed a million reviews inside a product document and MongoDB will hate you. Reference user addresses that are always fetched with the user and you’ve recreated SQL’s JOIN problem.</p>

<h3 id="my-solution-confidence-weighted-decisions">My Solution: Confidence-Weighted Decisions</h3>

<p>The algorithm takes the co-access score from Component 1 and calculates a <strong>Confidence Score</strong> for each relationship:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Confidence = (co_access_weight × access_factor) + (bounded_growth × stability_factor)
</code></pre></div></div>

<ul>
  <li><strong>≥ 0.85</strong>: Strong embed recommendation (green in output)</li>
  <li><strong>0.70-0.85</strong>: Moderate confidence (yellow)</li>
  <li><strong>&lt; 0.70</strong>: Reference or needs human review (red)</li>
</ul>

<p>The color-coding isn’t cosmetic—it tells developers where to focus their review time.</p>

<h3 id="design-decision-schema-only-vs-schema--queries">Design Decision: Schema Only vs. Schema + Queries</h3>

<p><strong>Trade-off considered:</strong></p>

<table>
  <thead>
    <tr>
      <th>Approach</th>
      <th>Output</th>
      <th>Developer Effort</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Schema only</td>
      <td>JSON structure</td>
      <td>Developer writes queries</td>
    </tr>
    <tr>
      <td>Schema + queries</td>
      <td>Structure + aggregation pipelines</td>
      <td>Copy-paste ready</td>
    </tr>
  </tbody>
</table>

<p><strong>My choice:</strong> Generate both. For MongoDB, <code class="language-plaintext highlighter-rouge">schema-travels</code> outputs the exact aggregation pipelines or <code class="language-plaintext highlighter-rouge">findOne</code> queries that replace the original SQL JOINs.</p>

<p><strong>Why this matters:</strong> A schema migration isn’t done when you have a new data model. It’s done when your application code works. Giving developers the target schema <em>and</em> the code to query it cuts migration time significantly.</p>

<hr />

<h2 id="component-3-dynamodb-paradigm-shift">Component 3: DynamoDB Paradigm Shift</h2>

<h3 id="the-problem-2">The Problem</h3>

<p>DynamoDB isn’t just “MongoDB but AWS.” It’s a fundamentally different paradigm:</p>

<table>
  <thead>
    <tr>
      <th>MongoDB</th>
      <th>DynamoDB</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Flexible queries</td>
      <td>Pre-defined access patterns</td>
    </tr>
    <tr>
      <td>Indexes added later</td>
      <td>GSIs designed upfront</td>
    </tr>
    <tr>
      <td>Nested documents</td>
      <td>Flat, wide-column design</td>
    </tr>
    <tr>
      <td>Query anything</td>
      <td>Query only what you planned for</td>
    </tr>
  </tbody>
</table>

<p>The infamous “Single-Table Design” pattern—where multiple entity types share one table with carefully crafted partition and sort keys—is powerful but alien to SQL developers.</p>

<h3 id="my-solution-union-find-access-clustering">My Solution: Union-Find Access Clustering</h3>

<p>This is where the computer science degree earns its keep. The <code class="language-plaintext highlighter-rouge">DynamoDBDesigner</code> uses a <strong>Union-Find (Disjoint Set Union)</strong> algorithm to cluster SQL tables based on their relationship weights.</p>

<p><strong>How it works:</strong></p>

<ol>
  <li>Each SQL table starts as its own cluster</li>
  <li>For each edge (co-access relationship) above a threshold weight:
    <ul>
      <li>Find the cluster roots of both tables</li>
      <li>Union them if they’re frequently accessed together</li>
    </ul>
  </li>
  <li>Result: clusters of tables that should share a DynamoDB table</li>
</ol>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Input: users, orders, order_items, products, reviews
       
Co-access weights:
  users ←→ orders:      0.92  (high)
  orders ←→ order_items: 0.95  (high)
  products ←→ reviews:   0.45  (low)
  
After Union-Find:
  Cluster 1: {users, orders, order_items}  → Single-table candidate
  Cluster 2: {products}                     → Separate table
  Cluster 3: {reviews}                      → Separate table
</code></pre></div></div>

<p>The algorithm then generates PK/SK patterns and GSI candidates for each cluster.</p>

<h3 id="design-decision-llm-generation-vs-algorithmic-draft">Design Decision: LLM Generation vs. Algorithmic Draft</h3>

<p><strong>Trade-off considered:</strong></p>

<table>
  <thead>
    <tr>
      <th>Approach</th>
      <th>Consistency</th>
      <th>Quality</th>
      <th>Hallucination Risk</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>LLM generates schema</td>
      <td>Low</td>
      <td>Variable</td>
      <td>High</td>
    </tr>
    <tr>
      <td>Algorithm generates, LLM reviews</td>
      <td>High</td>
      <td>Consistent</td>
      <td>Low</td>
    </tr>
  </tbody>
</table>

<p><strong>My choice:</strong> Algorithms generate the draft; LLMs review it.</p>

<p>Union-Find is deterministic—same input always produces the same clusters. LLMs are not. Asking an LLM to “design a DynamoDB schema” is asking for creative writing. Asking it to “review this algorithmic draft and flag issues” is asking for structured critique.</p>

<p><strong>Lesson learned:</strong> Early versions let the LLM suggest entity renames during review. This broke the mapping back to the algorithmic draft, causing cryptic “Entity Not Found” errors. Now the validator explicitly forbids schema invention.</p>

<hr />

<h2 id="component-4-the-multi-provider-llm-layer">Component 4: The Multi-Provider LLM Layer</h2>

<h3 id="the-problem-3">The Problem</h3>

<p>I needed LLM review capabilities but didn’t want to be locked into one provider. Different providers have different strengths, costs, and availability.</p>

<h3 id="my-solution-protocol-oriented-provider-abstraction">My Solution: Protocol-Oriented Provider Abstraction</h3>

<p>The <code class="language-plaintext highlighter-rouge">LLMProvider</code> protocol defines what any provider must support:</p>

<table>
  <thead>
    <tr>
      <th>Method</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">complete()</code></td>
      <td>Generate a response</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">supports_json_mode</code></td>
      <td>Whether native JSON mode is available</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">name</code>, <code class="language-plaintext highlighter-rouge">model</code></td>
      <td>Provider identification</td>
    </tr>
  </tbody>
</table>

<p>Any class implementing this protocol works with the Advisor:</p>

<table>
  <thead>
    <tr>
      <th>Provider</th>
      <th>Default Model</th>
      <th>Cost</th>
      <th>Best For</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Claude</strong></td>
      <td>claude-sonnet-4</td>
      <td>~$3/1M</td>
      <td>Complex reasoning</td>
    </tr>
    <tr>
      <td><strong>OpenAI</strong></td>
      <td>gpt-4o-mini</td>
      <td>~$0.15/1M</td>
      <td>Cost-effective structured output</td>
    </tr>
    <tr>
      <td><strong>Gemini</strong></td>
      <td>gemini-2.0-flash</td>
      <td>~$0.10/1M</td>
      <td>Speed</td>
    </tr>
    <tr>
      <td><strong>Ollama</strong></td>
      <td>llama3.1:8b</td>
      <td>Free</td>
      <td>Privacy, offline</td>
    </tr>
  </tbody>
</table>

<h3 id="design-decision-agentic-generation-vs-agentic-review">Design Decision: Agentic Generation vs. Agentic Review</h3>

<p><strong>Trade-off considered:</strong></p>

<table>
  <thead>
    <tr>
      <th>Approach</th>
      <th>LLM Role</th>
      <th>Control</th>
      <th>Consistency</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Agentic generation</td>
      <td>Creator</td>
      <td>Low</td>
      <td>Low</td>
    </tr>
    <tr>
      <td>Agentic review</td>
      <td>Critic</td>
      <td>High</td>
      <td>High</td>
    </tr>
  </tbody>
</table>

<p><strong>My choice:</strong> The LLM is a <em>reviewer</em>, not a <em>creator</em>.</p>

<p>The prompt never says “design a schema.” It says “here is the algorithmic draft—critique it.” The LLM can flag issues:</p>

<blockquote>
  <p>“The algorithm suggested Single-Table Design here, but this Partition Key has low cardinality and will cause a hot partition. Consider adding a write-sharding suffix.”</p>
</blockquote>

<p>But it cannot invent new tables or fundamentally restructure the design. Pydantic validators enforce this boundary.</p>

<hr />

<h2 id="component-5-caching--infrastructure-output">Component 5: Caching &amp; Infrastructure Output</h2>

<h3 id="the-problem-4">The Problem</h3>

<p>LLM calls are slow (2-30 seconds) and expensive. Re-analyzing the same schema during CI/CD is wasteful.</p>

<h3 id="my-solution-dual-mode-hashing">My Solution: Dual-Mode Hashing</h3>

<table>
  <thead>
    <tr>
      <th>Mode</th>
      <th>Hash Includes</th>
      <th>Use Case</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Relaxed</strong></td>
      <td>Schema structure, log patterns</td>
      <td>Development iteration</td>
    </tr>
    <tr>
      <td><strong>Strict</strong></td>
      <td>Full payload including metadata</td>
      <td>Production, testing</td>
    </tr>
  </tbody>
</table>

<p><strong>Relaxed mode</strong> hashes only the structural elements. Minor metadata changes hit the cache, dropping a 25-second pipeline to ~3 seconds.</p>

<p><strong>Strict mode</strong> requires cryptographic match of the entire input. Essential for reproducible E2E testing.</p>

<h3 id="closing-the-loop-infrastructure-as-code">Closing the Loop: Infrastructure as Code</h3>

<p>A schema design on paper is useless if it can’t be deployed. The pipeline terminates by generating actual IaC:</p>

<table>
  <thead>
    <tr>
      <th>Output</th>
      <th>Format</th>
      <th>Use</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Terraform</strong></td>
      <td><code class="language-plaintext highlighter-rouge">.tf</code></td>
      <td><code class="language-plaintext highlighter-rouge">terraform apply</code> ready</td>
    </tr>
    <tr>
      <td><strong>NoSQL Workbench</strong></td>
      <td><code class="language-plaintext highlighter-rouge">.json</code></td>
      <td>Visual modeling, data import</td>
    </tr>
  </tbody>
</table>

<p>The Terraform output includes table definitions, GSI configurations, and capacity settings. Not a template—actual runnable infrastructure.</p>

<p><strong>Lesson learned:</strong> My Terraform formatter had a subtle bug—it generated <code class="language-plaintext highlighter-rouge">$${table_name}</code> instead of <code class="language-plaintext highlighter-rouge">"${table_name}"</code> in some edge cases. The E2E test matrix caught this because it validated the <code class="language-plaintext highlighter-rouge">.tf</code> files could be parsed by Terraform’s HCL parser.</p>

<hr />

<h2 id="what-id-do-differently">What I’d Do Differently</h2>

<h3 id="1-dynamodb-query-translation-from-day-one">1. DynamoDB Query Translation from Day One</h3>

<p>The MongoDB module translates SQL JOINs to aggregation pipelines. The DynamoDB module only outputs schemas—no Boto3 query code. This asymmetry bothers me.</p>

<p>Generating <code class="language-plaintext highlighter-rouge">dynamodb.query(KeyConditionExpression=...)</code> calls alongside the schema would make the DynamoDB path as developer-friendly as MongoDB.</p>

<h3 id="2-stricter-entity-name-validation">2. Stricter Entity Name Validation</h3>

<p>The LLM occasionally renames entities during review (“I’ll call this <code class="language-plaintext highlighter-rouge">CustomerOrders</code> instead of <code class="language-plaintext highlighter-rouge">user_orders</code>”). This breaks the mapping back to the algorithmic draft.</p>

<p>The fix was a Pydantic validator that rejects any entity name not in the original input. But I should have anticipated this—LLMs love to be “helpful” by renaming things.</p>

<h3 id="3-cache-key-design-up-front">3. Cache Key Design Up Front</h3>

<p>I added the <code class="language-plaintext highlighter-rouge">dynamodb_mode</code> parameter to cache keys late. This meant cached results from <code class="language-plaintext highlighter-rouge">auto</code> mode were incorrectly served for <code class="language-plaintext highlighter-rouge">single</code> mode requests.</p>

<p>Cache key design should happen during architecture, not debugging.</p>

<hr />

<h2 id="the-proof-what-actually-happened">The Proof: What Actually Happened</h2>

<p>Let me show you what this architecture produces in practice. I ran the E2E test matrix across 4 providers × 2 targets on a 42-table e-commerce schema with 100 synthetic queries:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>┌─────────────┬──────────────┬──────────────┐
│  Provider   │   MongoDB    │   DynamoDB   │
├─────────────┼──────────────┼──────────────┤
│ claude      │ ✓ PASS       │ ✓ PASS       │
│ openai      │ ✓ PASS       │ ✓ PASS       │
│ gemini      │ ✓ PASS       │ ✓ PASS       │
│ ollama      │ ✓ PASS       │ ✓ PASS       │
└─────────────┴──────────────┴──────────────┘
Total: 8 tests | Passed: 8 | Failed: 0
</code></pre></div></div>

<p><strong>What the numbers tell us:</strong></p>

<table>
  <thead>
    <tr>
      <th>Provider</th>
      <th>DynamoDB Design</th>
      <th>Confidence</th>
      <th>GSIs Generated</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Claude</strong></td>
      <td>single_table</td>
      <td>85%</td>
      <td>4 (overloaded)</td>
    </tr>
    <tr>
      <td><strong>OpenAI</strong></td>
      <td>single_table</td>
      <td>77.5%</td>
      <td>5 (descriptive names)</td>
    </tr>
    <tr>
      <td><strong>Gemini</strong></td>
      <td>single_table</td>
      <td>75%</td>
      <td>5 (direct attributes)</td>
    </tr>
    <tr>
      <td><strong>Ollama</strong> (local)</td>
      <td>multi_table</td>
      <td>80%</td>
      <td>per-table</td>
    </tr>
  </tbody>
</table>

<p>Here’s the insight that makes this architecture work: <strong>the algorithmic clusters are identical across all providers</strong>. Products had 82 accesses. Users had 54. Orders had 32. The Union-Find algorithm doesn’t care which LLM you’re using—it produces the same deterministic foundation every time.</p>

<p>But the <em>interpretation</em> differs. Three cloud providers looked at the same clusters and said “single-table design with GSI overloading.” The local model (gemma3:4b running on my Mac Mini) said “multi-table is fine here.”</p>

<p>Just like every architecture review I’ve ever been in—except this one finished in 22 seconds and nobody rage-quit to “work from home.”</p>

<p>Who’s right? Honestly, both approaches are defensible for this workload. The point isn’t that one answer is correct—it’s that the AI is <em>reviewing</em> a solid algorithmic foundation, not hallucinating schemas from scratch.</p>

<p><strong>MongoDB showed similar patterns:</strong></p>

<p>The Claude review of MongoDB produced 12 recommendations with confidence-scored decisions:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">orders → order_items</code>: <strong>EMBED</strong> (95% confidence) — “Perfect co-access, always accessed together”</li>
  <li><code class="language-plaintext highlighter-rouge">products → reviews</code>: <strong>REFERENCE</strong> (90% confidence) — “Unbounded growth, popular products can have thousands of reviews”</li>
  <li><code class="language-plaintext highlighter-rouge">users → addresses</code>: <strong>EMBED</strong> (85% confidence) — “High co-access, addresses typically accessed with user profile”</li>
</ul>

<p>That 90% confidence REFERENCE decision for reviews? That’s exactly the kind of nuanced judgment that makes NoSQL design hard. The algorithm detected high co-access, but the AI correctly identified the unbounded growth risk that would blow past MongoDB’s 16MB document limit.</p>

<p>More than 40 tables migrated, zero DBAs traumatized. Though if your schema has more foreign keys than a hotel concierge, maybe grab coffee first.</p>

<hr />

<h2 id="the-bigger-picture-what-this-actually-solves">The Bigger Picture: What This Actually Solves</h2>

<p><strong>The Old Way:</strong> A senior engineer spends 2-3 weeks analyzing query logs, drawing ER diagrams on whiteboards, debating embed-vs-reference decisions in meetings, and manually translating that into DynamoDB access patterns. Then they write Terraform by hand and pray they didn’t miss a GSI.</p>

<p><strong>The New Way:</strong> Feed the tool your PostgreSQL logs and schema. Get a reviewed, confidence-scored design with deployable Terraform in 22 seconds. Spend those 2-3 weeks on the parts that actually require human judgment—data migration strategy, application refactoring, rollback planning.</p>

<p>This isn’t about replacing engineers. It’s about replacing the <em>tedious parts</em> of engineering so we can focus on the <em>interesting parts</em>.</p>

<h3 id="the-core-innovation-bounded-ai">The Core Innovation: Bounded AI</h3>

<p>The fundamental insight behind this architecture is that <strong>LLMs should critique, not create</strong>.</p>

<table>
  <thead>
    <tr>
      <th>Approach</th>
      <th>What Can Go Wrong</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>“LLM, design me a schema”</td>
      <td>Hallucinated tables, inconsistent naming, unbounded creativity</td>
    </tr>
    <tr>
      <td>“LLM, review this algorithmic draft”</td>
      <td>Bounded feedback, structured output, deterministic baseline</td>
    </tr>
  </tbody>
</table>

<p>By forcing the AI into a reviewer role with Pydantic-enforced boundaries, we get the benefits of LLM intelligence (business context, heuristic reasoning, natural language explanations) without the chaos of unbounded generation.</p>

<p>This pattern—<strong>algorithmic draft + bounded LLM review</strong>—is applicable far beyond schema migration. It’s how I’d approach any problem where you need AI assistance but can’t afford hallucinations.</p>

<hr />

<h2 id="whats-next-graphrag-for-enterprise-scale">What’s Next: GraphRAG for Enterprise Scale</h2>

<p>The current implementation handles schemas with 10-50 tables comfortably. But what happens when you’re migrating a legacy enterprise system with 500 tables? 1,000?</p>

<p>At that scale, the co-access matrix becomes unwieldy, the visualization becomes spaghetti, and even Union-Find starts to strain under the combinatorial explosion.</p>

<p><strong>The roadmap:</strong> GraphRAG-powered schema analysis.</p>

<p>The idea is straightforward:</p>
<ol>
  <li><strong>Store the schema graph</strong> in a proper graph database (NetworkX + SQLite for now, Neo4j for enterprise)</li>
  <li><strong>Embed table semantics</strong> using sentence transformers</li>
  <li><strong>Query with natural language</strong>: “Show me all tables related to order fulfillment” or “Which clusters would be affected if we split the users table?”</li>
</ol>

<p>This transforms schema-travels from a migration tool into a <strong>schema intelligence platform</strong>. Instead of processing everything at once, you can explore the graph, ask questions, and migrate incrementally—cluster by cluster, bounded by what your team can absorb.</p>

<hr />

<h2 id="coming-up-part-2">Coming Up: Part 2</h2>

<p>In Part 2, we’ll dive deeper into the E2E test results:</p>

<ul>
  <li><strong>Latency breakdown</strong>: 22 seconds for first run → 3 seconds cached</li>
  <li><strong>Provider comparison</strong>: Why Claude, OpenAI, and Gemini agreed on single-table while Ollama chose multi-table</li>
  <li><strong>The cache drift bug</strong>: How the test matrix caught an inconsistency in DynamoDB Terraform output</li>
  <li><strong>Cost analysis</strong>: Running the full matrix cost less than $0.50 in API calls</li>
</ul>

<hr />

<h2 id="final-thoughts">Final Thoughts</h2>

<p>I’ve been building distributed systems for over a decade. In that time, I’ve seen plenty of “AI-powered” tools that are really just prompt wrappers—impressive demos that fall apart the moment you need reproducibility.</p>

<p><code class="language-plaintext highlighter-rouge">schema-travels</code> is my answer to the question: <em>How do you build AI-assisted tooling that a principal engineer would actually sign off on?</em></p>

<p>The answer, it turns out, is the same principle that makes distributed systems reliable: <strong>don’t trust any single component</strong>. Algorithms provide the deterministic foundation. LLMs provide the intelligence. Pydantic provides the guardrails. Caching provides the economics. And an 8-test E2E matrix provides the confidence that it all actually works.</p>

<p>The schema migration problem was just the vehicle. The real artifact is an architecture pattern for building AI tools that are auditable, reproducible, and won’t make your on-call engineer cry at 3am.</p>

<hr />

<p><strong>GitHub:</strong> <a href="https://github.com/kraghavan/schema-travels">github.com/kraghavan/schema-travels</a></p>

<p><em>Questions, feedback, or war stories from your own migrations? Connect with me on <a href="https://linkedin.com/in/karthikaraghavan">LinkedIn</a>.</em></p>]]></content><author><name>Karthika Raghavan</name></author><summary type="html"><![CDATA[Translating SQL to NoSQL: Architecture Deep-Dive]]></summary></entry><entry><title type="html">Building a Privacy-Aware LLM Gateway: Benchmarking Results</title><link href="https://kraghavan.ca/llm/infrastructure/benchmarks/2026/03/21/inference-sentinel-benchmarks2.html" rel="alternate" type="text/html" title="Building a Privacy-Aware LLM Gateway: Benchmarking Results" /><published>2026-03-21T00:00:00+00:00</published><updated>2026-03-21T00:00:00+00:00</updated><id>https://kraghavan.ca/llm/infrastructure/benchmarks/2026/03/21/inference-sentinel-benchmarks2</id><content type="html" xml:base="https://kraghavan.ca/llm/infrastructure/benchmarks/2026/03/21/inference-sentinel-benchmarks2.html"><![CDATA[<h1 id="building-a-privacy-aware-llm-gateway-benchmarking-results">Building a Privacy-Aware LLM Gateway: Benchmarking Results</h1>

<p><em>Part 2 of 2: Empirical evaluation of classification accuracy, routing performance, and cost attribution</em></p>

<hr />

<h2 id="abstract">Abstract</h2>

<p>In <a href="/llm/infrastructure/smart%20gateway/python/2026/03/20/inference-sentinel-architecture.html">Part 1</a>, I described the architecture of inference-sentinel, a privacy-aware LLM routing gateway. This post presents empirical results from five experiments evaluating classification accuracy, routing latency, cost efficiency, controller effectiveness, and session stickiness.</p>

<p><strong>Key findings:</strong></p>
<ul>
  <li>The hybrid classifier achieves 97.5% accuracy with 0.16ms mean latency, though a systematic failure mode in Tier 3 detection reveals the importance of enabling NER for healthcare identifiers</li>
  <li>Local inference introduces a 10× latency penalty compared to cloud backends, a fundamental trade-off for privacy preservation</li>
  <li>Routing 47.5% of traffic locally yields 68.6% cost savings, with an unexpected finding that Google’s Gemini is 44× cheaper per request than Anthropic’s Claude</li>
  <li>The closed-loop controller correctly withheld recommendations when local-cloud quality divergence exceeded thresholds</li>
</ul>

<hr />

<h2 id="1-experimental-setup">1. Experimental Setup</h2>

<h3 id="11-hardware-configuration">1.1 Hardware Configuration</h3>

<table>
  <thead>
    <tr>
      <th>Component</th>
      <th>Specification</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Gateway Host</strong></td>
      <td>Docker container (inference-sentinel)</td>
    </tr>
    <tr>
      <td><strong>Local Inference</strong></td>
      <td>Apple Mac Mini M4, 16GB unified memory</td>
    </tr>
    <tr>
      <td><strong>Local Models</strong></td>
      <td>Ollama serving gemma3:4b and mistral (round-robin)</td>
    </tr>
    <tr>
      <td><strong>Cloud Backends</strong></td>
      <td>Claude Sonnet 4 (Anthropic), Gemini 2.0 Flash (Google)</td>
    </tr>
  </tbody>
</table>

<h3 id="12-dataset">1.2 Dataset</h3>

<p>I constructed a synthetic evaluation dataset of 200 prompts with known ground-truth privacy labels, balanced across four tiers:</p>

<table>
  <thead>
    <tr>
      <th>Tier</th>
      <th>Label</th>
      <th>Count</th>
      <th>Example Patterns</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>0</td>
      <td>PUBLIC</td>
      <td>50</td>
      <td>General knowledge questions</td>
    </tr>
    <tr>
      <td>1</td>
      <td>INTERNAL</td>
      <td>50</td>
      <td>Project codes, internal URLs</td>
    </tr>
    <tr>
      <td>2</td>
      <td>CONFIDENTIAL</td>
      <td>50</td>
      <td>Email addresses, phone numbers</td>
    </tr>
    <tr>
      <td>3</td>
      <td>RESTRICTED</td>
      <td>50</td>
      <td>SSNs, credit cards, health records</td>
    </tr>
  </tbody>
</table>

<p>The balanced design enables per-class precision/recall analysis without class imbalance confounds.</p>

<h3 id="13-experimental-protocol">1.3 Experimental Protocol</h3>

<p>Each experiment was run independently with the gateway in a fresh state. Metrics were collected via Prometheus and exported to JSON for analysis. All experiments used the same dataset to enable cross-experiment comparison.</p>

<hr />

<h2 id="2-experiment-1-classification-accuracy">2. Experiment 1: Classification Accuracy</h2>

<p><strong>Research Question:</strong> How accurately does the hybrid classifier assign privacy tiers, and what are the failure modes?</p>

<h3 id="21-results">2.1 Results</h3>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Overall Accuracy</strong></td>
      <td>97.5% (195/200)</td>
    </tr>
    <tr>
      <td><strong>Mean Classification Time</strong></td>
      <td>0.16ms</td>
    </tr>
    <tr>
      <td><strong>Misclassifications</strong></td>
      <td>5</td>
    </tr>
  </tbody>
</table>

<p><img src="/assets/images/inference-sentinel/tier_metrics.png" alt="Classification Metrics by Tier" />
<em>Figure 1: Per-tier precision, recall, and F1 scores. The dashed line indicates the 95% threshold. Tier 3 recall (90%) falls below threshold due to undetected health insurance identifiers.</em></p>

<h3 id="22-per-tier-analysis">2.2 Per-Tier Analysis</h3>

<table>
  <thead>
    <tr>
      <th>Tier</th>
      <th>Precision</th>
      <th>Recall</th>
      <th>F1</th>
      <th>TP</th>
      <th>FP</th>
      <th>FN</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>0 (PUBLIC)</td>
      <td>90.9%</td>
      <td>100%</td>
      <td>95.2%</td>
      <td>50</td>
      <td>5</td>
      <td>0</td>
    </tr>
    <tr>
      <td>1 (INTERNAL)</td>
      <td>100%</td>
      <td>100%</td>
      <td>100%</td>
      <td>50</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td>2 (CONFIDENTIAL)</td>
      <td>100%</td>
      <td>100%</td>
      <td>100%</td>
      <td>50</td>
      <td>0</td>
      <td>0</td>
    </tr>
    <tr>
      <td>3 (RESTRICTED)</td>
      <td>100%</td>
      <td>90%</td>
      <td>94.7%</td>
      <td>45</td>
      <td>0</td>
      <td>5</td>
    </tr>
  </tbody>
</table>

<p>The asymmetry between Tier 0 and Tier 3 is notable: Tier 0 has 5 false positives (items incorrectly classified as PUBLIC), while Tier 3 has 5 false negatives (restricted items missed). These are the same 5 samples — Tier 3 prompts misclassified as Tier 0.</p>

<p><img src="/assets/images/inference-sentinel/confusion_matrix.png" alt="Confusion Matrix" />
<em>Figure 2: Confusion matrix showing classification performance. Off-diagonal entries appear only in the Tier 3→Tier 0 cell, indicating a systematic failure mode rather than random errors.</em></p>

<h3 id="23-error-analysis">2.3 Error Analysis</h3>

<p>All five misclassifications share a common pattern:</p>

<table>
  <thead>
    <tr>
      <th>Prompt ID</th>
      <th>Text Preview</th>
      <th>Expected</th>
      <th>Predicted</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>tier3_277eb0aa</td>
      <td>“Patient Alyssa Nelson, health insurance ID: FRJ508021882, prescribed Lisinopril 10mg daily.”</td>
      <td>Tier 3</td>
      <td>Tier 0</td>
    </tr>
    <tr>
      <td>tier3_67f1698c</td>
      <td>“Patient Joseph Hill, health insurance ID: WRY526164289, prescribed Metformin 25mg twice daily.”</td>
      <td>Tier 3</td>
      <td>Tier 0</td>
    </tr>
    <tr>
      <td>tier3_8989c5ab</td>
      <td>“Patient Michael Weaver, health insurance ID: IIP473415078, prescribed Atorvastatin 25mg twice daily.”</td>
      <td>Tier 3</td>
      <td>Tier 0</td>
    </tr>
    <tr>
      <td>tier3_02ed73ce</td>
      <td>“Patient Levi Fowler, health insurance ID: WRV424211872, prescribed Metformin 500mg with meals.”</td>
      <td>Tier 3</td>
      <td>Tier 0</td>
    </tr>
    <tr>
      <td>tier3_bb134f02</td>
      <td>“Patient Brandon Davis, health insurance ID: SIE176051319, prescribed Metformin 10mg daily.”</td>
      <td>Tier 3</td>
      <td>Tier 0</td>
    </tr>
  </tbody>
</table>

<p><strong>Root Cause Analysis:</strong></p>

<p>NER was enabled during this benchmark, yet the <code class="language-plaintext highlighter-rouge">PERSON_NAME</code> entities were not detected. The failures stem from two factors:</p>

<ol>
  <li>
    <p><strong>Missing regex pattern:</strong> The health insurance ID format (<code class="language-plaintext highlighter-rouge">[A-Z]{3}\d{9}</code>) is not covered by existing Tier 3 patterns, which target SSNs (<code class="language-plaintext highlighter-rouge">\d{3}-\d{2}-\d{4}</code>), credit cards (Luhn-valid sequences), and MRN patterns (<code class="language-plaintext highlighter-rouge">MRN:\s*\d+</code>).</p>
  </li>
  <li>
    <p><strong>NER model limitation:</strong> The HuggingFace Transformers BERT model (<code class="language-plaintext highlighter-rouge">dslim/bert-base-NER</code>) failed to recognize the person names in medical record context. The phrase structure “Patient [Name], health insurance ID…” appears to confuse the model — likely because “Patient” is parsed as part of the name span, or the surrounding medical terminology disrupts entity boundary detection.</p>
  </li>
</ol>

<p>Examining the detection results:</p>
<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"expected_entities"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"PERSON_NAME"</span><span class="p">,</span><span class="w"> </span><span class="s2">"PERSON_NAME"</span><span class="p">],</span><span class="w">
  </span><span class="nl">"detected_entities"</span><span class="p">:</span><span class="w"> </span><span class="p">[]</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>The NER model returned zero entities despite clear person names being present. This is a known limitation of lightweight NER models on domain-specific text — medical, legal, and financial documents often require fine-tuned models.</p>

<p><strong>Implication:</strong> The 10% false negative rate on Tier 3 represents exactly the failure mode that matters most in a privacy system — restricted data being classified as public. This is not acceptable for production deployment without remediation.</p>

<h3 id="24-remediation">2.4 Remediation</h3>

<p>Three complementary approaches:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># Fix 1: Add regex pattern for health insurance IDs
</span><span class="n">PATTERNS</span><span class="p">[</span><span class="s">"health_insurance"</span><span class="p">]</span> <span class="o">=</span> <span class="sa">r</span><span class="s">'\b(?:health\s*insurance\s*id|member\s*id)[:\s]*[A-Z]{2,4}\d{8,12}\b'</span>

<span class="c1"># Fix 2: Add "Patient [Name]" pattern for medical contexts
</span><span class="n">PATTERNS</span><span class="p">[</span><span class="s">"patient_name"</span><span class="p">]</span> <span class="o">=</span> <span class="sa">r</span><span class="s">'\bPatient\s+[A-Z][a-z]+\s+[A-Z][a-z]+\b'</span>

<span class="c1"># Fix 3: Consider larger NER model for production
# "accurate" mode uses Jean-Baptiste/roberta-large-ner-english
</span></code></pre></div></div>

<p>The regex-first approach is particularly important here: rather than relying solely on NER for entity detection, adding domain-specific patterns provides a deterministic safety net for known sensitive formats.</p>

<hr />

<h2 id="3-experiment-2-routing-performance">3. Experiment 2: Routing Performance</h2>

<p><strong>Research Question:</strong> What latency overhead does the gateway introduce, and how does local inference compare to cloud?</p>

<h3 id="31-results">3.1 Results</h3>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Total Requests</strong></td>
      <td>200</td>
    </tr>
    <tr>
      <td><strong>Successful</strong></td>
      <td>183 (91.5%)</td>
    </tr>
    <tr>
      <td><strong>Failed</strong></td>
      <td>17 (8.5%)</td>
    </tr>
    <tr>
      <td><strong>Total Duration</strong></td>
      <td>1,421 seconds</td>
    </tr>
    <tr>
      <td><strong>Throughput</strong></td>
      <td>0.13 req/s</td>
    </tr>
  </tbody>
</table>

<p><img src="/assets/images/inference-sentinel/latency_distribution.png" alt="Latency Distribution" />
<em>Figure 3: End-to-end latency distribution showing heavy right tail. The p99 latency (62.9s) is 26× higher than p50 (2.4s), indicating high variance primarily from local inference.</em></p>

<h3 id="32-latency-decomposition">3.2 Latency Decomposition</h3>

<table>
  <thead>
    <tr>
      <th>Component</th>
      <th>Mean Latency</th>
      <th>% of Total</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Classification</td>
      <td>1.47ms</td>
      <td>0.02%</td>
    </tr>
    <tr>
      <td>Routing Decision</td>
      <td>0.22ms</td>
      <td>0.003%</td>
    </tr>
    <tr>
      <td>Inference</td>
      <td>7,729ms</td>
      <td>99.98%</td>
    </tr>
  </tbody>
</table>

<p><strong>Key Finding:</strong> The gateway overhead (classification + routing) is <strong>1.69ms</strong> — effectively invisible relative to inference time. The privacy-aware routing layer does not meaningfully impact end-to-end latency.</p>

<h3 id="33-latency-by-route">3.3 Latency by Route</h3>

<table>
  <thead>
    <tr>
      <th>Route</th>
      <th>Tier</th>
      <th>Count</th>
      <th>Mean</th>
      <th>p50</th>
      <th>p95</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Cloud</td>
      <td>0 (PUBLIC)</td>
      <td>50</td>
      <td>1,669ms</td>
      <td>1,755ms</td>
      <td>2,737ms</td>
    </tr>
    <tr>
      <td>Cloud</td>
      <td>1 (INTERNAL)</td>
      <td>50</td>
      <td>1,571ms</td>
      <td>1,182ms</td>
      <td>3,059ms</td>
    </tr>
    <tr>
      <td>Local</td>
      <td>2 (CONFIDENTIAL)</td>
      <td>42</td>
      <td>15,523ms</td>
      <td>9,949ms</td>
      <td>60,722ms</td>
    </tr>
    <tr>
      <td>Local</td>
      <td>3 (RESTRICTED)</td>
      <td>36</td>
      <td>16,643ms</td>
      <td>5,959ms</td>
      <td>48,418ms</td>
    </tr>
  </tbody>
</table>

<p><strong>The latency trade-off is stark:</strong> Local inference is approximately <strong>10× slower</strong> than cloud. This is the fundamental cost of privacy preservation with consumer-grade hardware.</p>

<h3 id="34-error-analysis">3.4 Error Analysis</h3>

<p>All 17 failures returned <code class="language-plaintext highlighter-rouge">HTTP 503: No healthy local backends available</code>. Examining the error distribution:</p>

<table>
  <thead>
    <tr>
      <th>Tier</th>
      <th>Failures</th>
      <th>Total Requests</th>
      <th>Failure Rate</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Tier 2</td>
      <td>8</td>
      <td>50</td>
      <td>16%</td>
    </tr>
    <tr>
      <td>Tier 3</td>
      <td>9</td>
      <td>50</td>
      <td>18%</td>
    </tr>
    <tr>
      <td>Tier 0-1</td>
      <td>0</td>
      <td>100</td>
      <td>0%</td>
    </tr>
  </tbody>
</table>

<p>Failures occurred exclusively on local-routed traffic. The root cause is <strong>memory pressure</strong>: the Mac Mini M4 with 16GB unified memory struggles to serve concurrent requests across two loaded models (gemma3:4b ≈ 3GB, mistral ≈ 4GB).</p>

<p><strong>Mitigation strategies:</strong></p>
<ol>
  <li>Reduce to single local model (eliminates round-robin memory contention)</li>
  <li>Implement request queuing with backpressure</li>
  <li>Upgrade to 32GB+ RAM for concurrent model serving</li>
  <li>Increase health check timeout to tolerate transient memory pressure</li>
</ol>

<hr />

<h2 id="4-experiment-3-cost-attribution">4. Experiment 3: Cost Attribution</h2>

<p><strong>Research Question:</strong> What are the realized cost savings from local routing, and how do cloud backends compare?</p>

<h3 id="41-results">4.1 Results</h3>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Actual Cost</strong></td>
      <td>$0.0844</td>
    </tr>
    <tr>
      <td><strong>Hypothetical All-Cloud</strong></td>
      <td>$0.2687</td>
    </tr>
    <tr>
      <td><strong>Savings</strong></td>
      <td>$0.1843 (68.6%)</td>
    </tr>
  </tbody>
</table>

<p><img src="/assets/images/inference-sentinel/cost_comparison.png" alt="Cost Attribution" />
<em>Figure 4: Cost comparison showing actual spend vs. hypothetical all-cloud routing. Local routing of Tier 2-3 traffic yields 68.6% cost reduction.</em></p>

<h3 id="42-routing-distribution">4.2 Routing Distribution</h3>

<p><img src="/assets/images/inference-sentinel/routing_distribution.png" alt="Routing Distribution" />
<em>Figure 5: Request distribution by route. 42.6% of requests routed to local inference (privacy-sensitive), 57.4% to cloud (non-sensitive).</em></p>

<table>
  <thead>
    <tr>
      <th>Route</th>
      <th>Requests</th>
      <th>Percentage</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Local</td>
      <td>95</td>
      <td>47.5%</td>
    </tr>
    <tr>
      <td>Cloud</td>
      <td>105</td>
      <td>52.5%</td>
    </tr>
  </tbody>
</table>

<h3 id="43-backend-cost-analysis">4.3 Backend Cost Analysis</h3>

<table>
  <thead>
    <tr>
      <th>Backend</th>
      <th>Requests</th>
      <th>Total Cost</th>
      <th>Cost/Request</th>
      <th>Cost/1K Tokens</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Anthropic (Claude)</td>
      <td>53</td>
      <td>$0.0826</td>
      <td>$0.00156</td>
      <td>$0.0130</td>
    </tr>
    <tr>
      <td>Google (Gemini)</td>
      <td>52</td>
      <td>$0.00185</td>
      <td>$0.0000355</td>
      <td>$0.00036</td>
    </tr>
    <tr>
      <td>Local (Ollama)</td>
      <td>95</td>
      <td>$0.00</td>
      <td>$0.00</td>
      <td>$0.00</td>
    </tr>
  </tbody>
</table>

<p><img src="/assets/images/inference-sentinel/cost_by_backend.png" alt="Cost by Backend" />
<em>Figure 6: Cost distribution by backend. Anthropic accounts for 97.8% of cloud spend despite handling only 50.5% of cloud requests.</em></p>

<p><strong>Unexpected Finding:</strong> Gemini is <strong>44× cheaper per request</strong> than Claude ($0.0000355 vs $0.00156). This suggests a potential optimization: use Gemini as the primary cloud backend for cost-sensitive workloads, reserving Claude for quality-critical requests.</p>

<h3 id="44-cost-by-privacy-tier">4.4 Cost by Privacy Tier</h3>

<table>
  <thead>
    <tr>
      <th>Tier</th>
      <th>Requests</th>
      <th>Routed Local</th>
      <th>Cost</th>
      <th>Savings</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>0 (PUBLIC)</td>
      <td>55</td>
      <td>0</td>
      <td>$0.0400</td>
      <td>$0.0420</td>
    </tr>
    <tr>
      <td>1 (INTERNAL)</td>
      <td>50</td>
      <td>0</td>
      <td>$0.0444</td>
      <td>$0.0248</td>
    </tr>
    <tr>
      <td>2 (CONFIDENTIAL)</td>
      <td>50</td>
      <td>50</td>
      <td>$0.00</td>
      <td>$0.0575</td>
    </tr>
    <tr>
      <td>3 (RESTRICTED)</td>
      <td>45</td>
      <td>45</td>
      <td>$0.00</td>
      <td>$0.0600</td>
    </tr>
  </tbody>
</table>

<p><strong>Tier 2 and Tier 3 traffic incurs zero marginal cost</strong> after hardware investment. For organizations with significant sensitive data volumes, the ROI calculation favors local inference.</p>

<h3 id="45-projected-annual-savings">4.5 Projected Annual Savings</h3>

<p>Extrapolating from observed cost ratios:</p>

<table>
  <thead>
    <tr>
      <th>Daily Volume</th>
      <th>Annual Cloud-Only</th>
      <th>Annual with Sentinel</th>
      <th>Savings</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1,000 req</td>
      <td>$490</td>
      <td>$154</td>
      <td>$336</td>
    </tr>
    <tr>
      <td>10,000 req</td>
      <td>$4,900</td>
      <td>$1,540</td>
      <td>$3,360</td>
    </tr>
    <tr>
      <td>100,000 req</td>
      <td>$49,000</td>
      <td>$15,400</td>
      <td>$33,600</td>
    </tr>
  </tbody>
</table>

<p><strong>Caveat:</strong> These projections assume similar traffic distribution (47.5% local-eligible) and do not account for hardware depreciation, electricity, or operational overhead.</p>

<hr />

<h2 id="5-experiment-4-controller-effectiveness">5. Experiment 4: Controller Effectiveness</h2>

<p><strong>Research Question:</strong> Does the closed-loop controller generate actionable routing recommendations?</p>

<h3 id="51-results">5.1 Results</h3>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Controller Evaluations</strong></td>
      <td>117</td>
    </tr>
    <tr>
      <td><strong>Recommendations Generated</strong></td>
      <td>0</td>
    </tr>
    <tr>
      <td><strong>Drift Detected</strong></td>
      <td>No</td>
    </tr>
  </tbody>
</table>

<h3 id="52-shadow-mode-metrics">5.2 Shadow Mode Metrics</h3>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Shadow Runs</strong></td>
      <td>340</td>
    </tr>
    <tr>
      <td><strong>Successful Comparisons</strong></td>
      <td>275</td>
    </tr>
    <tr>
      <td><strong>Quality Match Rate</strong></td>
      <td>0%</td>
    </tr>
    <tr>
      <td><strong>Cost Savings Tracked</strong></td>
      <td>$0.15</td>
    </tr>
  </tbody>
</table>

<h3 id="53-analysis">5.3 Analysis</h3>

<p>The controller generated zero recommendations because the <strong>quality match rate was 0%</strong>. This means local model responses (gemma3:4b, mistral) were semantically dissimilar enough from cloud responses (Claude, Gemini) that they never crossed the similarity threshold (default: 85%).</p>

<p><strong>This is informative, not a failure.</strong> The controller correctly identified that:</p>
<ol>
  <li>Local models produce qualitatively different outputs than cloud models</li>
  <li>Promoting Tier 0-1 traffic from cloud to local would degrade response quality</li>
  <li>The conservative default (keep on cloud) is appropriate</li>
</ol>

<h3 id="54-interpretation">5.4 Interpretation</h3>

<p>The 0% quality match rate reflects the capability gap between 4B-parameter local models and frontier cloud models. For tasks where approximate answers suffice, lowering the similarity threshold would generate recommendations:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">controller</span><span class="pi">:</span>
  <span class="na">quality_threshold</span><span class="pi">:</span> <span class="m">0.70</span>  <span class="c1"># Down from 0.85</span>
</code></pre></div></div>

<p>However, this requires explicit acceptance of quality trade-offs — a decision the controller correctly defers to human operators.</p>

<hr />

<h2 id="6-experiment-5-session-stickiness">6. Experiment 5: Session Stickiness</h2>

<p><strong>Research Question:</strong> Does the one-way trapdoor correctly lock sessions after PII detection?</p>

<h3 id="61-results">6.1 Results</h3>

<table>
  <thead>
    <tr>
      <th>Metric</th>
      <th>Value</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Sessions Tested</strong></td>
      <td>20</td>
    </tr>
    <tr>
      <td><strong>Requests per Session</strong></td>
      <td>10</td>
    </tr>
    <tr>
      <td><strong>PII Probability</strong></td>
      <td>30%</td>
    </tr>
    <tr>
      <td><strong>Sessions Locked</strong></td>
      <td>0</td>
    </tr>
    <tr>
      <td><strong>Trapdoor Violations</strong></td>
      <td>0</td>
    </tr>
  </tbody>
</table>

<h3 id="62-analysis">6.2 Analysis</h3>

<p><strong>Zero sessions were locked</strong> despite 30% of requests containing PII and session tracking being enabled. Examining the test methodology reveals the issue:</p>

<p>The benchmark harness sent requests with simulated IPs (<code class="language-plaintext highlighter-rouge">10.0.0.0</code> through <code class="language-plaintext highlighter-rouge">10.0.0.19</code>), but the session ID computation may not have properly differentiated these synthetic sources. Additionally, the PII detection failures identified in Experiment 1 (the 5 health insurance records) would have prevented those sessions from locking — if PII isn’t detected, the trapdoor isn’t triggered.</p>

<p><strong>Contributing factors:</strong></p>

<ol>
  <li>
    <p><strong>Classification dependency:</strong> Session locking requires Tier 2+ classification. The 10% Tier 3 false negative rate means some PII-containing requests were classified as Tier 0, preventing session locks.</p>
  </li>
  <li>
    <p><strong>Test methodology:</strong> Requests originated from the same physical host with simulated client IPs. The session ID hashing (<code class="language-plaintext highlighter-rouge">SHA-256(client_ip + daily_salt)</code>) should differentiate these, but the harness may need validation.</p>
  </li>
  <li>
    <p><strong>PII probability vs. detection:</strong> The 30% PII probability applies to dataset generation, but if those PII patterns aren’t detected by the classifier, sessions won’t lock.</p>
  </li>
</ol>

<h3 id="63-what-we-can-validate">6.3 What We Can Validate</h3>

<p>Despite no sessions locking, the core privacy invariant held:</p>

<ul>
  <li><strong>Trapdoor violations: 0</strong> — No request with <em>detected</em> PII ever routed to cloud</li>
  <li><strong>Per-request classification: Functional</strong> — Requests that were classified as sensitive routed locally</li>
</ul>

<p>The gap is between “contains PII” (ground truth) and “detected as PII” (classifier output).</p>

<h3 id="64-required-follow-up">6.4 Required Follow-Up</h3>

<p>A proper session stickiness evaluation requires:</p>

<ol>
  <li><strong>Fix classification first:</strong> Address the Tier 3 detection gaps so PII is actually detected</li>
  <li><strong>Validate session ID generation:</strong> Ensure synthetic client IPs produce distinct session IDs</li>
  <li><strong>Use diverse source IPs:</strong> Run from multiple actual hosts or containers</li>
  <li><strong>Add session state logging:</strong> Instrument the session manager to log state transitions</li>
</ol>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Re-run with verified distinct sessions</span>
python <span class="nt">-m</span> benchmarks.harness <span class="nt">--experiment</span> session <span class="nt">--sessions</span> 20 <span class="nt">--verify-session-ids</span>
</code></pre></div></div>

<p>Expected behavior after fixes:</p>
<ul>
  <li>Sessions should lock when Tier 2+ PII is detected</li>
  <li>Subsequent requests in that session should route to local regardless of content</li>
  <li>Locked session count should approximate <code class="language-plaintext highlighter-rouge">sessions × pii_probability × detection_rate</code></li>
</ul>

<hr />

<h2 id="7-discussion">7. Discussion</h2>

<h3 id="71-principal-findings">7.1 Principal Findings</h3>

<table>
  <thead>
    <tr>
      <th>Hypothesis</th>
      <th>Result</th>
      <th>Verdict</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Classification adds minimal latency</td>
      <td>1.69ms overhead</td>
      <td>✅ Confirmed</td>
    </tr>
    <tr>
      <td>Accuracy exceeds 95%</td>
      <td>97.5% overall</td>
      <td>✅ Confirmed</td>
    </tr>
    <tr>
      <td>Local inference is slower</td>
      <td>10× latency penalty</td>
      <td>⚠️ Confirmed (expected)</td>
    </tr>
    <tr>
      <td>Cost savings are significant</td>
      <td>68.6% reduction</td>
      <td>✅ Confirmed</td>
    </tr>
    <tr>
      <td>Controller generates recommendations</td>
      <td>0 recommendations</td>
      <td>⚠️ By design (quality gap)</td>
    </tr>
    <tr>
      <td>Sessions lock on PII detection</td>
      <td>0 sessions locked</td>
      <td>⚠️ Requires improved test methodology</td>
    </tr>
  </tbody>
</table>

<h3 id="72-limitations">7.2 Limitations</h3>

<p><strong>Dataset Size:</strong> 200 prompts is sufficient for detecting large effect sizes but underpowered for rare failure modes. A production evaluation should use 10,000+ samples.</p>

<p><strong>Synthetic Data:</strong> The evaluation dataset was synthetically generated with known patterns. Real-world PII distributions may differ, particularly for domain-specific identifiers.</p>

<p><strong>Single Hardware Configuration:</strong> Results reflect a specific hardware setup (M4 Mac Mini, 16GB). Performance characteristics will vary with different local inference hardware.</p>

<p><strong>NER Model Limitations:</strong> The lightweight BERT NER model (<code class="language-plaintext highlighter-rouge">dslim/bert-base-NER</code>, “fast” mode) failed to detect person names in medical record contexts, revealing domain-specific NER gaps that require either fine-tuning or larger models like RoBERTa.</p>

<p><strong>Session Test Methodology:</strong> The session stickiness experiment used simulated IPs from a single host, and classification failures prevented some PII-containing requests from triggering session locks.</p>

<h3 id="73-threats-to-validity">7.3 Threats to Validity</h3>

<p><strong>Internal Validity:</strong> The 17 routing failures (8.5%) due to memory pressure may have biased latency statistics toward successful (potentially faster) requests.</p>

<p><strong>External Validity:</strong> The balanced tier distribution (25% per tier) does not reflect production traffic, which is typically skewed toward Tier 0-1.</p>

<p><strong>Construct Validity:</strong> Semantic similarity (cosine distance on embeddings) may not capture task-specific quality dimensions relevant to specific use cases.</p>

<hr />

<h2 id="8-conclusion">8. Conclusion</h2>

<h3 id="81-summary-of-contributions">8.1 Summary of Contributions</h3>

<p>This work presents <strong>inference-sentinel</strong>, a privacy-aware LLM routing gateway that addresses a gap in the current MLOps landscape: the ability to enforce data residency policies at inference time without sacrificing developer experience.</p>

<p><strong>What we built:</strong></p>

<table>
  <thead>
    <tr>
      <th>Component</th>
      <th>Contribution</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Hybrid Classifier</strong></td>
      <td>Two-stage pipeline (regex + NER) achieving 97.5% accuracy at 0.16ms latency — fast enough for real-time routing decisions</td>
    </tr>
    <tr>
      <td><strong>Session Manager</strong></td>
      <td>One-way trapdoor state machine ensuring PII-containing sessions are permanently locked to local inference, with cryptographic session ID hashing</td>
    </tr>
    <tr>
      <td><strong>Context Handoff</strong></td>
      <td>Rolling buffer mechanism preserving conversation continuity during mid-session cloud→local transitions, with optional PII scrubbing</td>
    </tr>
    <tr>
      <td><strong>Backend Manager</strong></td>
      <td>Pluggable selection strategies (priority, round-robin, latency-aware) with automatic health checking and failover</td>
    </tr>
    <tr>
      <td><strong>Shadow Mode</strong></td>
      <td>Non-blocking A/B comparison framework collecting quality metrics without impacting user-facing latency</td>
    </tr>
    <tr>
      <td><strong>Closed-Loop Controller</strong></td>
      <td>Rule-based recommendation engine that observes traffic patterns and suggests routing policy adjustments</td>
    </tr>
    <tr>
      <td><strong>Observability Stack</strong></td>
      <td>Full OpenTelemetry integration with Prometheus metrics, Grafana dashboards, and structured logging</td>
    </tr>
  </tbody>
</table>

<p><strong>What the benchmarks revealed:</strong></p>

<p>The evaluation across 200 synthetic prompts demonstrated that privacy-aware routing is feasible with sub-2ms overhead. The 68.6% cost savings from local routing validates the economic case, while the 10× latency penalty quantifies the privacy-performance trade-off. The systematic Tier 3 failures (health insurance IDs) highlight the importance of domain-specific pattern engineering and robust NER model selection — even with NER enabled, lightweight models may miss entities in specialized contexts.</p>

<p>This is not a production-ready system — it is a <strong>proof of architecture</strong> demonstrating that the building blocks exist and compose correctly.</p>

<hr />

<h3 id="82-future-work">8.2 Future Work</h3>

<h4 id="821-scaling-the-evaluation">8.2.1 Scaling the Evaluation</h4>

<p>The current benchmark uses 200 prompts — sufficient for detecting large effects but underpowered for tail behavior analysis. Future work should include:</p>

<table>
  <thead>
    <tr>
      <th>Benchmark</th>
      <th>Purpose</th>
      <th>Target</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Extended classification</strong></td>
      <td>Rare pattern detection, edge cases</td>
      <td>1,000+ prompts</td>
    </tr>
    <tr>
      <td><strong>Load testing</strong></td>
      <td>Concurrent request handling, memory pressure</td>
      <td>100 req/s sustained</td>
    </tr>
    <tr>
      <td><strong>Adversarial evaluation</strong></td>
      <td>Evasion attempts, prompt injection</td>
      <td>Red team dataset</td>
    </tr>
    <tr>
      <td><strong>Longitudinal study</strong></td>
      <td>Drift detection over weeks of traffic</td>
      <td>Production deployment</td>
    </tr>
  </tbody>
</table>

<p>Statistical power analysis suggests n=1,000+ is required to detect failure modes occurring at &lt;1% frequency with 95% confidence.</p>

<h4 id="822-improving-ner-accuracy">8.2.2 Improving NER Accuracy</h4>

<p>The current implementation uses HuggingFace Transformers with <code class="language-plaintext highlighter-rouge">dslim/bert-base-NER</code> (“fast” mode, ~400MB) for named entity recognition. Several directions merit exploration:</p>

<table>
  <thead>
    <tr>
      <th>Model</th>
      <th>Size</th>
      <th>Tradeoff</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">dslim/bert-base-NER</code> (fast)</td>
      <td>~400MB</td>
      <td>Current default, good speed, limited domain coverage</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Jean-Baptiste/roberta-large-ner-english</code> (accurate)</td>
      <td>~1.3GB</td>
      <td>Higher accuracy, 3-5× latency</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">Davlan/bert-base-multilingual-cased-ner-hrl</code> (multilingual)</td>
      <td>~700MB</td>
      <td>Multi-language support</td>
    </tr>
    <tr>
      <td><strong>Fine-tuned NER</strong></td>
      <td>Variable</td>
      <td>Domain-specific entities (PHI, financial identifiers)</td>
    </tr>
    <tr>
      <td><strong>Presidio</strong></td>
      <td>N/A</td>
      <td>Microsoft’s PII detection library, rule + ML hybrid</td>
    </tr>
    <tr>
      <td><strong>GLiNER</strong></td>
      <td>200MB</td>
      <td>Zero-shot NER, no fine-tuning required</td>
    </tr>
  </tbody>
</table>

<p>The optimal choice depends on latency budget. For sub-50ms classification, the “fast” BERT model with expanded regex patterns may outperform larger models. For offline batch classification, RoBERTa-based NER (“accurate” mode) is viable.</p>

<h4 id="823-gpu-accelerated-local-inference">8.2.3 GPU-Accelerated Local Inference</h4>

<p>The current setup runs local models on Apple Silicon (M4 Mac Mini) using Metal acceleration via Ollama. While sufficient for development and low-throughput production, this architecture has limitations:</p>

<table>
  <thead>
    <tr>
      <th>Constraint</th>
      <th>Current</th>
      <th>With GPU</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>VRAM</td>
      <td>16GB unified</td>
      <td>24-80GB dedicated</td>
    </tr>
    <tr>
      <td>Concurrent models</td>
      <td>1-2 (memory pressure)</td>
      <td>3-4+</td>
    </tr>
    <tr>
      <td>Throughput</td>
      <td>~0.1 req/s</td>
      <td>1-10 req/s</td>
    </tr>
    <tr>
      <td>Model size</td>
      <td>4-8B parameters</td>
      <td>13-70B parameters</td>
    </tr>
  </tbody>
</table>

<p><strong>GPU deployment options:</strong></p>

<ol>
  <li><strong>NVIDIA GPU server</strong> (RTX 4090, A100): Run vLLM or TGI for high-throughput local inference</li>
  <li><strong>Cloud GPU instances</strong> (but local network): AWS/GCP instances in private VPC, data never leaves controlled infrastructure</li>
  <li><strong>Apple M4 Max/Ultra</strong>: 128GB unified memory enables 70B models with acceptable latency</li>
</ol>

<p>The shadow mode quality metrics would likely improve significantly with larger local models, potentially enabling automatic traffic promotion.</p>

<h4 id="824-kubernetes-deployment">8.2.4 Kubernetes Deployment</h4>

<p>The current Docker Compose stack is suitable for single-node deployment. Production deployment requires:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>┌─────────────────────────────────────────────────────────────┐
│                    Kubernetes Cluster                       │
├─────────────────────────────────────────────────────────────┤
│  ┌─────────────┐  ┌─────────────┐  ┌─────────────┐          │
│  │  Sentinel   │  │  Sentinel   │  │  Sentinel   │          │
│  │  Pod (HPA)  │  │  Pod (HPA)  │  │  Pod (HPA)  │          │
│  └──────┬──────┘  └──────┬──────┘  └──────┬──────┘          │
│         └────────────────┼────────────────┘                 │
│                          ▼                                  │
│                 ┌─────────────────┐                         │
│                 │ Redis (Session  │                         │
│                 │    State)       │                         │
│                 └─────────────────┘                         │
│                          │                                  │
│         ┌────────────────┼────────────────┐                 │
│         ▼                ▼                ▼                 │
│  ┌─────────────┐  ┌─────────────┐  ┌─────────────┐          │
│  │   Ollama    │  │   Ollama    │  │    vLLM     │          │
│  │  (gemma3)   │  │  (mistral)  │  │  (llama3)   │          │
│  │   Node 1    │  │   Node 2    │  │  GPU Node   │          │
│  └─────────────┘  └─────────────┘  └─────────────┘          │
└─────────────────────────────────────────────────────────────┘
</code></pre></div></div>

<p><strong>K8s-specific requirements:</strong></p>
<ul>
  <li><strong>Horizontal Pod Autoscaler (HPA)</strong> for gateway pods based on request rate</li>
  <li><strong>Node affinity</strong> for GPU-accelerated inference pods</li>
  <li><strong>PodDisruptionBudget</strong> ensuring availability during rollouts</li>
  <li><strong>NetworkPolicy</strong> restricting egress to approved cloud endpoints</li>
  <li><strong>ServiceMesh</strong> (Istio/Linkerd) for mTLS between components</li>
</ul>

<h4 id="825-session-state-in-memory-vs-persistent-storage">8.2.5 Session State: In-Memory vs. Persistent Storage</h4>

<p>The current architecture stores session state in an in-memory data structure with TTL-based eviction. This is a deliberate design choice:</p>

<table>
  <thead>
    <tr>
      <th>Approach</th>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>In-memory (current)</strong></td>
      <td>Zero latency, no external dependencies, automatic cleanup</td>
      <td>Lost on restart, single-node only</td>
    </tr>
    <tr>
      <td><strong>Redis</strong></td>
      <td>Distributed, persistent, TTL support native</td>
      <td>Additional infra, latency (+1-2ms), security surface</td>
    </tr>
    <tr>
      <td><strong>PostgreSQL</strong></td>
      <td>ACID, queryable, audit trail</td>
      <td>Highest latency, schema management, backup complexity</td>
    </tr>
  </tbody>
</table>

<p><strong>Why in-memory is defensible:</strong></p>

<ol>
  <li><strong>Session data is ephemeral by design</strong> — 15-minute TTL means losing state on restart is acceptable for most use cases</li>
  <li><strong>Security through ephemerality</strong> — no persistent store means no data to exfiltrate, no backups to secure, no encryption-at-rest requirements</li>
  <li><strong>Operational simplicity</strong> — no Redis cluster to manage, no connection pooling, no failover logic</li>
  <li><strong>Latency</strong> — hash table lookup is O(1) with ~0.001ms; Redis adds network round-trip</li>
</ol>

<p><strong>When to move to Redis:</strong></p>

<ul>
  <li>Multi-pod deployment requiring shared session state</li>
  <li>Session TTL &gt;1 hour (memory pressure)</li>
  <li>Audit requirements mandating session history</li>
  <li>Graceful restart without session loss</li>
</ul>

<p>For the Redis migration path, the interface is already abstracted:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">class</span> <span class="nc">SessionStore</span><span class="p">(</span><span class="n">Protocol</span><span class="p">):</span>
    <span class="k">async</span> <span class="k">def</span> <span class="nf">get</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">session_id</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="n">Optional</span><span class="p">[</span><span class="n">Session</span><span class="p">]:</span> <span class="p">...</span>
    <span class="k">async</span> <span class="k">def</span> <span class="nf">set</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">session_id</span><span class="p">:</span> <span class="nb">str</span><span class="p">,</span> <span class="n">session</span><span class="p">:</span> <span class="n">Session</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span> <span class="p">...</span>
    <span class="k">async</span> <span class="k">def</span> <span class="nf">delete</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">session_id</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span> <span class="p">...</span>

<span class="c1"># Swap implementations without changing business logic
</span><span class="n">store</span> <span class="o">=</span> <span class="n">RedisSessionStore</span><span class="p">(</span><span class="n">redis_url</span><span class="p">)</span> <span class="k">if</span> <span class="n">USE_REDIS</span> <span class="k">else</span> <span class="n">InMemorySessionStore</span><span class="p">()</span>
</code></pre></div></div>

<hr />

<h3 id="83-target-applications">8.3 Target Applications</h3>

<p>inference-sentinel addresses use cases across multiple organizational functions:</p>

<h4 id="healthcare--life-sciences">Healthcare &amp; Life Sciences</h4>

<table>
  <thead>
    <tr>
      <th>Use Case</th>
      <th>Privacy Concern</th>
      <th>Sentinel Solution</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Clinical decision support</td>
      <td>PHI in patient queries</td>
      <td>Tier 3 classification for health records</td>
    </tr>
    <tr>
      <td>Drug interaction lookup</td>
      <td>Patient medication history</td>
      <td>Session locking after first PHI exposure</td>
    </tr>
    <tr>
      <td>Medical transcription</td>
      <td>Dictated patient notes</td>
      <td>Local inference for all transcription</td>
    </tr>
  </tbody>
</table>

<p><strong>Regulatory context:</strong> HIPAA requires technical safeguards for PHI. A gateway that provably routes PHI to local-only inference provides auditable compliance.</p>

<h4 id="financial-services">Financial Services</h4>

<table>
  <thead>
    <tr>
      <th>Use Case</th>
      <th>Privacy Concern</th>
      <th>Sentinel Solution</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Customer service chatbots</td>
      <td>Account numbers, SSNs</td>
      <td>Tier 3 detection with immediate local routing</td>
    </tr>
    <tr>
      <td>Fraud analysis</td>
      <td>Transaction patterns</td>
      <td>Shadow mode for quality validation before local promotion</td>
    </tr>
    <tr>
      <td>Document summarization</td>
      <td>Contracts with PII</td>
      <td>Context handoff preserving conversation flow</td>
    </tr>
  </tbody>
</table>

<p><strong>Regulatory context:</strong> PCI-DSS, SOX, and GLBA impose data handling requirements that a privacy-aware gateway can enforce at the infrastructure layer.</p>

<h4 id="legal--professional-services">Legal &amp; Professional Services</h4>

<table>
  <thead>
    <tr>
      <th>Use Case</th>
      <th>Privacy Concern</th>
      <th>Sentinel Solution</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Contract review</td>
      <td>Client confidential information</td>
      <td>Tier 2+ routing for all legal documents</td>
    </tr>
    <tr>
      <td>Legal research</td>
      <td>Case details, party names</td>
      <td>Session stickiness ensuring full conversation stays local</td>
    </tr>
    <tr>
      <td>E-discovery</td>
      <td>Privileged communications</td>
      <td>Mandatory local inference for attorney-client content</td>
    </tr>
  </tbody>
</table>

<h4 id="enterprise-it--security">Enterprise IT &amp; Security</h4>

<table>
  <thead>
    <tr>
      <th>Use Case</th>
      <th>Privacy Concern</th>
      <th>Sentinel Solution</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Code review assistants</td>
      <td>Proprietary source code</td>
      <td>Internal URL and project code detection (Tier 1)</td>
    </tr>
    <tr>
      <td>Security log analysis</td>
      <td>Infrastructure details, credentials</td>
      <td>API key and credential pattern detection (Tier 3)</td>
    </tr>
    <tr>
      <td>Internal knowledge base Q&amp;A</td>
      <td>Employee PII, org structure</td>
      <td>Configurable routing based on data classification</td>
    </tr>
  </tbody>
</table>

<h4 id="human-resources">Human Resources</h4>

<table>
  <thead>
    <tr>
      <th>Use Case</th>
      <th>Privacy Concern</th>
      <th>Sentinel Solution</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Resume screening</td>
      <td>Candidate PII</td>
      <td>Local inference for all recruitment workflows</td>
    </tr>
    <tr>
      <td>Employee feedback analysis</td>
      <td>Performance data</td>
      <td>Session locking after employee identifier detection</td>
    </tr>
    <tr>
      <td>Compensation benchmarking</td>
      <td>Salary information</td>
      <td>Tier 3 classification for financial PII</td>
    </tr>
  </tbody>
</table>

<hr />

<h3 id="84-broader-impact">8.4 Broader Impact</h3>

<p>The proliferation of LLM-powered applications creates a tension between capability and privacy. Cloud-hosted models offer superior performance but require transmitting potentially sensitive data to third parties. Local models preserve privacy but sacrifice quality and increase operational burden.</p>

<p>inference-sentinel demonstrates that <strong>this is not a binary choice</strong>. By making routing decisions at inference time based on content classification, organizations can:</p>

<ol>
  <li><strong>Use cloud models for the 50%+ of traffic that contains no sensitive data</strong> — capturing the quality and cost benefits</li>
  <li><strong>Enforce local-only inference for genuinely sensitive content</strong> — preserving privacy guarantees</li>
  <li><strong>Measure the trade-off empirically</strong> — shadow mode quantifies exactly what quality you sacrifice for privacy</li>
</ol>

<p>This is a fundamentally different approach from “all cloud” or “all local” architectures. It treats privacy as a first-class routing dimension, alongside latency and cost.</p>

<hr />

<h3 id="85-closing-thoughts">8.5 Closing Thoughts</h3>

<p>Building inference-sentinel during my job search taught me more about LLM infrastructure than any tutorial could. Debugging why Ollama returns 404 (model name mismatch), why Grafana dashboards show “Value” instead of model names (missing metric labels), why round-robin wasn’t working (YAML override precedence) — these are the unglamorous details that separate working systems from prototypes.</p>

<p>The code is open source. The architecture is documented. The benchmarks are reproducible.</p>

<p>If you’re building LLM applications that handle sensitive data, I hope this work provides a useful reference — or at least saves you from repeating my mistakes.</p>

<hr />

<h2 id="appendix-a-raw-data">Appendix A: Raw Data</h2>

<h3 id="a1-classification-misclassifications">A.1 Classification Misclassifications</h3>

<p>All 5 errors follow the pattern:</p>
<ul>
  <li><strong>Input:</strong> Health record with insurance ID format <code class="language-plaintext highlighter-rouge">[A-Z]{3}\d{9}</code></li>
  <li><strong>Expected entities:</strong> <code class="language-plaintext highlighter-rouge">PERSON_NAME</code> (not detected by BERT NER in medical context)</li>
  <li><strong>Detected entities:</strong> <code class="language-plaintext highlighter-rouge">[]</code></li>
</ul>

<h3 id="a2-routing-errors">A.2 Routing Errors</h3>

<p>All 17 errors: <code class="language-plaintext highlighter-rouge">HTTP 503: No healthy local backends available</code></p>

<p>Distribution: 8 Tier 2, 9 Tier 3 (local-routed traffic only)</p>

<h3 id="a3-entity-detection-summary">A.3 Entity Detection Summary</h3>

<table>
  <thead>
    <tr>
      <th>Entity Type</th>
      <th>Count</th>
      <th>Tier Assignment</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>SSN</td>
      <td>24</td>
      <td>3</td>
    </tr>
    <tr>
      <td>Credit Card</td>
      <td>12</td>
      <td>3</td>
    </tr>
    <tr>
      <td>Health Record (MRN)</td>
      <td>6</td>
      <td>3</td>
    </tr>
    <tr>
      <td>Bank Account</td>
      <td>6</td>
      <td>3</td>
    </tr>
    <tr>
      <td>Email</td>
      <td>18</td>
      <td>2</td>
    </tr>
    <tr>
      <td>Phone</td>
      <td>14</td>
      <td>2</td>
    </tr>
    <tr>
      <td>Address</td>
      <td>16</td>
      <td>2</td>
    </tr>
    <tr>
      <td>Internal URL</td>
      <td>28</td>
      <td>1</td>
    </tr>
    <tr>
      <td>Project Code</td>
      <td>12</td>
      <td>1</td>
    </tr>
    <tr>
      <td>Employee ID</td>
      <td>10</td>
      <td>1</td>
    </tr>
  </tbody>
</table>

<hr />

<p><strong>GitHub:</strong> <a href="https://github.com/kraghavan/inference-sentinel">github.com/kraghavan/inference-sentinel</a></p>

<p><em>Questions, feedback, or collaboration ideas? Connect on <a href="https://linkedin.com/in/karthikaraghavan">LinkedIn</a>.</em></p>

<p><strong>Updated Last:</strong> March 24, 2026</p>]]></content><author><name>Karthika Raghavan</name></author><category term="llm" /><category term="infrastructure" /><category term="benchmarks" /><category term="python" /><category term="privacy" /><category term="observability" /><category term="distributed-systems" /><category term="evaluation" /><summary type="html"><![CDATA[Part 2 of 2: Empirical evaluation of classification accuracy, routing performance, and cost attribution — with honest analysis of failure modes]]></summary></entry></feed>